Why is content migration so difficult?

Migrating content from one application to another is a problem that even now, two decades into the digital age, we have no solution for.  Migrating content is often so labour intensive and complex as to be non cost effective.   Any content migration involves compromises and ommissions that result in a significant loss of quality of the metadata that is held about the content being migrated.
Solving the content migration problem is about to become more urgent with the growing popularity of the software-as-a-service (SaaS) variety of cloud computing.  In this model the provider not only provides the software application, they also host your content.  Imagine what would happens if your organisation decided it wanted to change from one SaaS provider to another.  It wants to change from Salesforce to a different SaaS CRM.  Or it wants to go from SharePoint online to Box or Huddle or another collaboration/filesharing offering (or vica-versa).   What do you do?  How do you migrate content from SharePoint Online to Box? They have little in common in terms of how they are architected and what entities they consist of. What is the Box equivalent of a SharePoint content type?
The vendor lock-in problem is very real.  If you can’t migrate the content you are left paying two sets of SaaS subscriptions and managing two SaaS contracts.  If you were leaving because of a breakdown of trust with your original SaaS providor then how happy would you be leaving your content locked up with them on their servers?

Content migration is a problem that affects all organisations, and which affects archivists as much as records managers

The difficulty organisations experience in migrating content from one application to another matters in many situations. It matters when an organisation wants to replace an application with a better application from a different supplier. It matters in a merger/acquisition scenario, when an organisation wants to move the acquired company onto the same applications that the rest of the group are using.
It matters to archivists, because any transfer of electronic records from an organisation to an archive is, to all intents and purposes, a content migration.  I heard the digital preservation consultant Philip Lord say at a conference that the big difference for archives of the electronic world over the paper world is that:

  • in the paper world it was possible for an archive to set up a routine process for transferring hard-copy records that it would expect all bodies contributing records to the archive to adhere to
  • in the electronic world everytime an archive wishes to accept a transfer of records from a new information system it needs to work out a bespoke process for importing that content and its metadata from that particular system into their electronic archive.

Different applications keep their metadata in profoundly different ways

Migration from one application to another is extremely time consuming because you are:

  • mapping from one set of entity types to another. Entities are the types of objects the application can hold (users/groups/documents/records/files/libraries/sites/retention rules etc)
  • mapping from one set of descriptive metadata fields to another
  • mapping from one set of functions to another. Functions are the actions that users can be permitted to perform on entities in the system (for example: create an entity/amend it/rename it/move it/copy it/delete it/attach a retention rule to it/grant or deny access permissions on it)
  • mapping from one set of roles to another. Roles are simply collections of functions, grouped together to make it easier to administrate them. For example in SharePoint the role of ‘member’ of a site collects together the functions a user needs to be able to access a site and view and download content, and to contribute new content to the site, but denies them the functions they would need to administer or change the site itself.

Let us imagine we want to migrate content from application A to application B. Application A has an export function and can export all of its content and metadata into an xml schema. That is good. We go to import the content and metadata into application B. This is where we hit problems.

Application B looks at the audit logs of application A. They contain a listing of events (actions performed by users on entities within the system, at a particular point in time). Each event listed gives you the identity of the user that performed the function, the name of the function they performed, the identity of the entity they performed it on and the date or time at which the event occurred. Application B won’t understand these event listings. It is unlikely to understand the identifiers application A uses to refer to the entities and users. It is unlikely to understand the functions performed because application A has a different set of functions to application B.

Application B looks at the access control lists of application A. Each entity in application A has an access control lists that tells you which users or groups can perform what role in relation to that entity. Application B does not understand those roles, nor does it understand the functions that the roles are made up of. Therefore system B cannot understand the access control lists.

The end result is that application B cannot understand the history of the entities it is importing from application A, and it cannot understand who should be able to access/contribute to/change them.  It is also going to find it difficult to import things like retention rules, descriptive metadata fields, controlled vocabularies.

Migration reduces the quality of metadata

The process of migration is ‘lossy’.  In the world of recorded music it is said that when you move music from one format to another (LP to tape, tape to mp3 etc.) you cannot gain quality, you can only lose it.  When you migrate content from one system to another you cannot gain information about that that content, you can only lose it.  There will be whole swathes of metadata in system A that it will not be cost effective for you to map to conterpart metadata in system B.  You end up migrating content without that metadata, and your knowledge about the content that you hold is poorer as a result.

The fact that content migration is so labour intensive and lossy means that many organsiations opt to leave content in the original application and start from scratch in the new application.  This is a nice easy option, but there are downsides.   It means that the organisation has to maintain the original application for as long as it needs to keep the content that is locked within it.  This means paying the resultant cost of licence fees and support arrangements.   It also means a break in the memory of the organisation.  Users of the new system wishing to look back over previous years will have to go to the old system to view the content.  That is OK for a short period, during which time most colleagues will remember the old system and how to use it.  But as time goes by a larger and larger percentage of colleagues will have no knowledge or memory of the older system and how to use it.

The organisation may mitigate the impact of that by connecting the search capability of system B to the repository of system A.  The results of this are hit and miss.  The search functionality of system B will have been calibrated to the architecture of system B, it will not be calibrated to the architecture of system A.  Yes, it will return results but it will not be able to rank them very well (and you are still having to maintain system A in order that system B can run the search on it).

What can electronic records management specifications do to improve this situation?

The problem of content migration is not specific to records systems, it is a universal problem that affects any organisation wishing to move content from any kind of application to another application.

But it is a problem that is central to the concerns of records managers and archivists, because as a profession(s) we are concerned with the ability to manage records over time, and difficulties in migrating content hamper our ability to manage content over time.  We know that applications have a shelf life – after a period of years a new application comes along that can do the same job better and/or cheaper, and therefore we want to move to the new tool.  The problem is that retention periods for business records are usually longer than the shelf life of applications.    Therefore it is probably from the records management or archives world that a solution will come to this problem, if it comes at all.

The first generation of electronic records management system specifications (everything from the US DoD 5015.2 that first came out in 1998 to MoReq2 which came out in 2008), did not attempt to tackle the problem. They told vendors what types of metadata to put into their products – but they did not tell vendors how to implement that metadata.   For example these specifications would specify that records had to have a unique system identifier, but it was up to the vendor what format that identifier took. They had to have a permissions model but what functions and roles they set up was up to the vendor, and so on.

This lack of prescription had the benefit of sparing vendors of existing products the necessity of re-architecting the way they assign identifiers/implement a permissions model/ keep event histories etc. Had existing vendors been forced to re-architect in such a way it would have proved a major disincentive for them to produce products that complied with the specification. But the disadvantage was that the electronic document and records management systems (EDRMS) that these specifications gave rise to each had their own permissions models and metadata structures. When an organisation wanted to change from one specification compliant EDRMS to another, they had the same content migration problems as you would when migrating content between instances of any other type of information system. An archive (for instance a national archive) wishing to accept records from different EDRM systems would need to come up with a bespoke migration procedure for each product.

MoReq2010’s attempt to facilitate content migration between MoReq2010 compliant systems

MoReq2010 marks something of a break with past electronic records management specifications.  One of its stated aims is to ensure that any compliant system can export its content together with their event history, their access control list and their contextual metadata, in a way that any system that has the capability of importing MoReq2010 content can understand and use.

In order to this it has had to be far more prescriptive than previous electronic records management specifications in terms of how products keep metadata.

For example

  • It tells any compliant system to give each implementation of that system a unique identifier. This means that any entity created within that implementation will be able to carry with it to subsequent systems information about the system it originated in
  • It tells every implementation of every compliant system to give each entity it creates the MoReq2010 identifier for that entity type, so that any subsequent  MoReq 2010 compliant system that the entity is migrated to understands what type of thing that entity is (is it a record? or an aggregation of records? or a classification class or a retention schedule? or a user? or a group? or a role?)
  • It tells every implementation of every compliant system to give every entity created within it a globally unique identity an identifier in a MoReq2010 specified format. Each entity can carry this identifier with it to any subsequent MoReq 2010 compliant system, no matter how many times it is migrated
  • It tells every implementation of every compliant system to give each entity an event history that not only records the functions performed on that entity whilst it is in the system, but which also could be carried on and added by each subsequent system.
  • It tells each compliant system to create an access control list for each entity in the system, that governs who can do what in relation to that entity whilst it is in the system, and which can be understood, used, and added to by any subsequent compliant system that the entity is migrated to.

To achieve the last two of these ambitions MoReq2010 had to get into the nitty gritty of how a system implements its permissions model.

MoReq2010 and permissions models

I recorded two podcasts with Jon Garde about the permissions model in MoReq2010:

  • episode 7 of Musing Over MoReq2010 is about how the ‘user and group service’ section of the MoReq2010 specification
  • episode 8 (shortly to be published here )is about the ‘model role service’ section – the part of the MoReq2010 specification that deals with functions (the actions users can perform within the system) and roles (collections of functions).

In the latter podcast Jon said that the model role service was the part of MoReq2010 that caused him the most sleepless nights when he wrote it.  The problem was that every product on the market already has a permissions model, with its own way of describing the functions that it allows its users to perform on entities within the system.

The dilemma for Jon writing Moreq2010 was as follows:

  • If the specification prescribed a way for each system to implement its permissions model then existing systems would have to be rewritten and this would act as a major disincentive for vendors to revise their products to comply with MoReq2010
  • If the specification did not prescribe a way for each system to describe the functions that users could perform within it then subsequent systems would not be able to understand the event histories of exported entities (because it would not understand which actions had been performed on the entity concerned) or their access control lists (because it would not understand what particular users/groups of users were entitled to do to that entity)

The solution that Jon adopted was half way between these two options.  In the model role service MoReq2010 outlines its own permissions model, with definitions of a complete set of functions that a record system can allow users to perform on entities.

MoReq2010 does not insist that to be compliant a system must implement every one (or even any one) of the functions that are outlined within the model role service.  It allows products to carry on using their own permissions model.  However MoReq2010 does insist that a system must be able to export their content and metadata with the functions and roles expressed as the functions and roles outlined in the MoReq2010 specification.  In other words a product would need to map its existing permissions model (functions and roles) to MoReq2010 functions and roles.   This would mean that two MoReq compliant systems with entirely different permissions models could both export their content with all of the functions in the access control lists and the event histories expressed as MoReq2010 functions.

Mapping the functions and roles in their product’s permission model to MoReq2010’s permission model is a significant body of work for vendors of existing systems, and they will obviously make a commercial judgement as to whether the benefit to them of achieving MoReq2010 compliance outweighs the cost of the investment they will need to make those mappings and to implement the other changes, such as the identifier formats, that MoReq2010 demands.

Because MoReq2010 is so prescriptive as to how systems keep metadata it could well be that it is easier for new entrants to the market to write new products from scratch to comply with the specification than it is for existing vendors to re-architect their products to comply. If I was a vendor writing a new document or records management system from scratch I would certainly think about simply implementing the MoReq2010 permissions model outlined in the model role service.

Why is import more complex than export?

The core modules of MoReq2010 include an export module.  Every compliant system must be able to export entities and their event histories, access control lists and contextual metadata in a MoReq2010 compliant way.   There is no import module in the core modules of MoReq2010.  Vendors can win MoReq2010 compliance for their products without their products being able to import content and its metadata from other MoReq2010 compliant systems.

The import module of MoReq2010 is being written as I write, and is scheduled for release sometime in 2012.  It will not be compulsory.  The reason why the import module is not a compulsory module of the specification is that not all records systems will need to import from other MoReq2010 compliant records systems.  For example by definition the first generation of compliant systems will not have to import from other compliant systems (because they have no predecessor compliant systems to import from!).

It will be more complex for a system to comply with the import requirements of MoReq2010 (when the module is published) than it is with the export requirements.

For example:

  • an existing product that seeks compliance with the core modules of MoReq2010 (but not the additional and optional import module) will have to map its functions (actions/permissions) and roles to the functions and roles outlined in MoReq2010.  It does not have to worry about all the functions listed in MoReq2010 – only the functions that it needs to map its own functions to
  • a product that seeks additionally to comply with the import module of  MoReq2010 compliant system will need to be able to implement all of the functions listed in MoReq2010 – because it needs to be able to import content from any MoReq2010 compliant system and a MoReq2010 compliant system may chose to use any of the functions listed in MoReq2010.

I put it to Jon in our podcast on the model role service that we would know that MoReq2010 had ‘arrived’ if and when someone brings to market a product that complies with the import module and is capable of importing content from MoReq2010 compliant systems.  Once you have products capable of importing from MoReq2010 compliant systems there is all of a sudden a purpose to implementing MoReq2010 compliant systems – the theoretical possibility of being able to pass content onto another system that understands the content as well or nearly as well as the originating system is turned into a practical reality.  Once you have a product that is capable of importing from MoReq2010 compliant systems it is in the interests of anyone implementing that product to influence whoever runs the applications that they wish to import from to make those applications MoReq2010 compliant. Imagine a national archives running an electronic archive with a MoReq2010 import capability.  It would be in the interests of that national archives to pursuade the various parts of government who contribute records to them to implement MoReq2010 compliant systems.

Jon’s response on the podcast was to lay down a challenge to the archives world to develop a MoReq2010 compliant electronic archive system, with a MoReq2010 compliant import capability.

What are the chances of MoReq2010 catching on?

MoReq2010 is doubly ambitious.  In this post I have looked at its ambition to ensure that content can take its identifiers, event history, access control list and contextual metadata with it through its life as it migrates from one system to another.  Its other great ambition is to reach a situation where any application in use in a business is routinely expected to have record keeping functionality.   The two ambitions are related to each other.

  • MoReq2010 makes it feasible for the vendor of a line of business system to add records management functionality to their product and get it certified as being a compliant records system. The specification has done this by eliminating from the core modules  any requirements that are would not be necessary for every system to perform however small and however specialised. A compliant system does not have to be able to do all the things an organisation-wide electronic records management system would have to do.  It only needs to be able to manage and export its own records. Note that MoReq2010 makes it possible for vendors of line of business systems to seek compliance, but the specification alone cannot incentivise them to do this – incentivisation would have to come from the market or from organisations that could influence the market
  • Because MoReq2010 allows the possibility for  records to be kept in multiple line of business and other systems within an organisation then the issue of migration becomes very important.  When a line of business applicatin is replaced the organisation will need to migrate content  either to the application’s replacement or to an organisational records repository or or to a third party archive. Hence the ambition that any compliant records system can export content and metadata in a way that another compliant system can understand.

Being ambitious carries with it a risk.  MoReq2010 does call for existing vendors to re-architect its systems, and vendors do not like re-architecting their systems.  If too few vendors produce products that comply with the specification then MoReq2010 will go the way of its predecessor, MoReq2, which died because only one vendor felt it was commercially worthwhile to produce a product that complied with it.

In the situation that electronic records management finds itself in, being ambitious is less risky than trying to incrementally tweak previous specifications.   MoReq2, failed because by the time it was published in 2008 the bottom had fallen out of the market for the EDRM systems that it and previous electronic records management system specifications underpinned.  SharePoint had come along and pushed it over like a house of cards.

EDRM fell without so much as a whimper because no-one was prepared to defend it.  Archivists were not prepared to defend it because they had not benefited from it – it was as hard for them to accept electronic transfers from EDRM systems as from any other type of application.  Practioners were not prepared to defend it because it had proved difficult and expensive to implement monolithic EDRM systems across whole enterprises.  The ECM vendors who had acquired EDRM products were not prepared to defend it because EDRM represented only a relatively small portion of their portfolio, and they had no stomach for a fight with Microsoft.

MoReq2010 has a chance of success.  It is not guaranteed to succeed, but it has a chance.  The reason why it has a chance is because it is addressing the right two questions – how do we get records management functionality adopted by all business applications? and how do we ensure that content can be migrated easily and without significant loss of metadata from one application to another?

These questions will have to be nailed. If MoReq2010 succeeds in nailing them so much the better.  If it doesn’t, if the market isn’t ready for it, then whatever specifications come after it will have to nail them.  There is no going back to the EDRM ‘one records system-per-organisation’ model.
Talking records – podcast discussion with Christian Walker

In this podcast, Christian Walker and I discuss whether records management is compatible with enterprise 2.0.  We talk about the problems of capturing records into a records systems such as an EDRMS.  We ponder on whether anyone could or should integrate their EDRM with a web service such as Twitter or Facebook.

I express mixed feelings about the concept of asking users to declare things as a record. (Chris wrote a blogpost ‘records matter, declaration doesn’t‘ last year, with a more recent follow up).

We discuss whether text analytics could be used to automatically select which e-mails should be saved as a record. We conclude that you probably could in isolated areas of your business, that you studied in depth and trained the analytic engine in, but that it would be difficult if not impossible to scale it up over all the activities of an organisation.

We discuss the challenges of using the word ‘record’ given that when anyone uses it you don’t know whether they mean one document or a collection (large or small) of documents. Chris wonders whether it is viable to carry on using the word ‘records’ but neither he nor I could come up with an alternatiive.

We end up talking about the proposed (but postponed) SOPA (Stop Online Piracy Act). Chris opposes the idea that a platform such as a filesharing site should be closed down if some of its users contribute content that infringes intellectual property rights.  He says it is up to content owners to protect their content online. He calls the media backers of SOPA ‘dinosaurs’.  I recall that we records managers get called dinosaurs too and I try to draw parallels.  The new media companies of Silicon valley (Facebook, Google, Twitter) are interested in the platform rather than the content.  The old media companies (Disney, News International) and records managers are interested in the content rather than the platform. The thing that records managers and old media have in common is that sometimes we seem to be swimming against the times.

Chris blogs at http://christianpwalker.wordpress.com/   and tweets as @chris_p_walker

Click here to play the podcast:
http://traffic.libsyn.com/talkingrecords/RecordsManagement_and_E2.0.mp3

MoReq2010 update

The DLM Forum held their triannual conference in Brussels last month.  The conference brought together archivists and records managers from across Europe.  The DLM forum had earlier in the year published the MoReq2010 electronic records management system specification, and there was much talk of the specification at the conference.

The DLM forum released the first sets of test scripts to vendors immediately prior to the conference. This is a significant point in the life of an electronic records management system specification. It means that vendors get to see exactly how their products will be judged by test centres.  This gives them a solid basis for deciding whether or not it will be worth their while modifying their products to comply with the specification.  It means they can get down in ernest to the work of preparing products to comply with the specification.

I have two predictions to make about MoReq2010.  Firstly that it will be a slow burner, secondly that it will end up being the most influential of the world’s electronic records management specifications.

It will take some time before the exact nature of MoReq2010 compliant products becomes apparent.   It is likely that MoReq2010 will lead to a very heterogenous set of products, ranging from products that simply manage records held in one type of application (products that simply manage records held in SharePoint, products that simply manage records held in an e-mail system) to products that can manage records held in any application that the organisation uses.  This is in contrast to the previous generation of electronic records management specifications (from DoD 5015.2 to MoReq2) that led to a very homogenous set of products – namely those products dubbed ‘electronic records management systems’ (EDRMS).

It was interesting to hear Jon Garde say at the conference that he hoped that the acronym that comes to be applied to systems that comply with MoReq2010 is ‘MCRS’ (MoReq2010 compliant record system) rather than ‘EDRMS’.

The second reason why MoReq2010 will be a slow burner is that it is the first specification which has been designed to be added to as it goes along.  One of the key learnings from the last seven years has been the realisation that the digital world is constantly creating new formats. Although we as records managers are primarily interested in the content and context of records rather than their format, we have to acknowledge that different formats have different management requirements.  The old paradigm of documents being aggregated into files is hard enough to apply to e-mail, let alone blogposts, status updates, discussion board posts and wiki pages.  E-mails tend naturally to aggregate themselves into e-mail accounts, blogposts aggregate themselves into blogs, status updates aggregate themselves into streams, wiki pages aggregate themselves into wikis.

MoReq 2010 takes a more generic approach. In the core requirements (the requirements that any MCRS has to adhere to) it talks in a rather abstract fashion of the system being able to manage ‘records’ that are grouped into ‘aggregations’ and which receive their retention rule from a records classification.   This begs the questions – what formats of records can any specific MCRS manage? How will it aggregate them?

The core requirements of MoReq2010 will be supplemented by extension modules.  At the DLM forum conference it was announced that extension modules were being written for specific types of record formats (for example e-mails), and for particular types of aggregation (for example the traditional ‘file’).  Buyers will be able to see what record formats and what types of aggregations a particular MCRS will be able to manage by looking at which extension modules the particular MCRS complies with.

In theory extension modules could be written for any and every format that came along and that had specific management requirements.  In practice this is likely to depend on the  capacity of the DLM forum to produce such extension modules.  Whereas the core requirements of MoReq2010 were substantially the work of one man (Jon Garde, with help from colleagues such as Richard Blake) it is hoped that a much wider base of people will contribute to the writing of extension modules. At the conference Jon appealed to those assembled to step forward and volunteer to help in the writing of these modules.

Jon Garde predicted an explosion in MoReq2010 over the next 12 months, as both MoReq2010 compliant products, and MoReq2010 extension modules started to appear.

As I write this post the most influential electronic records management specification in the world is the US DoD 5015.2.   That specification is looking increasingly jaded and outdated.  It was last revised in 2007, and the latest version does not reflect the changed nature of the digital landscape in organisations since the rise of both social computing and of SharePoint.   Over the medium term MoReq 2010 will overtake DoD 5015.2 in importance provided only that vendors find it feasible and profitable to develop products that comply with it.

What is SharePoint good for?

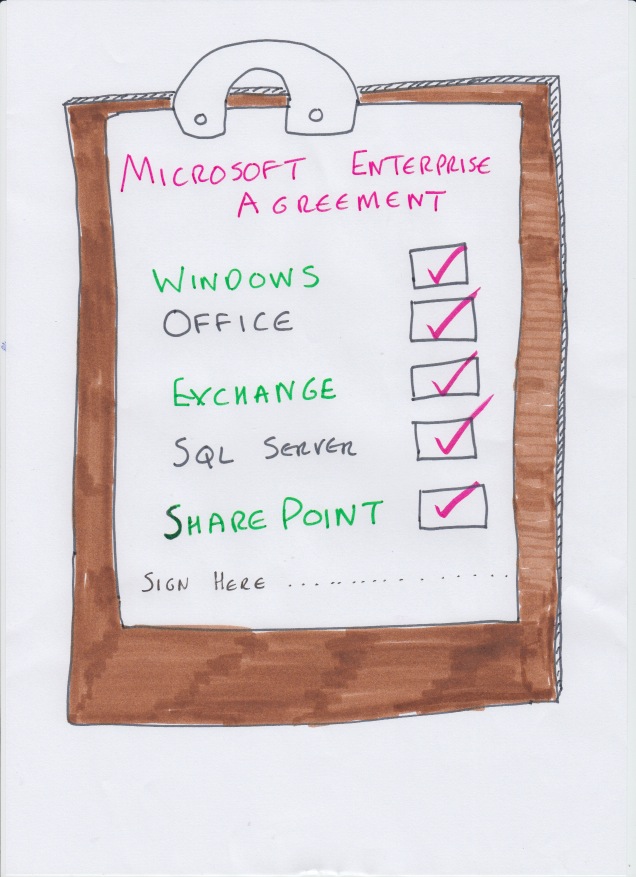
SharePoint is unique amongst information management systems in that it is rarely purchased with any specific purpose in mind. It is most often bought bundled in with other products when an IT department negotiates an enterprise agreement with Microsoft.

Microsoft enterprise agreement

This creates a challenge for such organisations. What should they use it for? What shouldn’t they use it for?

Giving people out of the box SharePoint team sites and hoping that they do something useful with them produces very variable results. Some teams will make their site work. Many others will either decline to put the effort in to tailor the site to their needs, or will tailor the site but make a bad job of it and the result will be unpopular with their colleagues. SharePoint team sites are most effective when they are targeted at (and restricted to) those areas of the business whose importance justifies the configuration of a template team site targeted specifically at their work.

The SharePoint Symposium in Washington DC that I attended last week brought together analysts such as Tony Byrne, Alan Pelz-Sharpe, Rop Koplowitz and Mark Gilbert; together with SharePoint implementers such as Shawn Shell and Richard Harbridge

SharePoint is a platform, not an application
Tony Byrne said SharePoint was best described as a platform rather than as an application. It had a great many features which provided organisations with the potential to build applications.

An application is a set of features that have been combined together to provide an organisation with a useful capability (a contracts management capability, a social computing capability etc.). SharePoint is feature-rich, but in most areas these features have not been knitted together in a way that provides an organisation with a useful capability.

For example in social computing SharePoint has every feature that you might ask for – blogs, wikis, microblogging, discussion boards etc.  The features may be variable in quality (Tony said that the microblogging ‘sucks’), but they are all there. However you could not roll out vanilla SharePoint blogs, wikis, discussion boards, activity streams etc. and expect any significant uptake of these features.  If you wanted a social computing capability that people would actually find useable, interesting and lively then you would either have to build a customised user interface on top of those features, extend SharePoint with a third party tool, or use a separate application entirely.

A member of the audience asked whether SharePoint could be used for business process management.  Tony said that SharePoint had good routing features, and if all the work in a particular process was to be done within SharePoint itself then it could fit the bill. But a business process management capability implies that a system is orchestrating a complex process across several different applications and SharePoint lacks the ability to do that.

The SharePoint ecosystem

Tony told us that consultants, ISVs and developers liked SharePoint because it ‘meant never having to say no to a client’. Given enough time and resource SharePoint could be made to do almost anything. SharePoint extends the .Net framework (Microsoft’s answer to Java, which is in itself a platform). It offers an object model and services on top of .Net that developers can make use of.  It is better documented than most other enterprise applications, and it’s codebase is remarkably stable considering the scale of the product. It also has an enormous ecosystem, and Microsoft themselves estimate that for every €1 spent on SharePoint licences €6 are spent with the SharePoint ecosystem.

Tony warned organisations against trying to use SharePoint to meet every technological need. Most organisations have SharePoint licences, and when a technology need arose someone, somewhere will ask the question ‘why not use SharePoint for that?’. Tony advised organisations to turn this question on its head and ask ‘why SharePoint?, ‘Why would customising and/or extending SharePoint be more effective than getting a tool that is already optimised to fulfil that purpose?’

Mark Gilbert said that organisations were getting frustrated at having to implement third party tools in order to do things that they expected SharePoint to be able to do natively.

Alan Pelz-Sharpe described the SharePoint ecosystem as being a very crowded market, full of small companies. There are lots of start-ups and many companies are operating on venture capital funding. Some of the companies will last but many won’t. Some will go-under, some will get acquired. When buying a third party product to extend SharePoint, organisations should consider the financial stability of the company and their road map for the future. Will they still be around to update their product every time a service pack is issued or a new version of SharePoint is released?

Using SharePoint to provide a user interface to data held elsewhere
Shawn Shell described some powerful uses of SharePoint’s Business Connectivity Services (BCS).  Organisations often have databases that contain valuable data (for example cusomer data in a customer database) that is not available to all staff because the organisation is reluctant to pay for extra user licences.  SharePoint’s BCS allows you to set up a connector to the database, and to surface the customer data as a SharePoint list.   This data can then be used to improve the findability of customer data in SharePoint. A column from the list such as ‘Customer ID’ could be used as a controlled vocabulary within the SharePoint environment, to be added as metadata to documents held in document libraries within the SharePoint implementation.

Office 365
Tony Byrne said that Microsoft seemed to have settled on a three year release cycle for SharePoint.  This three year wait was fine for steady areas like document management, but in quicker moving areas like social computing it put SharePoint at a disadvantage compared to more agile competitors.

Shawn Shell said SharePoint Online (a component of Microsoft ‘s cloud based Office 365) could give Microsoft the opportunity to introduce new features on a rolling basis rather than waiting for the next product release.   Shawn described SharePoint Online as a ‘weird mixture’ of the core SharePoint features (lists, libraries, sites etc.) available in SharePoint Foundation, together with some, but not all, of the features of the paid-for SharePoint 2007.

Rob Koplowitz said that early adopters are having a really hard time with SharePoint Online,  but he thought that over the long term it would be the way that most SharePoint clients will go.

Mark Gilbert said that at the moment Office 365 was geared to small and medium sized organisations.  At the Office 365 product launch Microsoft used the example of a dog grooming company.

SharePoint versus Box.net
Alan Pelz-Sharpe said that SharePoint is huge business and it is not going to go away any time soon, but cloud based file share services such as box.net, Huddle and others are the first to start to firing arrows across SharePoint’s bow. The reason why they are a threat is that filesharing is the core of SharePoint’s capabilities.  Filesharing is the one thing SharePoint does really well out of the box.

Alan said that  SharePoint Online would  find it hard to compete with born-in-the-cloud competitors.  Companies like Box.net  were cloud based from the start. They have optimised their product architecture for the cloud, all of their development effort goes into their cloud offering, and their partner channel is geared for the cloud.  In contrast SharePoint ‘s history is as an on-premise product.  Its architecture is geared to on-premise, the vendors in its ecosystem were mostly geared around on-premise.

Mark Gilbert said that SharePoint is an environment that organisations are used to tweaking and fine tuning, but you cannot do that to anything like the same extent with SharePoint Online.

Rob Koplowitz said that SharePoint was a Swiss army knife of a product that had a huge array of different features.  A service like Box.net was like a screwdriver – it did one job (filesharing).  But if you only want a screwdriver, why buy a Swiss army knife? The threat to SharePoint from Box.net and others would come if organisations decided that they wanted a way to tackle the fileshare problem without engaging with the complexity of SharePoint.

The analysts noted a trend in attempts to tackle the filesharing problem.  Early attempts to get away from shared drives came from powerful systems like Documentum that imposed rigid disciplines on users and gave strong central controls.  SharePoint upstaged these products by providing  a product that was simpler for end-users (at the expense of weaker central control and a more sprawling, less coherent repository).  Now Box.net comes along and offers a solution that is even more simple for end-users, and has even less central controls.

Rob Koplowitz pondered whether organisations were doomed to forever repeat the shared drive scenario on different products (SharePoint, Box.net etc.) with content sprawling on systems that are always beyond the organisation’s control.

Is SharePoint a records management system? – podcast

Last Friday Brad Teed (CTO of GimmalSoft) and I discussed whether or not SharePoint could be regarded as a records management system. We recorded the discussion for the ECM Talk podcast series.

Click on the play button below to hear the podcast. If the play button is not showing in your browser (it needs Flash) then you can get the podcast from here or from i-Tunes (search on ‘ECM Talk’). The podcast is around 45 minutes minutes long.

Brad said that SharePoint 2010 could be regarded as a records management system with the caveat that it did not do things in the way that traditional records management systems did them.

I conceded that SharePoint 2010 had records management features (such as holding and applying retention rules, holding a hierarchical classification, locking documents down as records) but I did not think that these features were brought together in a coherent enough way to justify calling SharePoint a records management ‘system’.

SharePoint 2010 offered organisations two different approaches to records management – the in-place approach and the records centre approach. Brad and I described and critiqued these two different approaches . I said it was a choice between ‘a rock and a hard place’ because both approaches had serious drawbacks:

  • The in-place approach left records scattered around team sites under the control of local site owners without providing any reporting capability to give a records manager visibility over them all
  • The records centre approach had the advantage of bringing records together into one place that the records manager could control. However it brought with it the complexity of managing the routing rules necessary to get documents from SharePoint team sites to the record centre

Brad and I will be debating the issue of records management in SharePoint live at the SharePoint Symposium in Washington DC on 2 November 2011.

Musing Over MoReq2010- podcast series with Jon Garde

There are many differences between MoReq2010 and previous electronic records management certification regimes (including DoD in the US, TNA in the UK, the previous version of MoReq in Europe etc.)

MoReq2010 is different in:

  • its fundamental assumptions (it assumes that records are captured in many different systems within an organisation, rather than in one records system)
  • what it is fundamentally trying to do (specify the minimum set of things that any application needs to do to manage its records, rather than specify a general records system that does everything any organisation would want its record system to do)
  • the concepts it uses  (most notably the concept of an ‘aggregation’ replacing the concept of a ‘file’ )
  • the way it is structured (with the functionality grouped into ten services)
  • the fact that it will develop over time (with new modules being added to meet to meet specific needs)

I spoke to Jon Garde (the lead author of MoReq 2010) before his talk to the 2011 IRMS conference.  He said that it was impossible to do justice to all those changes within the confines of a 30 presentation speech.  I suggested a podcast series in which we could discuss in detail the different areas of MoReq2010, and the thinking behind them. We have called the podcast series MusingOverMoReq2010.

We have recorded three epsiodes so far – episode 1 discusses the general philosophy behind MoReq 2010. Episode 2 looks at the classification service, and the role of a classfication within a MoReq2010 compliant system.   Episode 3 looks at the disposal service and how retention rules are applied within a MoReq2010 compliant system

As well as discussing an aspect of MoReq2010, each episode also contains news of recent developements around MoReq2010. This is to allow for the fact that MoReq2010 will continue to develop as extension modules are written, and as the testing centres get set up and certification gets underway. The third section of the show is a ‘postbag’ section where we will discuss any questions you send us.

You can listen to it on the Musing Over MoReq2010 website.   You can subscribe to it from the i-tunes store (search on Musing over MoReq2010) or by getting your podcatcher to subscribe to this feed: http://musingovermoreq2010.com/MusingOverMoReq2010_feed.atom

10 questions on the current state of the ECM market

On Wednesday I recorded an ECM talk podcast in which I put  10 questions  about the current state of the enterprise content management market to Alan Pelz-Sharpe.

Click on the play button below to hear the podcast. If you don’t see the play button (it needs Flash) then you can get the podcast from here. The podcast is just over 50 minutes long.

The ten questions, and a flavour of some of Alan’s answers are given below – there is a lot more detail in the actual podcast itself

Why have HP bought Autonomy?

Alan said that most analysts were surprised at how much HP paid for Autonomy.  The best guess at what HP (a hardware company) wants to do with Autonomy (a software company) is that they may wish to create some kind of appliance which has Autonomy’s IDOL search engine already loaded onto it (a bit like the Google search appliance).  One thing that HP and Autonomy have in common is that they have both bought well-regarded electronic records management vendors (Tower and Meridio respectively), and done very little with them.

How hard have the ECM vendors been hit by the rise of SharePoint?

Alan said that the ECM vendors haven’t bit hit as hard as you might think. Their revenues are still rising, and most of them enjoy good relations with Microsoft.

How does EMC and Open Text compare with the bigger ECM vendors (Oracle and IBM)

Alan said that Oracle and IBM are so big because they do a huge variety of stuff as well as ECM.  But at the end of the day if you are buying FileNet from IBM you are dealing with the FileNet division, not the whole massive company. So for buyers of ECM systems company size doesn’t matter that much.  Open Text is the largest company that focuses exclusively on ECM.   EMC’s business is mainly about storage.  They bought Documentum, but Documentum is very different from the rest of the EMC group and there has not been many synergies.

What is happening in the CRM (Customer relationship management) arena and how does it relate to ECM?

Essentially ECM and CRM are seperate worlds without much overlap.  CRM is a vital tool for many organisations.  As yet there is not a great deal of tie-ins with ECM.  Oracle has both a CRM and an ECM suite, which work together reasonably well.  SAP signed a large deal with Open Text but there doesn’t seem to be a huge number of organisations using SAP together with Open Text products.  Many of the CRM tools will do a little bit of document management of customer related documents, but for the most part organisations will have CRMs that don’t talk to whatever ECM product(s) they have

The Europeans have just revised their electronic records management specification (MoReq2010).  When will the US records management standard DoD 5015 be revised (it was issued back in 2007)

Alan said he didn’t know of any plans to revise DoD 5015.  SharePoint drove a horse and cart through DoD 5015 because Microsoft made the decision to release a document management product that did not comply with it but had huge market success.  Alan said he didn’t see the point in revising it –  it was specifically tailored to US Government (DoD stands for Department of Defense) so some of the requirements are overkill for organisations in other sectors.

After the podcast it occured to me that there was no need for DoD 5015 to be revised.  MoReq2010 is the first of the electronic records management specifications to be extensible. Rather than revise DoD5015, if there were requirements specific to the US  (or to particular sectors in the US) that were not covered in the core requirements of MoReq2010 then a seperate module could be written to cover those requirements for vendors wishing to target their products to the US market.

What is happening in the intranet arena?

Alan said that nothing dramatic is happening in the intranet arena.  Some intranet makeover projects will have been hit by the economic downturn.  Alan can’t understand why some organisations want to use the same product to manage there external web-site and their intranet – to him they are fundamentally different things with different requirements.

Do you know any organisation that manages their e-mail well?

Alan said that of all the ECM implementations that he sees, the type that gives the quickest and most reliable return on investment is an e-mail archiving tool brought in to take stored e-mails off the mail servers.  I said I would like to see some of the e-mail archiving vendors apply for certification for their products under MoReq2010, so that buyers could be more confident of their ability to export e-mails out of their e-mail archive if they neeeded to.

What do you think of PAS 89?

PAS 89 will be a UK standard on enterprise content management, with a view to becoming an international standard.  Alan said PAS 89 was a good attempt to define the scope of enterprise content management, although it was hard to think of what an organisation would specifically use it for.

How does Alfresco compare with the proprietary ECM products 

Alan said that if we were talking about open source ECM products Nuxeo should be mentioned alongside Alfresco. Both of them are established, mainstream enterprise content management systems.  The main difference between them and the proprietary ECM products is the licensing model.

How does Google Apps compare with the established ECM products 

In terms of impact on the ECM market Alan is more interested in Box.Net than Google Apps.  Alan and James discussed the prospect of new start ups deciding not to set up shared drives and instead using services like Box.Net in the cloud to provide a relatively simple place for colleagues to store and share documents.

After the podcast it occured to me that for a good 15 years we have been wondering what would replace shared drives. Shared drives have survived so long because anything that could have replaced them for general document storage (EDRMS, SharePoint) has proved more complex than shared drives, and so shared drives retained their role as an uncomplicated, quick place to store documents.  From a users perspective something like Box.net is as simple to use as a shared drive, and has the advantage that folders and documents can be shared with people outside the team, and with people outside the organisation.   From an organisation’s information management point of view box.net is currently little better than a shared drive in terms of being able to apply retention rules and a records classification (though maybe if an ecosystem grows around Box.net someone could come up with a MoReq2010 compliant plug in for it- that would be interesting!)


The implications of MoReq2010 for records management practice

The DLM forum is having its triennial conference in Brussels this coming December.  I responded to the call for speakers with the following submission:

MoReq2010 can be seen as an attempt to ensure that the records management baby is not chucked out with the EDRMS bathwater.

The EDRM idea was solidly based in records management theory, but lost its market viability after 2008 thanks to the global economic downturn, the rise of SharePoint, and perceived problems with usability and user acceptability of EDRM systems and their attendant corporate fileplans.

SharePoint 2007 and 2010 both offer records management features, but neither offers a well-thought through records management model.  Most organisations with SharePoint implementations have not attempted to use records management features such as the SharePoint records centre.  Of those that are trying to use those features only a relatively small number will be able to impose sufficient governance to enable them to viably manage records in SharePoint.

For most organisations SharePoint will be a records management problem rather than a records management solution.  In a few years time more organisations will be saying ‘we need help managing the records that are scattered around our SharePoint implementation’ than will be saying ‘thanks to SharePoint content types we can now apply retention rules to records across our organisation’.

MoReq2010 doesn’t kill off the EDRM model (you can  use a MoReq2010 compliant system as an EDRM provided it complies with the plug-in modules for a user interface and a hierarchical classification), but it does not attempt to revive it either.

The fact that MoReq2010 is offering two alternative to EDRM, rather than just one, whilst continuing to support the EDRM model itself, indicates that the profession is not yet ready to commit its weight behind one single approach.  It also means that we are in a transition period, during which many records managers and consultants will be uncertain as to what approach to advise their organisations to take.

The two new approaches offered by MoReq2010 are ways of dealing with the ‘multiple repository problem’ – the fact that every organisation deploys numerous different applications to create, capture and store content and records.   EDRM systems rarely tackled that problem.  They typically relied on colleagues voluntarily declaring material into the EDRM as records, and there was rarely any incentive for colleagues to move documents out of a line of business application into an EDRM.

The back-end repository approach

The first of the two approaches is what I would call the back-end repository approach (I would like to call it repository-as-a-service but I fear you may mistake it for a cloud offering).  In this approach a MoReq2010 compliant system governs content captured in the multiple different applications of the organisation.  It governs either by taking that content out of those applications and storing it in the MoReq2010 compliant system, or by protecting and governing that content whilst it stays within those applications themselves.

This is an approach that vendors have been working on over the past five years – both EDRM/ECM vendors looking for ways to continue selling to customers who have chosen SharePoint instead of an EDRM, and e-mail archiving vendors looking to expand the scope of their archiving systems.  It is also compatible with service orientated architecture of IT departments, but no-one knows yet how it will play with moves to the cloud. MoReq2010 for the first time offers a certification regime for vendors taking this approach, giving the approach more gravitas and credibility, and offering buyers reassurance that their back end repository/archive will not in itself become a black hole from which it is hard to migrate records.

The back-end repository approach significantly changes the role of the records manager.  In EDRM implementations the records manager was interacting with users, training them, cajoling them, tackling change management challenges, and designing classifications that end-users would directly interact with   In the  back-end repository model the records manager has a different role – connecting legacy applications to the back end repository, and trying to ensure that no new application is deployed into the organisation unless it hooks into the back-end repository from day one.  The interaction with, and impact on, end-users will inevitably be reduced, but it is to be hoped it won’t be eliminated entirely.   It will still be important for end-users to be aware of whether or not a piece of content that they have contributed to a particular application has been captured by the back-end repository.

The in-application approach

The second of the two approaches is the addition of records management functionality to each  application deployed in the organisation so that these applications can manage their own records.

This is the approach that I sense the authors of MoReq2010 would like to see prevail in the world. They are well aware that every time a record moves from system to system it loses context, and that ideally records management metadata would be captured from the moment a record was first captured into an application.

This approach is beyond the capabilities of any single organisation – no organisation could customise all their applications for them to become MoReq2010 compliant.  It becomes viable only when the vendors of line of business systems, make their products MoReq2010 compliant – whether they be sector specific applications like social care systems for local authorities, or line of business applications like HR systems.  Its a battle worth taking on for the profession, and worth fighting, but success is likely to be patchy.  The hope is that a tipping point could be reached when everybody expected every application to be MoReq2010 compliant, and felt that something is wrong if it was not compliant.

Preserving e-mail – records management perspectives

On July 29 I attended the Digital Preservation Coalition event Preserving e-mail – directions and perspectives . The event brought together records managers, archivists, cultural heritage institutions and digital preservation experts.  For a summary of the event see Chris Prom’s Practical e-records blog (starting here).  In this post I will give some thoughts on the records management perspective at the event

Three approaches to managing e-mail

In the afternoon tea break Stephen Howard   gave me his take on the three different approaches records managers could take to e-mail

  • the message-by-message approach – where users are encouraged to move significant e-mails out of their e-mail client and put them together with other documents arising from the same work (this is the traditional records management approach).
  • the e-mail account by e-mail account approach – where some individuals within the organisation are selected as having particularly important roles, and their entire e-mail account is preserved
  • the whole e-mail system approach – where the organisation treats its entire e-mail system as one aggregation and applies one retention or preservation rule to the entire system

In his current organisation Stephen is thinking of applying the in-box by in-box approach. It would be relatively easy to identify people in key roles whose e-mail was worth preserving. Those individuals could be told of the organisation’s intention to preserve the contents of their e-mail account after they had left. They could be given ways of filtering out personal e-mail so that the personal stuff did not enter the archive.

Earlier in the day Stephen had given a presentation in which he reflected candidly on advice he had given back in 2005 to a local authority he worked for at the time. The head of IT in the authority was concerned about the e-mail servers, and their lack of resilience in the face of mounting volumes of traffic and e-mail storage. They wanted to buy an e-mail archiving tool, to remove stored e-mails from the production e-mail servers.  Stephen at the time advised them not to.

The authority decided against an e-mail archive.  Instead they adopted the intention of implementing an electronic document and management system (EDRMS) to manage records in all formats, including e-mail.   In the meantime they  used an array of methods to encourage colleagues to adopt better e-mail practice.  The authority :

  • asked colleagues to save significant e-mails into shared drive folders
  • put quotas on e-mail in-box sizes to encourage staff to weed out ephemeral e-mails
  • encouraged people to avoid sending attachments where alternatives existed
  • gave advice and training on good use of e-mail

None of these measures did any harm, but the overall approach did not work. Few colleagues saved e-mails into the shared drives. The bottom fell out of the EDRM market and the EDRM never came. Stephen wondered whether the IT manager was right after all – maybe the e-mail archiving tool would have been the least-worse option.

Records management concerns about e-mail archiving tools

Records managers have had philosophical concerns about e-mail archiving tools.

A standard definition of a record is that it consists of all documentation regardless of format needed as evidence of a piece of work.  The idea of treating one set of documentation (e-mail) differently purely because of its format was anathema to us records managers.

There are practical as well as philosophical concerns.  In particular the concern that an e-mail archive operates as a ‘black hole’ .   Such an archive may well have a great search engine, but how could the organisation allow people to use that search engine given the vast amounts of personal information buried in every e-mail account?  The fundamental problem is that a typical e-mail account  makes no differentiation between innocuous e-mails, and e-mails containing sensitive personal information about the e-mail account holder or the people they correspond with.

In practice an organisation could allow:

  • individuals to access e-mails in the archive that were sent to or received by themselves
  • central administrators to search the entire archive for e-mails that fall within the scope of a legitimate e-discovery request, data protection subject access request or Freedom of Information request

But I don’t see how an organisation could allow staff to search across an e-mail archive  on a day to day basis, to answer mundane business questions, because it would then also be possible for them to  search for personal information on particular colleagues.

Yes you could tell staff that if they send or receive e-mails containing sensitive personal information about themselves or third parties then they should delete it from the e-mail archive, or flag it up with an access restriction.   But could you ever be confident enough that this has been acted upon to widen up access to the e-mail archive?

The access permission problem means that  organisations will not want to give up totally on the idea of having e-mails aggregated in some ways, other than simply lumped together in an e-mail archive divided into individual e-mail accounts.  One of the aims of Customer Relations Management (CRM) implementations  is to ensure that e-mails to/from customers are aggregated by customer rather than by the e-mail accounts of the members of staff that sent/received them.  An EDRMS implementation aims at aggregating e-mails and other documentation according to the piece of work that they arose from.   Both approaches offer the advantage that access permissions can be ascribed that fit the nature of those e-mails.

We need to have our cake and eat it.  The advantage of e-mail archiving tools is that they give you the security of  knowing that you have a record of everything that has come in or out.  But what we also need is the ability to apply frameworks that enable those e-mails to be understood, managed and accessed according to different criteria than the name of the individual who sent or received them.

What impact will MoReq 2010 have on the e-mail archiving tool market?

Until recently the records management world treated the existence of multiple applications within an organisation (e-mail clients, line of business applications, CRM systems, an HR system etc.)  as a problem that could best be mitigated by implementing a single electronic records management system and endeavouring to get all documents or e-mails needed as records saved into it.

The recent MoReq2010 specification takes a different approach. It attempts to boil down a core set of records management requirements with a view to making it feasible for any and every business application to have enough records management functionality to manage its own records, and to export those records and accompanying metadata, rules and classifications at the end of the useful life of the application.   This is hugely ambitious, as line of business application developers and vendors rarely take notice of records management specifications.

The first output of  MoReq2010 – the Core services and Plug-in Modules published in June of this year, does not specifically mention e-mail.   This is because the Core services cover only that minimum set of requirements that every records system  should possess, and it is possible to envisage a records systems that is not intended to hold e-mails.  But an extension module of MoReq2010 is planned, to specifically outline MoReq 2010 records management requirements for e-mail.

It will be interesting to see what effect that MoReq2010 e-mail module, when it appears, will have  on the e-mail archiving tool market.  A MoReq 2010 compliant e-mail archiving system would be an interesting proposition for records managers – I wonder if any of the big players in the market will rise to the challenge.

This 2009 Gartner magic quadrant report on e-mail active archiving tools shows that many such tools are branching out from simply archiving e-mails and now claim to be able to archive and manage material in shared drives and in SharePoint sites.  All the more reason for such products to go for MoReq 2010 certification.

Whether they do go for it depends in part upon their willingness to re-architect the way their systems maintain metadata and event histories.  MoReq 2010 is much more prescriptive on these fronts than previous standards, and established players with set architectures may be reluctant to change.

The challenges of archiving databases – Podcast with Kevin Ashley

There is seen to be a big divide between the domain of ‘structured data’ sitting in rows and columns within databases, and that of ‘unstructured data’ (documents, images etc). In fact the two domains are related.  Every document management system has a database within it to maintain the metadata about the objects it holds.  It is worthless to be able to migrate/extract/preserve the documents unless you can also migrate/extract/preserve the metadata held in the database.

Last Friday I had a discussion with Kevin Ashley  about digital preservation and the challenges of archiving data from databases.

Archivists encountered the problem of archiving databases earlier than they faced the problem of archiving electronic documents from document management systems.  This was simply because organisations used computing power for structured data  earlier than they did for the creation and storage of documents.  In the early 1980s Kevin was already involved in attempting to rescue data from legacy databases within a UK government research council.

In 1997 Kevin led the creation of NDAD, the National Digital Archive of Datasets.  This pioneering service, was set up under contract to the UK National Archives (then called the Public Record Office), and opened in 1998.

At the time it was widely thought within organisations that databases were the sphere of IT professionals and data managers, not records professionals (records managers/archivists). In fact NDAD needed the skills of all three of these professions. Kevin said that the contribution that the archivists in NDAD made was invaluable, because they knew how to to draw up agreements with the contributing organisation, and how to capture the context of the dataset (who created it, why, how, what they used it for etc.).

The National Archives required NDAD to use the ISAD G standard of archival description to catalogue each dataset. I asked Kevin whether ISAD G had been difficult to adapt to structured datasets (it was written with files/documents in mind). Kevin said that ISAD G had been very useful and worked very well for the datasets.

I asked Kevin whether he thought that the databases in use by organisations today were easier or harder to archive than the databases in use in the 1990s.   Kevin said that the challenges were different.  An individual database in an organisation today was easier to understand and extract data from than an equivalent database in the 1990s. But the challenge today is that the databases in an organisation tend to be integrated with each other. For example all or most databases in an organisation may use the organisation’s people directory to hold information about their users. As soon as you try to archive data from one database you are faced with the challenge of archiving data from all the other databases that it drew data from.

I asked Kevin whether initiatives such as the open data initiative at data.gov.uk and the whole linked data/semantic web movement would mean there is less of a role for archivists in getting government datasets into the public domain. He said that was very rare for an organisation to make an entire database available to the public online. Usually the public would be given access to a derived database, which contains only a subset of the data in the database used by the government department itself. So there is still a role for the archivist in ensuring that the database that actually informed government decisions was preserved.

Kevin talked about one of the perennial challenges of digital preservation, the challenge of avoiding lock-in to an application and ensuring that information (whether it be structured data in a database, e-mails in an e-mail system, or documents in a document management system) can be exported from a particular application when that application is no longer used by the organisation.   I was interested in the parallels here with the recently published MoReq 2010 records management standard.

MoReq 2010 was written on the premise that the content of applications is typically still of value after the application itself has fallen into disuse, and therefore a key attribute of any application must be that it can export data, objects and metadata in a form that another application can understand.  After we had stopped recording we realised that link between NDAD and MoReq 2010 comes in the person of Richard Blake, who has recently retired from the the UK National Archives. Richard was strongly involved in both the creation of NDAD in the 1990s and with the writing this year (with Jon Garde, Richard Jeffrey-Cook and others) of MoReq 2010.

Kevin reported Richard as saying that one of the weaknesses of early electronic records management system specifications (such as TNA 2002 from the National Archives) was that although all compliant EDRM system would keep metadata in a way that could be exported, each different EDRMS kept metadata in a different way, so it was hard an organisation to migrate from one vendor’s EDRM system to another. It was this experience that informed MoReq 2010s decision to define very precisely how systems keep metadata, in order that the metadata of one MoReq 2010 compliant system could be understood by any other MoReq 2010 compliant system.

Click on the play button below to hear the podcast. If you don’t see the play button (it needs Flash) then you can get the podcast from here. The podcast is 44 minutes long.

Notes

This podcast was recorded for the Records Management Today podcast series, hosted by the Northumbria University. To see all the podcasts in the series visit Records Management Today

Elizabeth Shepherd and Charlotte Smith have written an article on the application of ISAD G to archival datasets, which focused on NDAD’s experience. (Journal of the Society of Archivists ‘The application of ISAD(G) to the description of archival datasets’ Journal of the Society of Archivists 21: 1 (April 2000): 55-86)

Patricia Sleeaman, Digital archivist at the University of London wrote an article for the journal Archivaria about the National Digital Archive of Datasets, the article is available as a free pdf download from here

In the podcast Kevin discussed two datasets accessioned by NDAD:

Kevin Ashley is Director of the Digital Curation Centre.  He is @kevingashley on twitter