Records management meets data science

In order to manage your organisation’s digital heap you will need to make numerous interventions, at different times, in different repositories, for different purposes, on content that is at different stages of the records lifecycle. You are therefore going to need a tool kit of complementary methods and approaches.

For any particular  intervention, you have two key tactical choices to make. One comes from records management, the other comes from data science.

The key records management choice

The key records management choice is the level of aggregation at which you intervene. Corporate collaboration/document management systems and corporate email/messaging systems all have a structure. Teams and individuals create and receive content within a container (site/drive/account) that their organisation has provisioned to them.

Any intervention on any particular repository can either:

  • be targeted directly at all individual items across a repository OR
  • act on and within containers

The existence of a choice of levels of aggregation at which to act means that there is always a way of applying records retention and/or sensitivity categories within a repository.

If it is not feasible to act on individual items across a whole repository, and if acting on containers is not precise enough, then you can first act on all containers across the repository, and later intervene within a subset of those containers. The intervention could re-assign items that don’t fit the category assigned to their container.

The key data science choice

The key tactical choice in data science is between supervised and unsupervised learning approaches.

Supervised learning – training models to classify content

In supervised learning you build models. You teach an AI model what categories you want to apply to the target datapoints, and then test that it is applying them correctly. The classic mechanism of supervised learning is the classifier, which learns two or more categories and assigns each data point in the target data set to one of those categories. In a records management context you might seek to apply retention or sensitivity categories to content.

In data science the big strength of supervised learning is the ability to leverage and scale existing knowledge. You transfer your knowledge to the model, which applies it over a larger scale than humans could reach.

Unsupervised learning – using dashboards to understand content

In unsupervised learning you use AI to visualise a set of data. These methods teach you about the data. They surface features, trends, structure, relationships and/or groupings within the data – and you can then use that as a basis for making decisions on the data.  Examples of unsupervised approaches include:

  • analytics – surfacing of summary statistics about a dataset, or about groupings within a dataset
  • summarisation – textual summaries of a dataset, of groupings within a dataset, or of items within a dataset
  • entity extraction – extraction of the names of people, places, organisations and/or projects/programmes mentioned in a dataset or a subset of a dataset
  • cluster analysis –  assignment of each datapoint/item to a grouping in such a way as to maximise the similarity of all the items in each group

These methods can be brought together into a dashboard for a records team to analyse containers (drives/sites/accounts) and intervene within them.

In data science the big strength of visualisation/unsupervised learning is that it can generate insight, learning and new knowledge. If a retail or social media company wants to understand their customer base then running a cluster analysis of the buying or browsing behaviour of end users is a great way of doing it. The clustering might throw up unexpected similarities between particular types of customers/users. In a records management context if you want to understand the contents of an email account then running a cluster analysis within the email account is a good way of quickly seeing the main areas of activity that the individual was involved in.

The complementary nature of supervised and unsupervised learning

Unsupervised and supervised methods are complementary. They have different strengths and work well in different circumstances.

Supervised learning works well:

  • when the categories you wish to apply have clear boundaries
  • when one way of categorising the data is clearly superior to all others (or is mandated by regulation/law/policy commitment/ contractual commitment)

Unsupervised learning works well:

  • when you first need to understand the data before applying labels/categories
  • when the categories that you wish to apply have fuzzy boundaries (and hence it is difficult to teach a model how to apply them consistently)

The two approaches can be used in tandem. For example you can use unsupervised learning to increase your knowledge of a dataset, and later cement that knowledge in the form of a model that can classify future datapoints/items/containers.

A data scientist will need to intervene on different types of data sets, for different purposes, at different times. The fact that these two complementary sets of methods exist means that there is always a way that a data scientist can act on a data set to derive insight or to make the data itself more manageable.

Three viable options

When you combine the key records management choice with the key data science choice you get four options. One of the four options is not viable in a records management context. It is not feasible to use unsupervised learning to inform actions on individual items all across a repository.  That still leaves you with three viable options. You could:

  • use supervised learning to apply categories to individual items
  • use supervised learning to apply categories to containers
  • use unsupervised learning to inform action on containers and to inform interventions within them

This means that there always exists a viable option for you to carry out a records management intervention using data science methods in any corporate collaboration/messaging/document management system at any stage of the records lifecycle.

We can predict that each of these three options will be needed at one stage or another of the records lifecycle. We can also predict that no single one of these three options will be able to fuflil all records management purposes, in all repositories, at all stages of the lifecycle.

A key element of the building of a data science specific to the domain of records management will be capturing insights as to the trade offs involved in using these different approaches for particular records management purposes, and of the circumstances in which they work well/not so well.
Alternative approaches to applying AI for records management purposes

You are a records professional. Your organisation has in its possession a legacy repository to which no content has been added in the past five years. The repository contains over 100 million items (documents/messages etc.). No retention rules have been set on this content. You estimate that only 30% of the content has any ongoing value. 

The repository might be an old email system, an old SharePoint system, or a legacy set of network file shares left over from the days of on-premise computing. 

Let us imagine that you have decided to undertake an intervention, with the help of AI, to identify and remove the 70% of content within the repository that has no ongoing value. You have a cross disciplinary project team containing both records management and data science expertise. You have the backing of your organisation. 

How would you go about making the intervention?

Design choices

You have three key design choices to make when setting up the intervention. You have choices as to:

  • what level of aggregation you target your intervention at
  • what task you set your AI model/agent/set of agents
  • whether you use supervised or unsupervised learning 

You could target your intervention:

  • directly at individual items – the documents, messages etc. that make up the repository OR
  • at containers – the sites, accounts or drives that the items sit within 

You could task task the AI model with:

  • classifying – assigning each item or container to one of a set of pre-defined categories OR
  • clustering – in which the model looks for similarities between items (or between containers, or between items within each container) and groups like items with like

You could use:

  • supervised learning – where you transfer some of your records knowledge to the AI model so that the AI model can assign content to retention categories OR
  • unsupervised learning – where the AI model transfers information about content (or content groupings) to you so that you can use your records knowledge to assign that content to retention categories

In theory that gives you nine potential approaches, one for every permutation of these choices. In practice these choices are linked, and the choice in effect boils down to:

  • developing a classifier that looks at every item in the repository and assigns it to a retention category under your supervision OR
  • developing dashboards that can present you with analytical information about each container within the repository, and through which you can partition or cluster content within each container. This would enable you to understand and make retention decisions on each container. It would also enable you to intervene within any container that you choose to retain

Both these approaches scale up to repositories of digital heap scale. Both approaches enable you to wrest control of repositories that were previously seen to be unmanageable.

Lets see how you might use these two approaches to tackle a repository such as the one described at the start of this post.

Applying a classifier directly to every item

This set of approaches targets the intervention at the 100 million items that make up the repository. The aim is to develop a classifier that can evaluate each item and assign it to a retention category. You can define the scope of each category, and how many categories there are. For example: 

  • you might define a set of retention categories that correspond to different areas of activity of your organisation, each with its own accompanying retention rule OR
  • you might simply define two categories, one for content of ongoing value and the other for content without ongoing value

This approach uses supervised learning. Your aim is to teach the model the retention categories that you have defined. You might do this through one or more of the following:

  • writing a set of rules that define the features likely to be present (and/or absent) in items responsive to each category
  • collating a training pack of documents responsive to each category (and of documents that are not responsive, but are superficially similar) 
  • prompting a large language model with your rule set for each category, and providing the model with access to your training pack
  • iteratively working with a large language model to identify and build a training pack.

You will deploy the model once you have satisfied yourself that, when presented with a sample of items from the repository, it correctly categorises enough of the items to meet whatever threshold you have set for success. 

Faced with a repository of 100 million items, the model would make 100 million decisions, with each decision assigning an item to a category. You might aim to check a statistically significant sample of those decisions, on an ongoing basis, to ensure that the model continues to meet or exceed the success threshold set even when faced with new content.

Analysing every container and intervening within those you wish to retain

When using the second set of approaches you intervene through the containers that content sits within. A container is a site, account or drive that an organisation provides to a team or individual to enable them to accumulate content within a corporate system. All corporate multi-purpose collaboration, document management and messaging systems use some form of container:

  • in a SharePoint repository every item/document sits within a site
  • in an email repository every message sits within an email account
  • in a shared drive repository every document sits within a drive

With a container based approach you might split your AI intervention into two stages:

  • in stage 1 you might use AI to help you find the most valuable containers in the repository (so that you can remove the rest)
  • in stage 2 you might use AI to look for the least valuable content within each of those valuable containers (so that you can remove trivial content from the containers you have chosen to keep)

So in our imaginary scenario, with our notional target of removing 70% of content:

  • you might, in stage 1, seek to identify the most valuable 35% of containers (and delete the rest)
  • in stage 2 you might identify the least valuable 14% of content within each of the remaining containers, and remove it

After completing these two stages you would be left with approximately 30% of the content of the original legacy repository.

This set of approaches uses unsupervised learning. You would use a dashboard to look at each container. On the basis of the analysis available to you in the dashboard, you make a retention decision on the container, and in phase 2 you intervene in those containers that you chose to retain.

The first role of AI in this approach is to extract or reconstitute key information about the container. This might usefully include:

  • contextual information about the container – for example the identity and role of the team or individual to whom the container was provisioned
  • summary information about the container– for example the date range within which content was added, the  entities (places, organisations etc.) frequently mentioned within it, numbers of items within the container, volumes of different filetypes within the container etc

The second role of AI in this approach is to provide you with a means to divide the container into smaller chunks. For example AI could be used to

  • partition into sections – if there is significant structure within the container, for example a folder structure, the AI could suggest partitions of that structure into sections
  • cluster into clusters – if there is no significant structure within the container (as is often the case within email accounts) then AI could be used to cluster the contents, so that similar items are grouped together
  • create time based divisions –  it could partition messages within an email account by year depending on the date on which each message was sent or received. It could partition folders (or groupings of folders) within a folder structure depending on the year in which content was last added to the folder/folder grouping 

The process of arriving at a set of sections/clusters that are suitable is an iterative one. You will almost certainly want to change the partitions/clusters initially suggested by the model, for example by changing the boundaries of the partitions, or changing the numbers of clusters generated. Once you are happy with the sections/clusters, you could identify the clusters/sections that relate to the less important aspects of a team’s work, and remove them.  

Combining both sets of approaches

The two sets of approaches have different strengths. This makes them complementary to each other – each can compensate for the weaknesses of the other. 

As a general rule developing a classifier is at its most effective when:

  • the categories of content that you want to find are relatively evenly distributed across the repository AND
  • you need to treat all content of a category in the same way regardless of the role of the team or individual that created or received it

In such circumstances it should be both feasible and useful to develop a classifier that can be used across an entire repository.

In contrast working through containers is at its most effective when:

  • the categories of content that you wish to find are not uniformly distributed, but instead are ‘clumped’ within certain places within the repository, for example in the sites/drives/accounts of individuals or teams playing particular roles AND
  • your treatment of a category of content would vary depending on the role of the team or individual that created or received it.

If you adopt one approach and find there is an obstacle in your way, then incorporating some aspect of the thinking and the methods of the other approach might help you overcome that obstacle.   

AI and the strengthening of records management approaches

One way of thinking through the question of how AI can augment, strengthen and extend records management, is to ask:

  • what are the most effective approaches that we already have without AI?
  • what are the strengths of the best approaches and how far do they get us?
  • what are the limitations of even the best approaches?
  • what therefore is the gap that AI (and data science techniques/algorithmic approaches more generally) can most usefully address?

Existing approaches

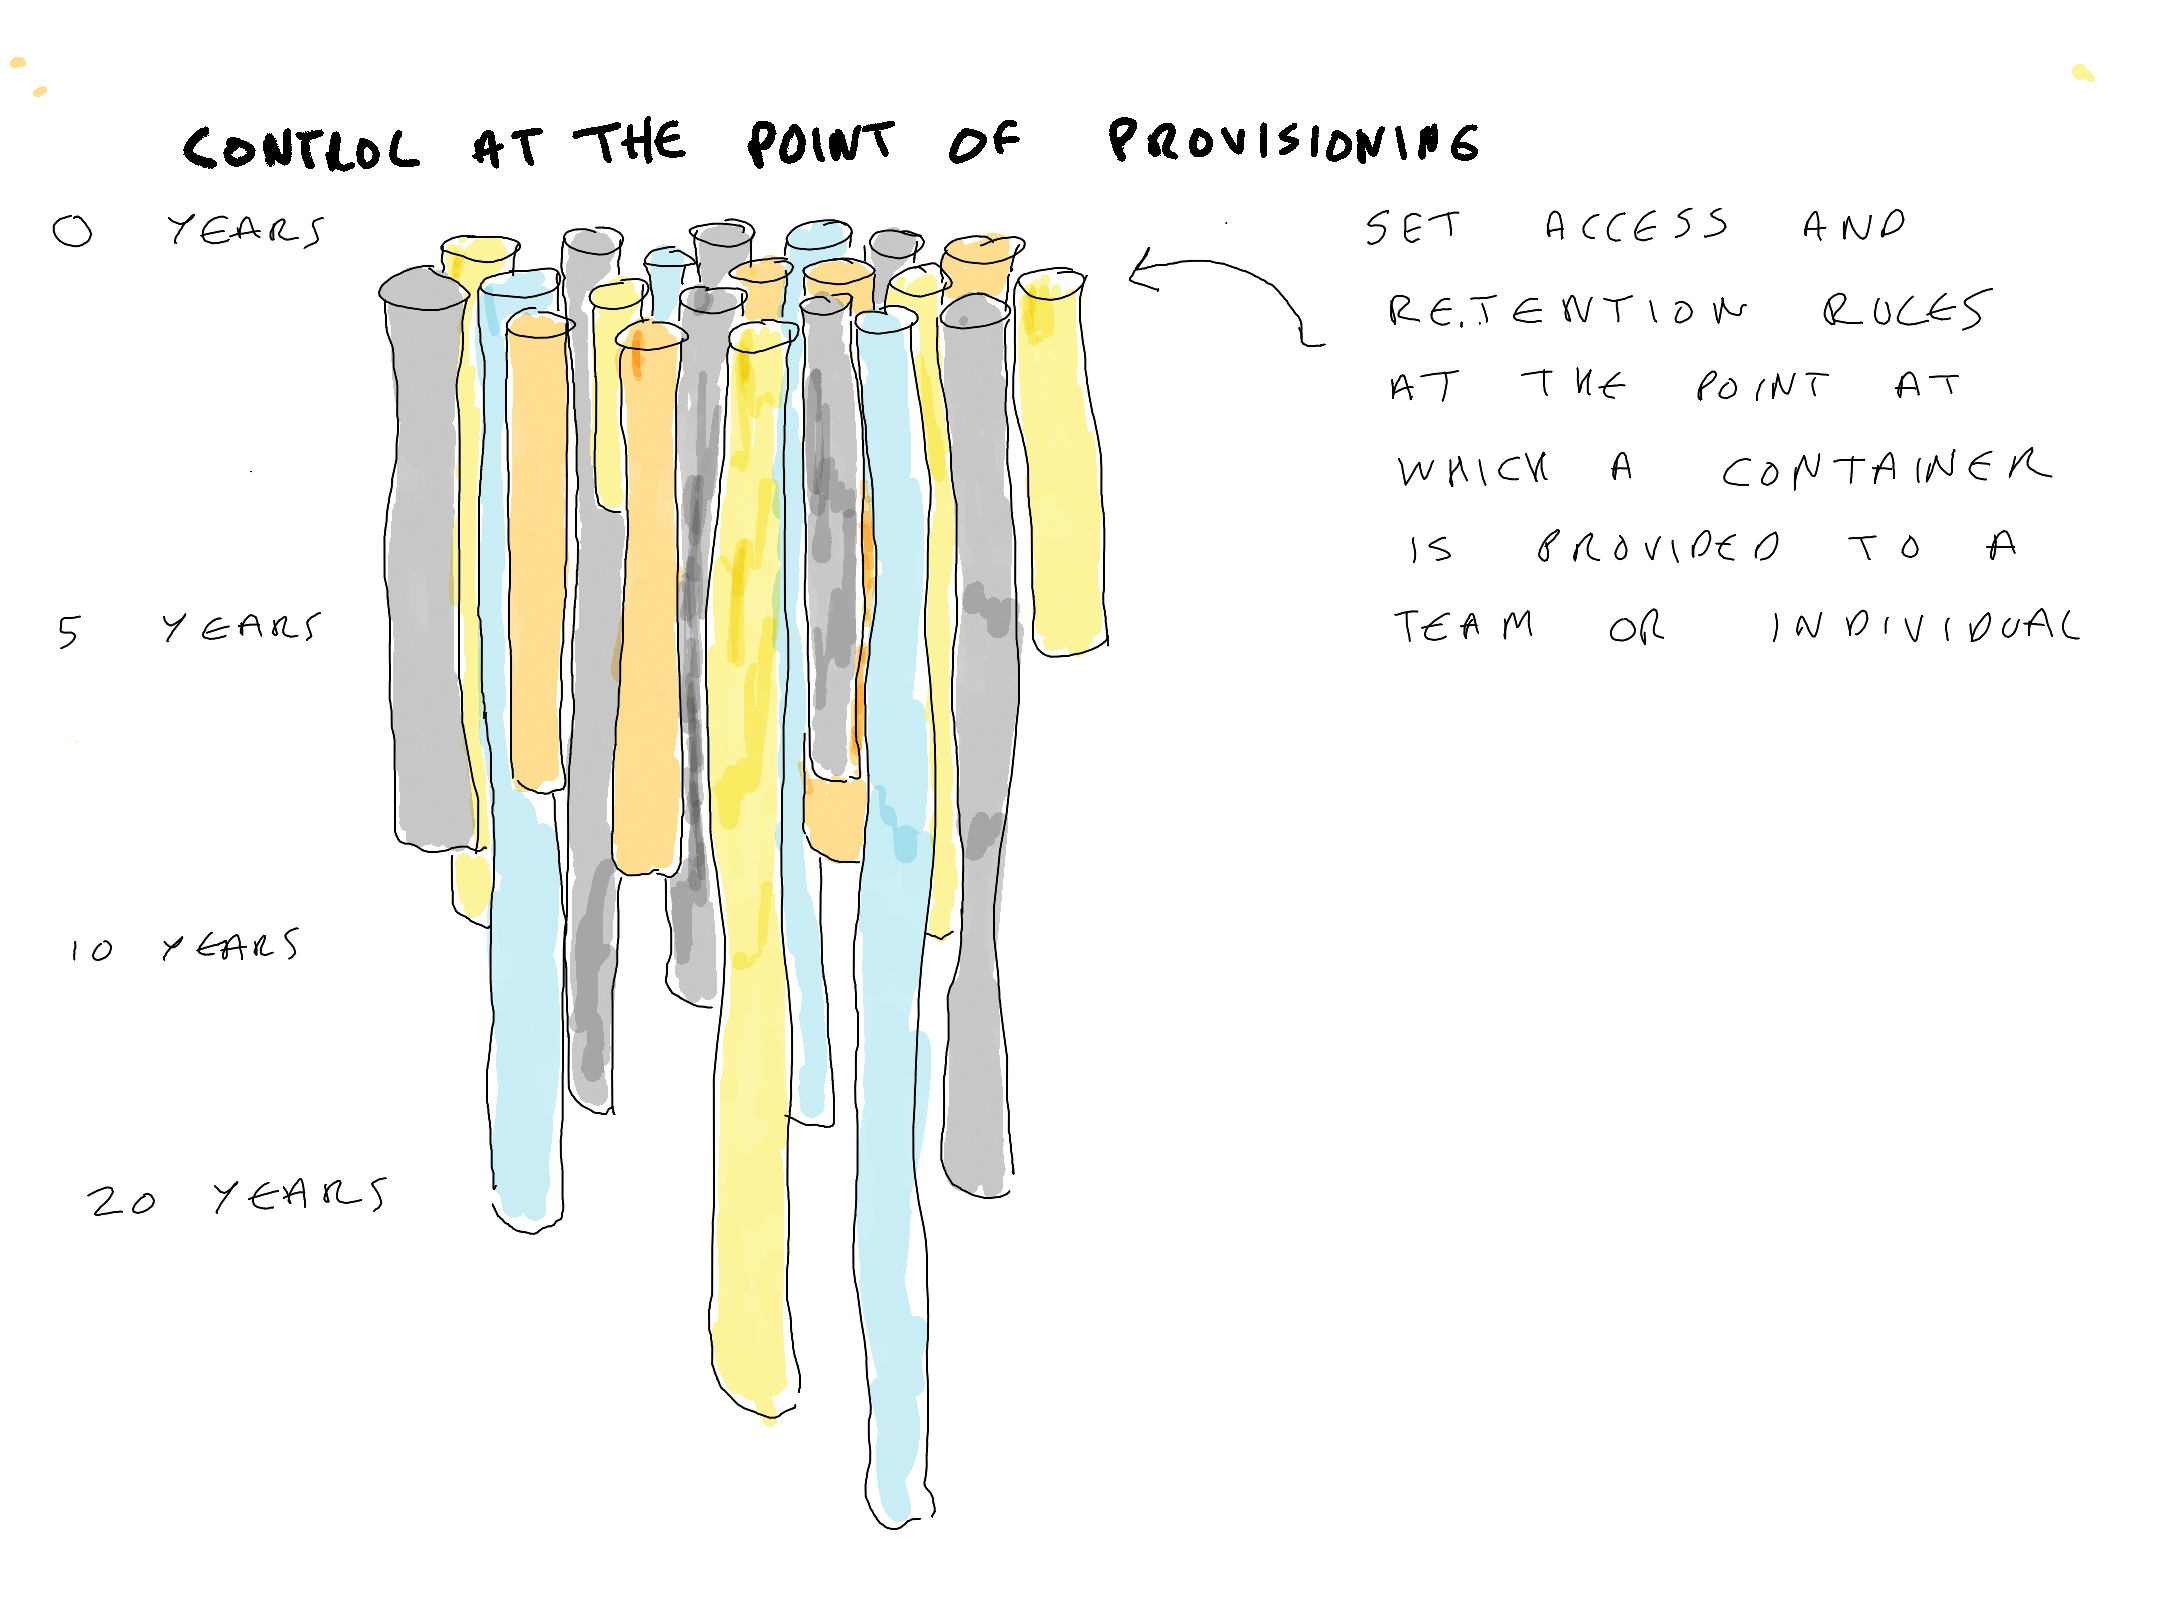
For the past decade records management has been dominated in many countries by large cloud suites (such as Microsoft 365 and Google Workspace) that provide generic collaboration and communication applications that all or most staff can use for all or most of their activities. The most effective records management approach during this period has been ‘control at the point of provisioning’.

Control at the point of provisioning involves acting to set default access permissions and retention rules on containers (such as sites, accounts, drives etc.) at the point at which they are provided to a team or individual. Ideally it also involves capturing sufficient context about a container to enable an information manager at a later date to understand:

  • who that container was provisioned to
  • what role the team or individual played within the organisation

Control at the point of provisioning is an effective strategy against the build up of uncontrolled digital heaps because:

  • it puts control in the hands of records and information professionals – its success is not dependent on end-user effort/buy-in. The provision of containers is a process that can be controlled by records and information management teams
  • it is comprehensive – if every SharePoint site has a default retention rule then every item of content within SharePoint has a default retention rule (because every item sits within a site). If every email account has a default retention rule then every email message has a default retention rule (because every email sits within an email account)
  • it is extensible – this approach can be applied in any corporate all-purpose collaboration or communication application because all such applications partition content into containers. Every one of the applications (workloads) within Microsoft 365 partitions content into containers
  • it applies retention rules to meaningful groupings of content – it manages content in-place within the context of the container within which it was created, accessed and used
  • it is predictable – it helps set the expectations of end-users with regard to how long the content they contribute to the container is likely to be kept
  • it is compatible with any viable form of information architecture – it can be applied in systems that are hierarchical in nature (like SharePoint or EDRM systems). It can also be applied to systems that are modular in nature (like MS Teams, MS Exchange, Gmail etc.). These applications are modular in the sense that each MS Team and each email account is a stand alone object that is not nested within a classification structure of any kind

Extending a control at the point of provisioning approach

Let us imagine that an organisation has deployed Microsoft 365 and has applied control at the point of provisioning across all the applications within it. They can therefore be assured that every container (Team/SharePoint site/OneDrive/email account) has a default retention rule set on it. What further capabilities might they want from AI to improve and refine their ability to manage their content over time?

There are three limits to control at the point of provisioning:

  • it doesn’t deal with legacy –  by definition you can’t retrospectively impose control at the point of provisioning 
  • it is only as precise as the containers that are being provisioned 
  • it does not typically involve a structure that enables an organisation to group like containers with like and make sense of the whole

These three limitations provide a clue as to the capabilities that such an organisation might want from AI (and data science/algorithmic approaches more generally).  The organisation might want:

  • the capability to analyse and assess legacy containers to support the retrospective assignment of a default retention rule to each container (legacy SharePoint sites, legacy shared drives given to particular teams, legacy email accounts etc.)
  • the capability to identify sub-groups within containers – for example the organisation might benefit from being able to:
    • identify content within each container that does not merit the default retention rule set on it (an obvious example is unsolicited, trivial or social emails in email accounts)
    • create sub-clusters of similar content within a container, which correspond to different areas of work. This may enable them to apply finer-grained retention rules or access permissions within a container
  • the capability to group and classify containers -for example the organisation might benefit from being able to:
    • group like containers with like (and assign a name/description to the grouping that identifies what the containers have in common)
    • group like groupings of containers with like (and to iterate this process to either build a corporate records classification from the bottom-up, or to reach a point at which they can link groupings to a classification structure that they have built separately)

Relationship with other potential approaches

There exists many possible strategies for deploying AI in support of a records management programme. Control at the point of provisioning is an approach that sets default retention rules at the container level. AI offers the opportunity to try entirely new strategies – for example AI could be used to set retention rules on items without reference to the containers that they were created and used in. Or it could be used to assign items to an entirely new set of containers for the purposes of applying retention and/or access rules. This post is based on the assumption that:

  • some organisations may wish to maintain a continuity of strategy as they transition to the greater use of AI to support the application of retention rules
  • containers shape the way that content accumulates within corporate collaboration and communication systems. Giving containers an ongoing role in the governance of content offers benefits in terms of maintaining predictability over time and maintaining content within the context it was created

The intuition behind this post

This is the third in a series of posts that attempt to articulate intuitions about records management for data scientists. The intuition behind this post is as follows:

Control at the point of provisioning involves setting default retention rules and access permissions on containers at the point at which they are provisioned to individuals and teams. It has proved to be an effective way of preventing the build up of uncontrolled digital heaps.

The previous posts in this series are:

All views in this post are my own

The original order of digital records

One of the founding principles of archival science is that the original order of records should be respected. If an organisation was to retrospectively restructure a set of records, in a way that obscured or lost the original order, then this would risk giving a misleading picture of:

  • how content had accumulated
  • how people had worked
  • who had known what, when, in relation to the work that the records arose from

One of the great strengths of digital (as opposed to analogue) records is that they can be presented or viewed in so many different ways and orders. Does the principle of respect for the original order of records still hold true in the digital age? Is a digital repository likely to have one structure that will tend to act as the best vehicle for the application of retention rules, the taking of disposition actions and the making of appraisal decisions on content within the repository? We can use a simple thought experiment to show that the principle does indeed still hold true.

Thought experiment to show the original order of digital records

Imagine you are a records or information manager, reviewing a legacy digital repository (think of a legacy shared drive (fileshare), or a legacy SharePoint system, or a legacy email system). You could reorder that repository in an unlimited number of ways, at the press of a button, with a few lines of code, or with a well-engineered prompt.

Now travel back in time a little and imagine yourself in the position of an end-user who is using a shared drive, a SharePoint site, an email account or in the course of their work. They would have been able to re-order content within that particular shared drive, that particular SharePoint site, or that particular email account. But it is unlikely that they would have been able to re-order content across the entire repository of shared drives, the entire repository of SharePoint sites or the entire repository of email accounts.

In corporate systems such as shared drives, SharePoint systems, email systems and the like, end-users are given partial access to the system. They can contribute to one or more containers within the system, but not to the rest. They can access one or more containers in the system, but not the rest.

This partitioning of the system is necessary in any all-purpose system that can be used by all or most of an organisation’s staff to conduct all or most of their business activities. It is necessary because in a large organisation with a sophisticated division of labour, it is not normally advisable to allow individuals to be able to view, edit and contribute content in all parts of the system.

The importance of containers within digital repositories

The order that has the most influence on how content accumulates in a digital system is the order which determines who can contribute content where, and the order that sets default access permissions on content. To find the original order we therefore have to find the groupings on which default access permissions were set within the system. This order also strongly influences how people behave in a system. People are likely to alter their communication style, and alter the types of information they are willing to share, depending on the access permissions of the particular container they are contributing to.

Content in corporate digital systems tends to be partitioned into containers within which a defined individual, team or work group can contribute content:

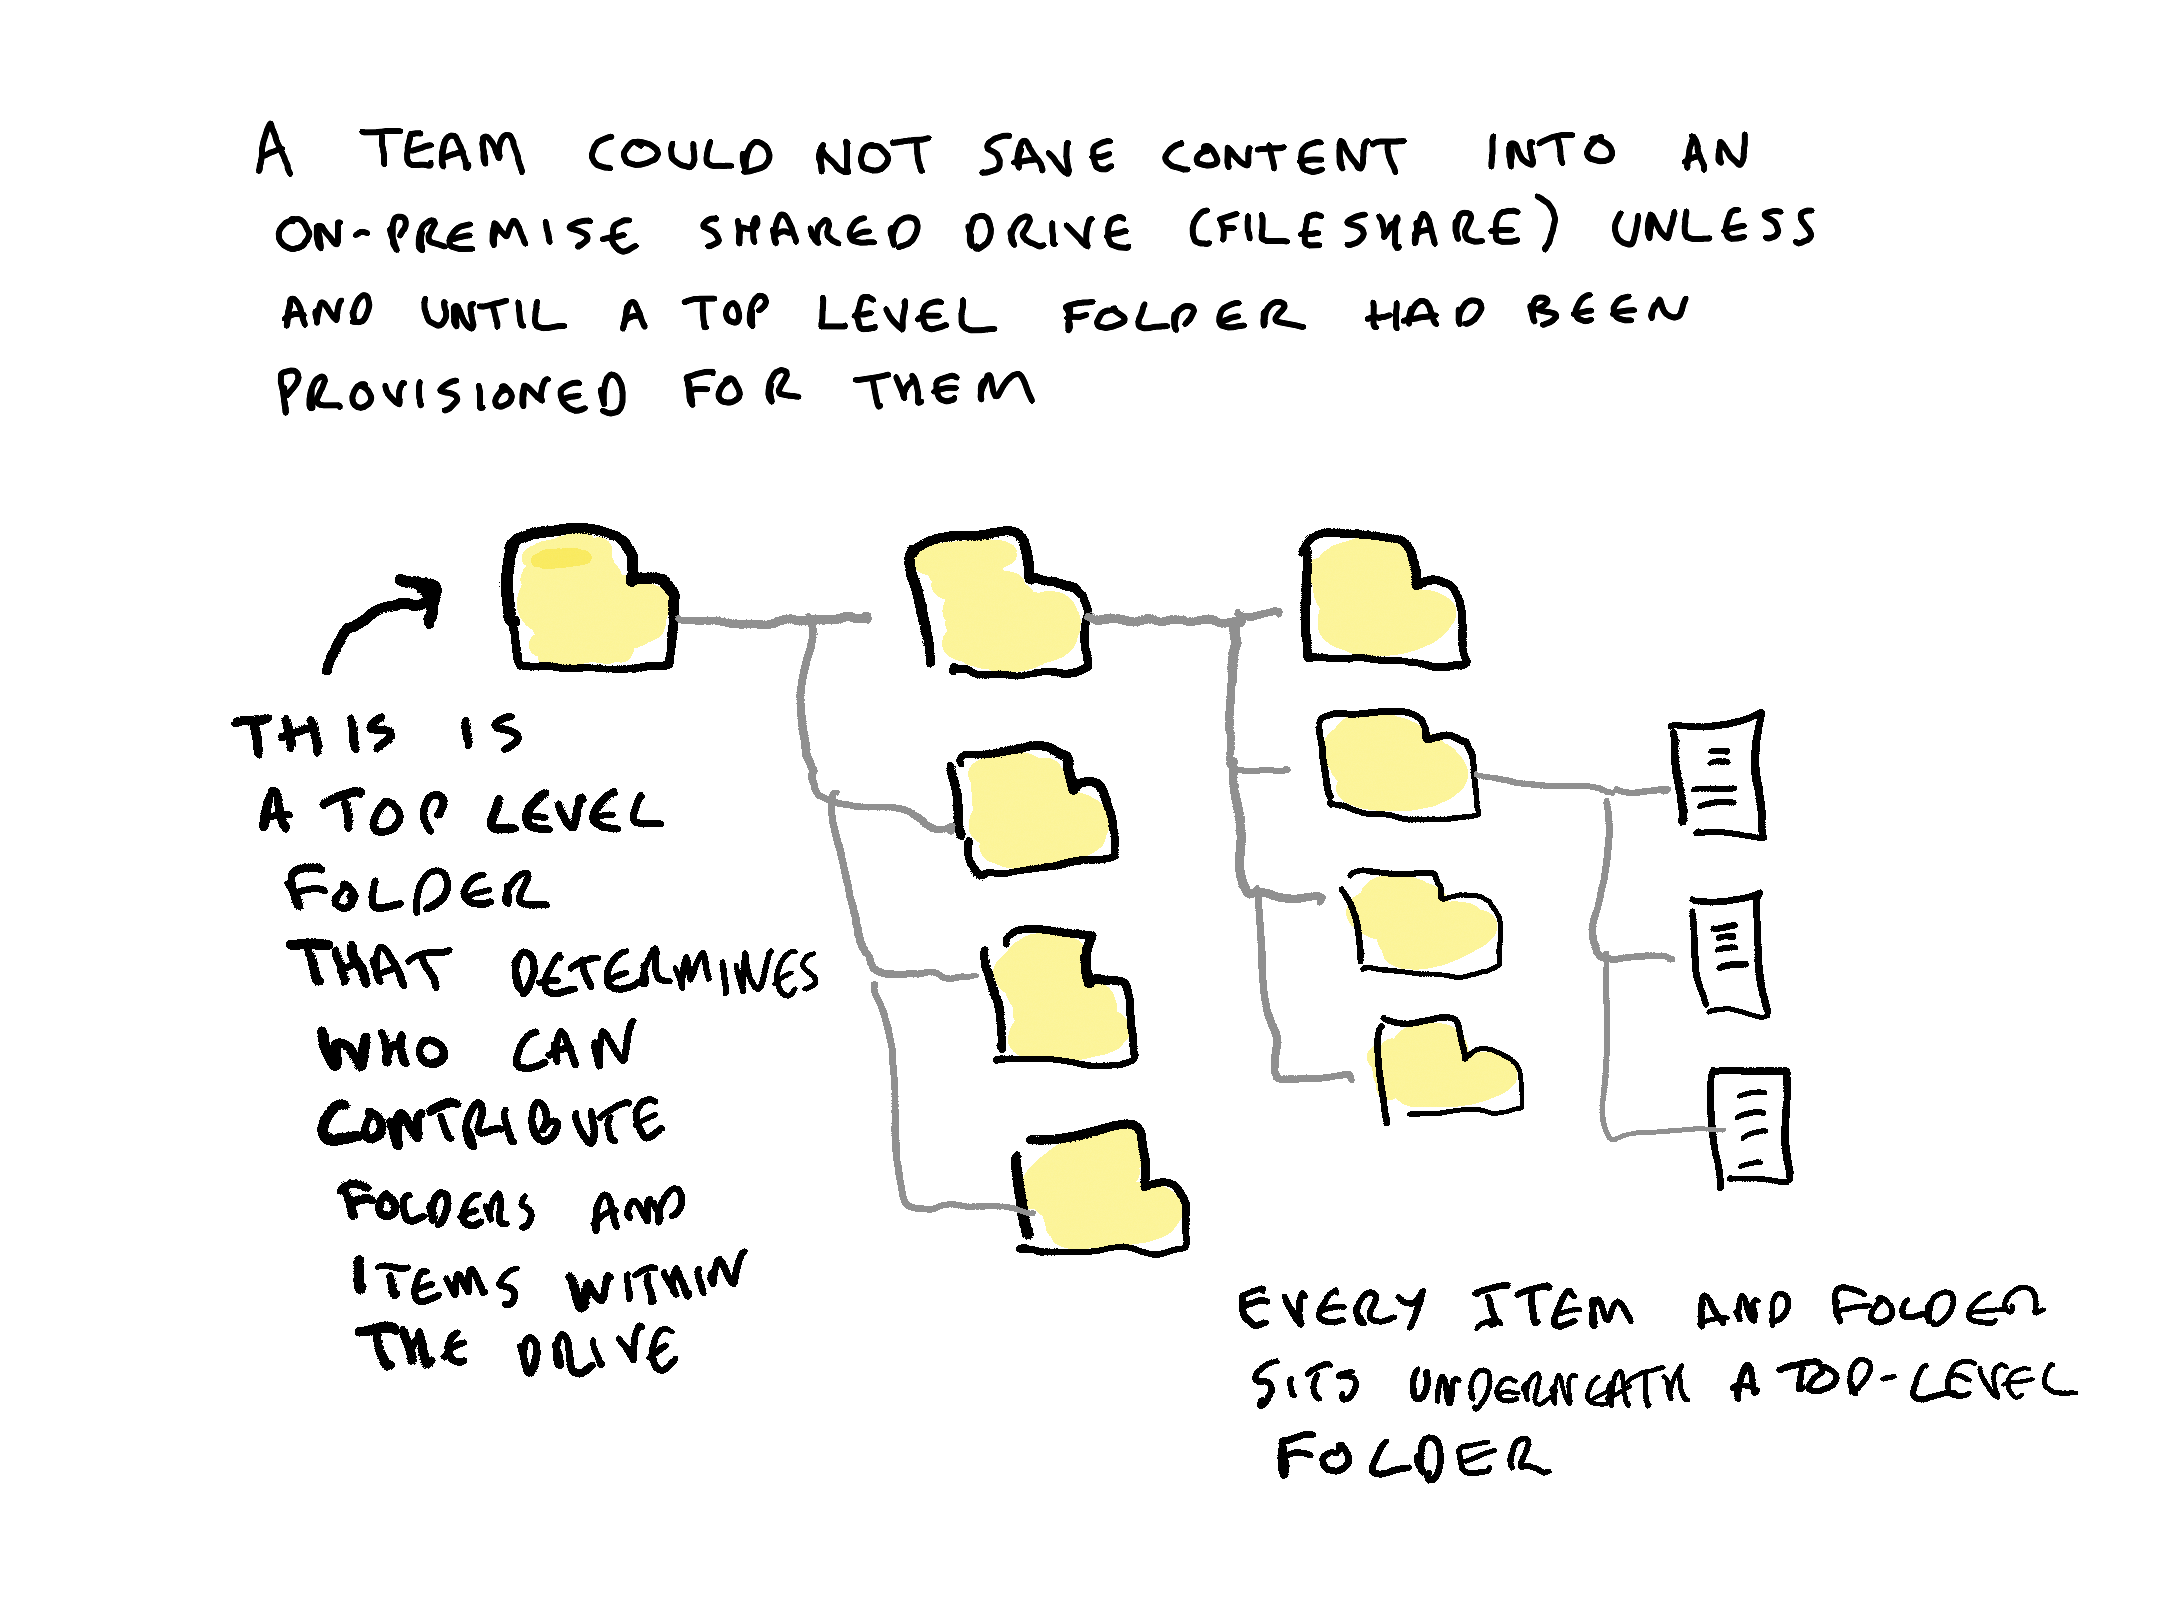
  • in the on-premise world before the coming of cloud suites, a teams could not work in shared drives (fileshares) until someone had provisioned them a top level folder
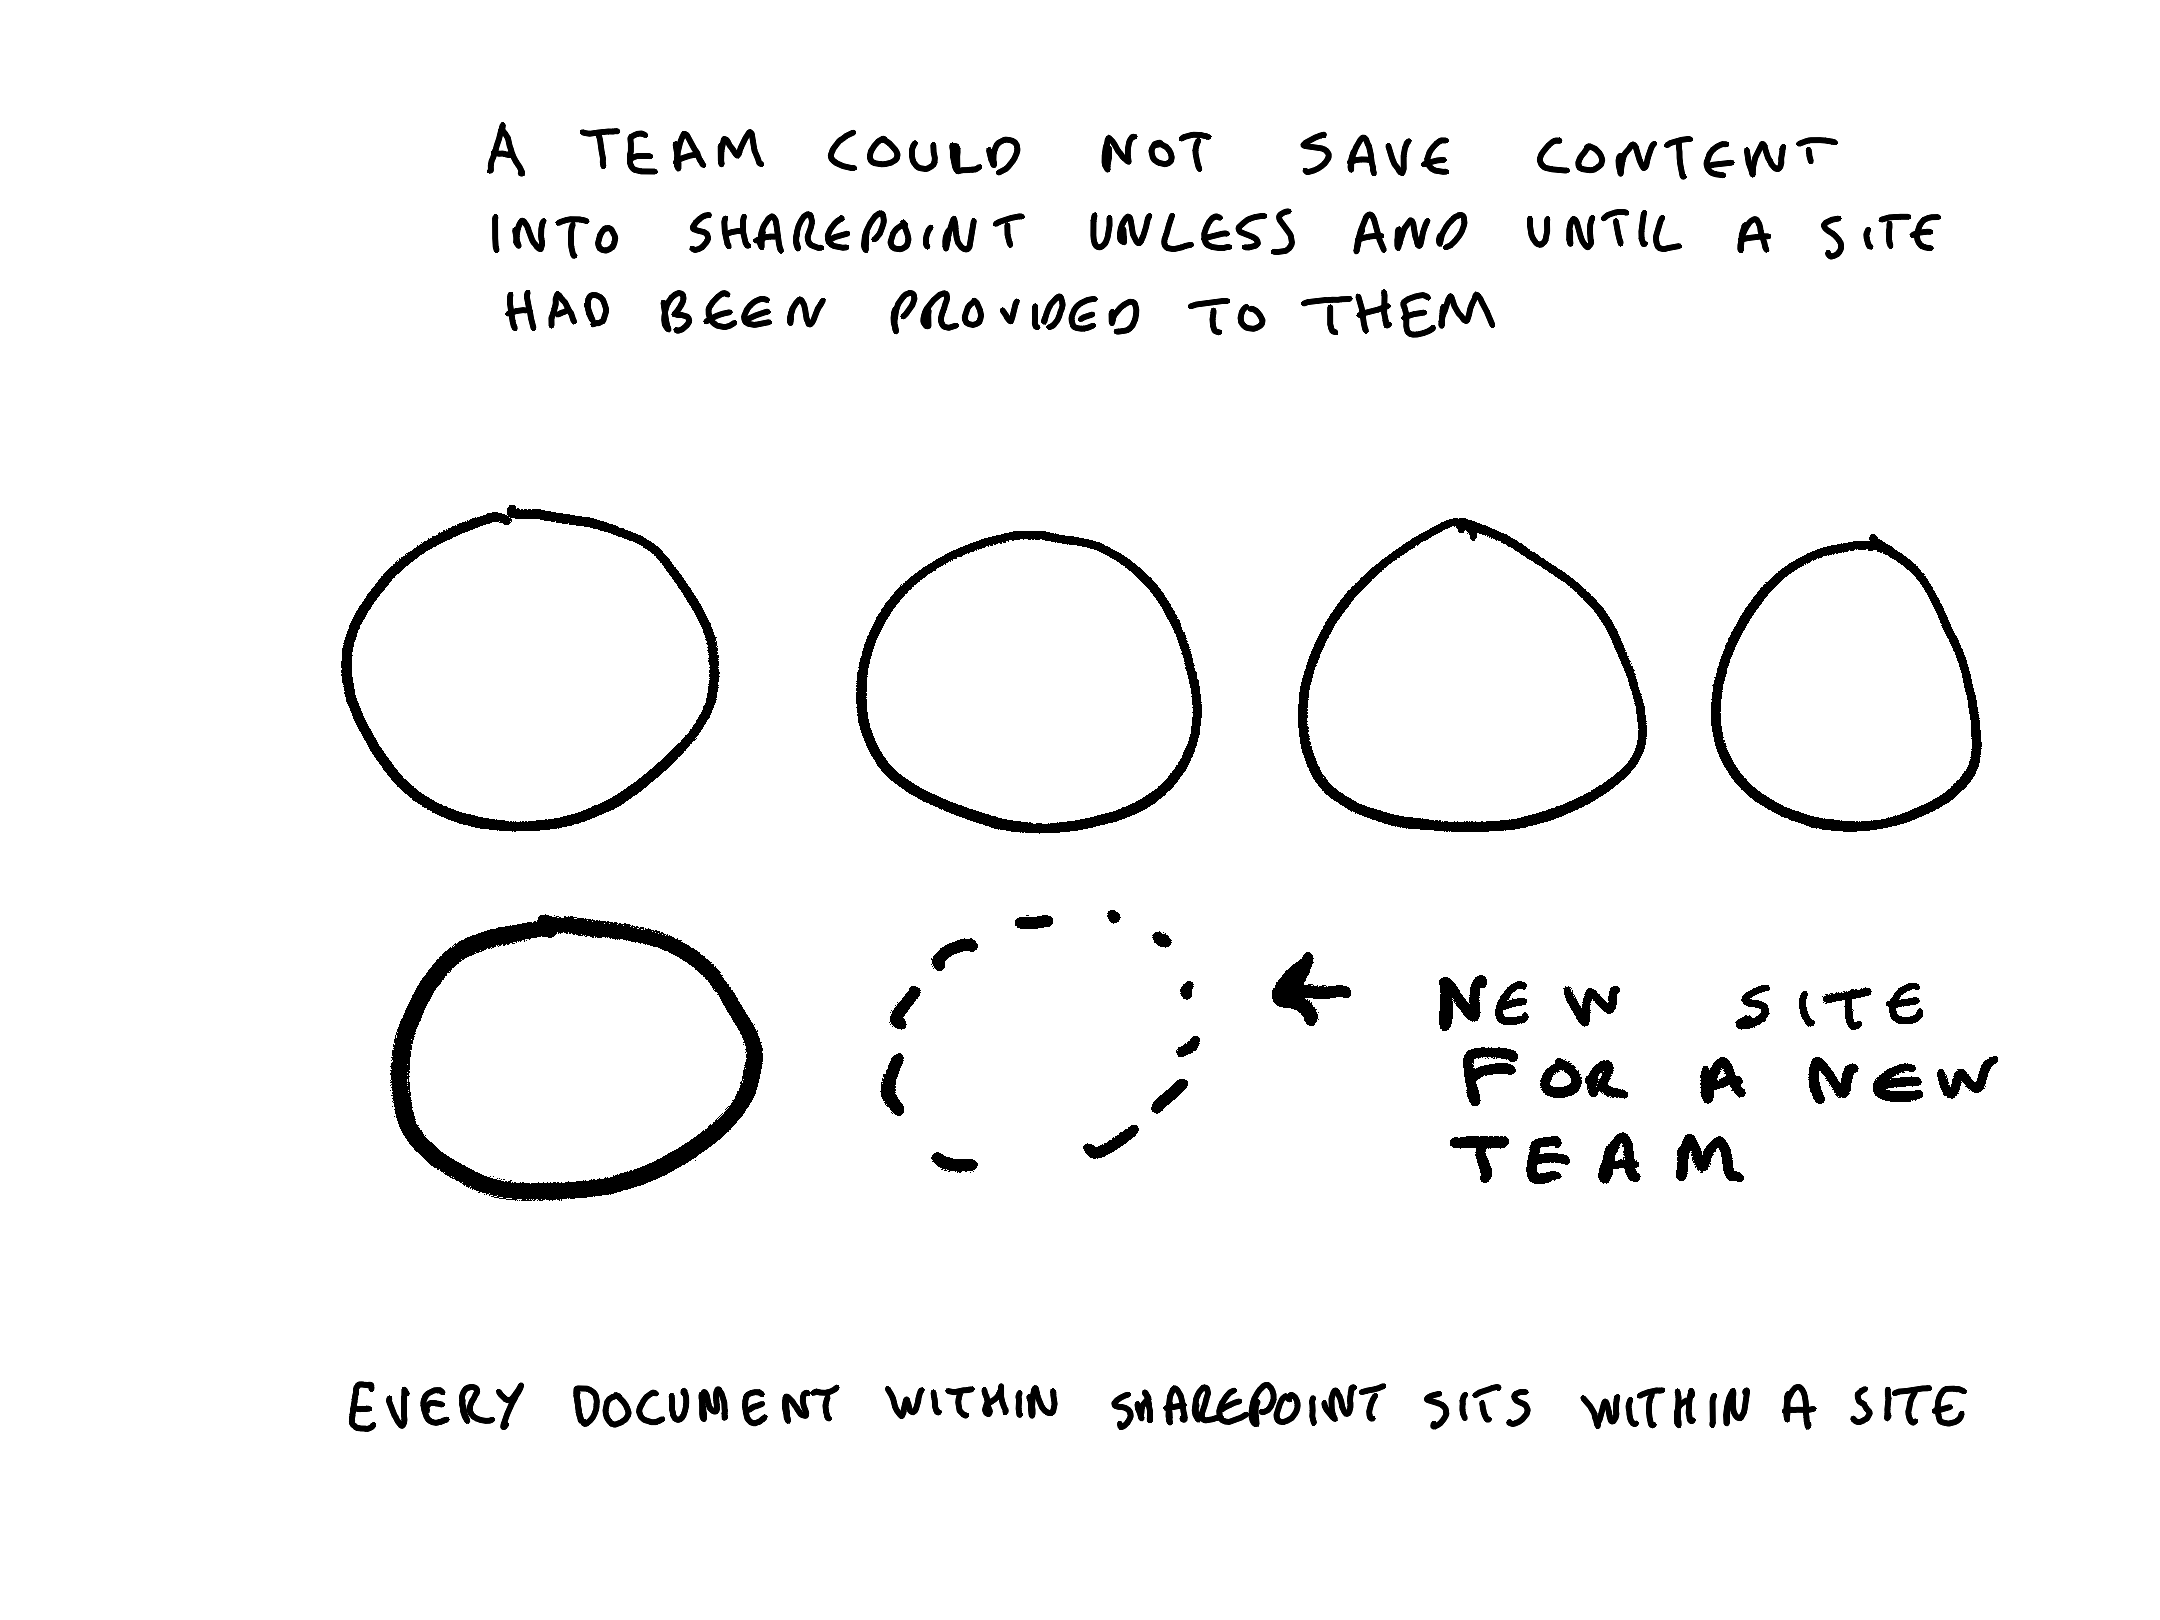
  • a team cannot work in SharePoint until someone has provisioned them a SharePoint site
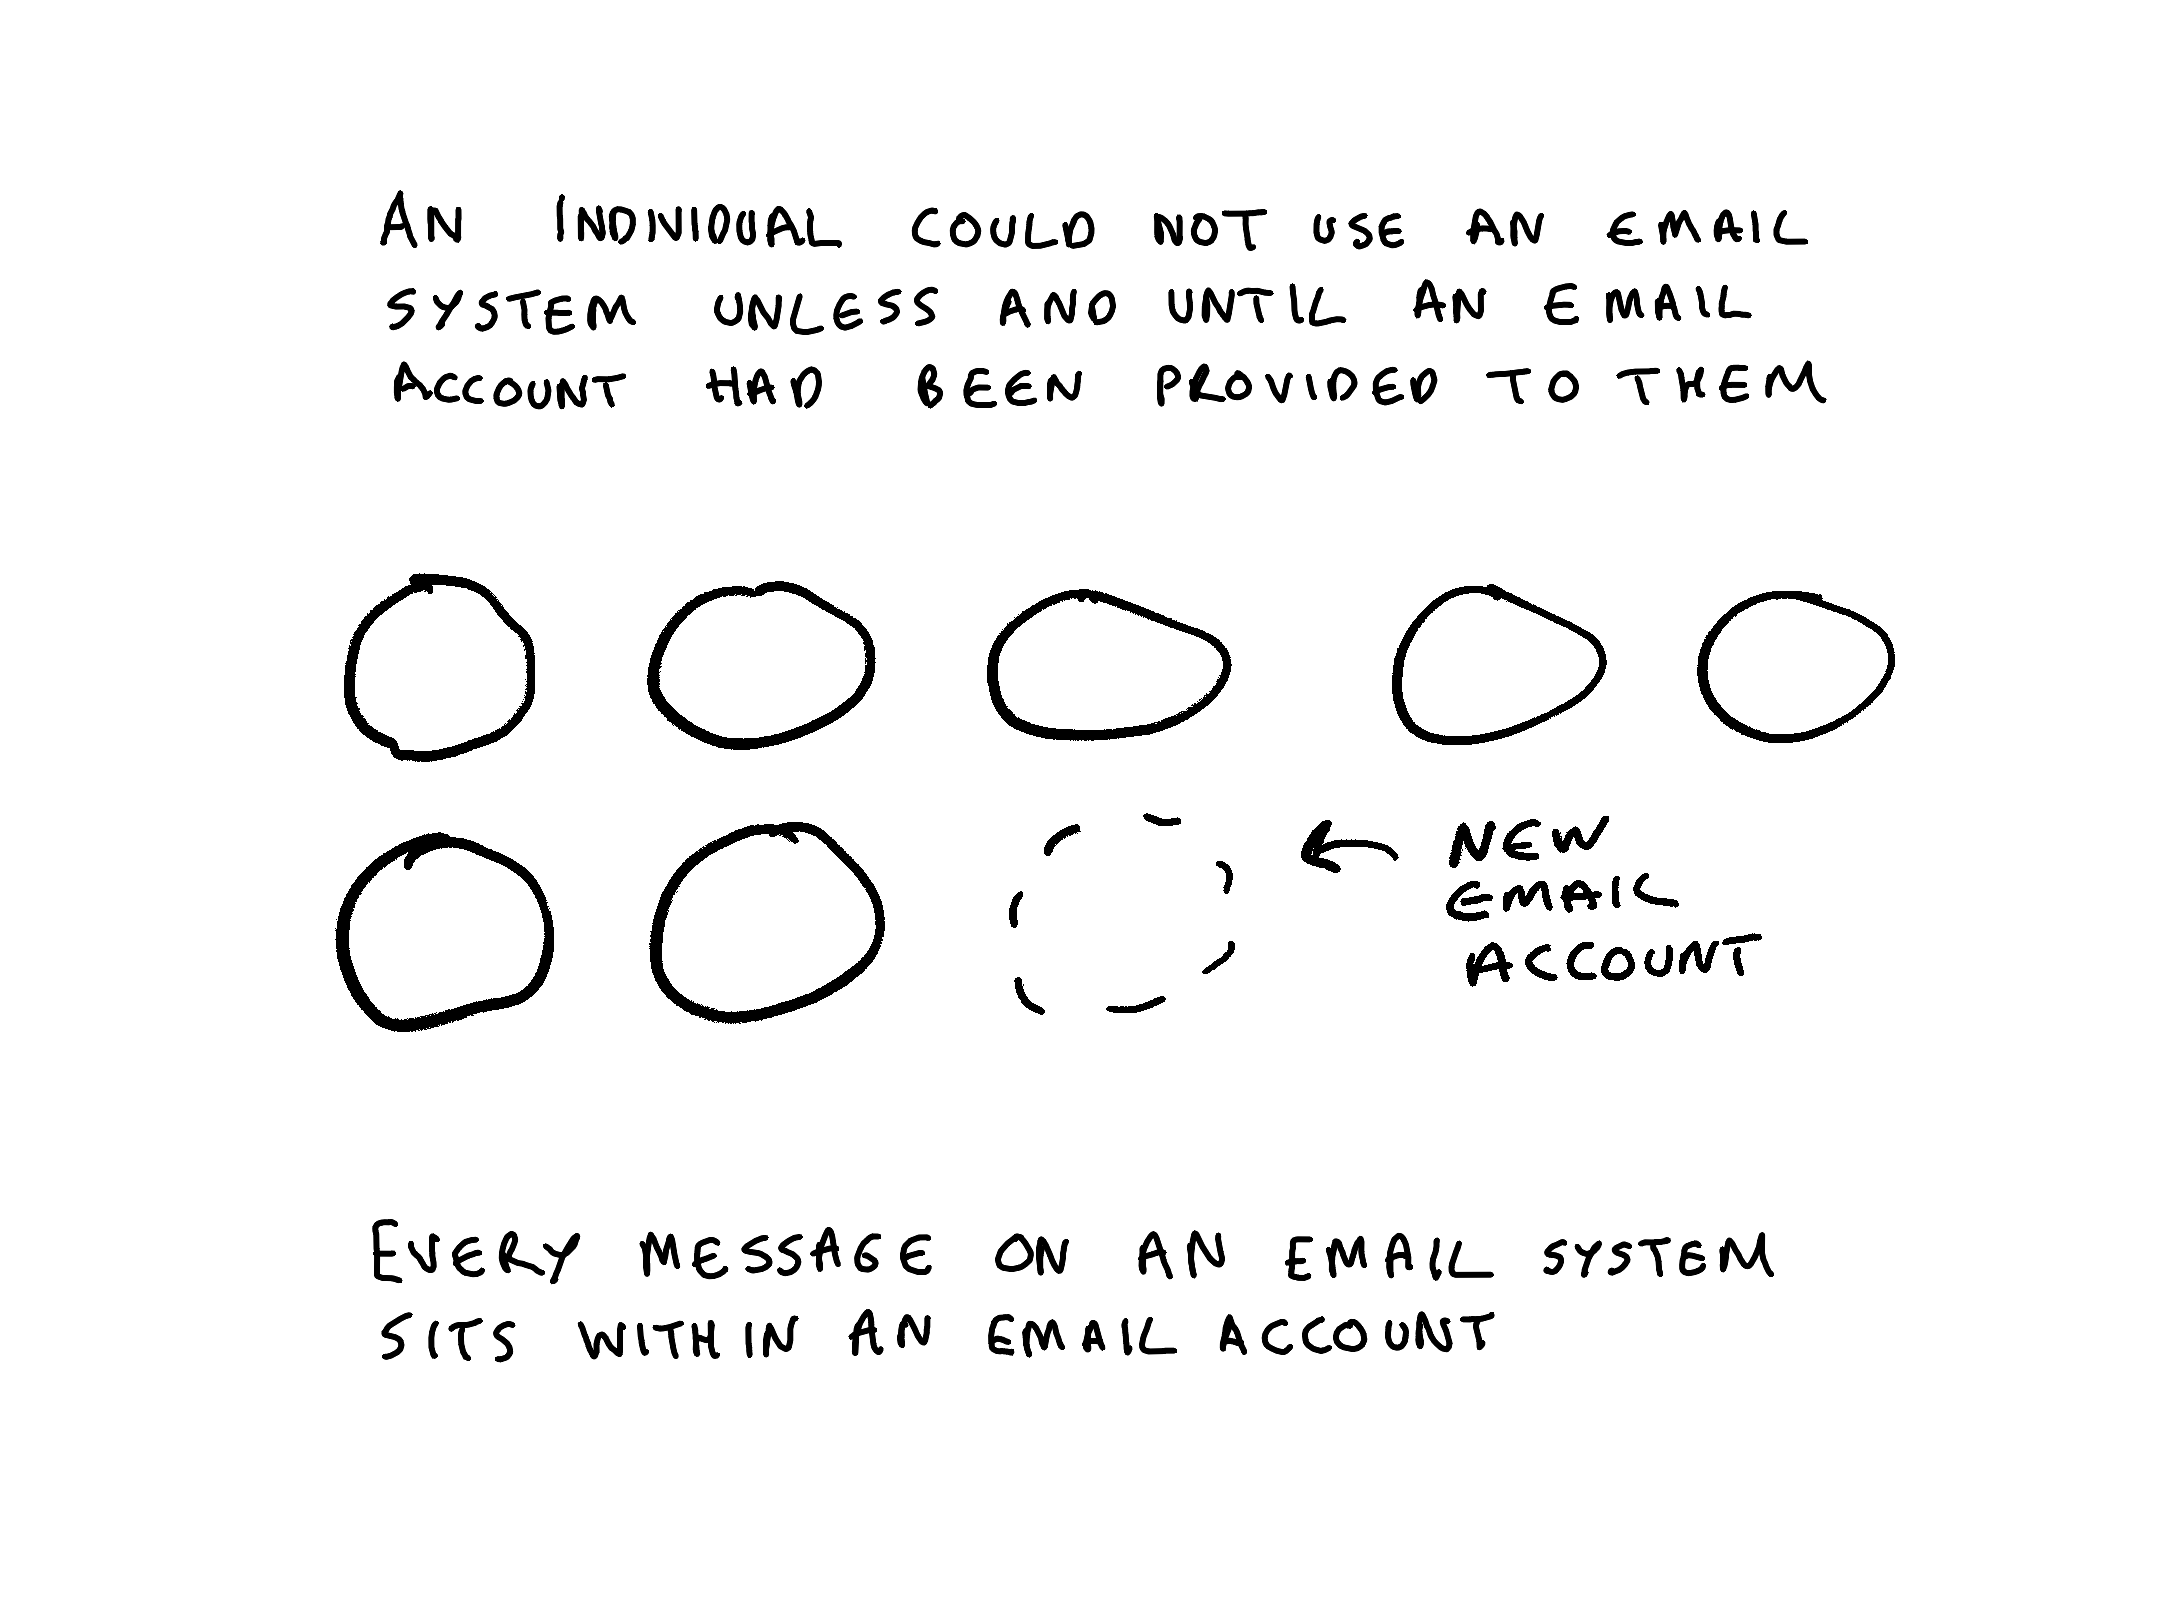
  • an individual cannot work in an email system until someone has provisioned them an email account that they can use

Every item within a corporate all-purpose digital system has to have an access permission attached to it from the first moment that it is saved into a system. Therefore there needs to be some way of applying default access permissions to all content. Containers are the vehicle through which default permissions are applied. Every item therefore must sit within a container.

In a SharePoint system every document sits within a site. In an email system every message sits within an email account. In a on-premise shared drives every item sits underneath a top level folder. In Microsoft 365 , MS Teams uses SharePoint, OneDrive and Exchange as its repositories. Every document, post or message contributed to a Teams channel or chat conversation is stored in either a SharePoint site, a OneDrive site or an Exchange email account.

This means that if a records/information manager has a means of acting on containers then they have a means of acting on all items within the repository. This makes containers a very powerful way of controling content in live digital repositories, and of scaling up actions and decisions on content in legacy digital repositories.

The intuition behind this post

This is the second in a series of posts that attempt to articulate intuitions about records management for data scientists. The intuition behind this post is as follows:

Corporate all purpose digital systems are systems that can be used by all or most members of staff to work on all or most of their activities. Examples include email systems, collaboration systems, shared drives (fileshares) etc.

Content in such systems tends to be partitioned into containers within which a defined individual, team or work group can contribute content.  All items within the repository will have been contributed to one of those containers.

The previous post in this series is Intuitions about records management for data scientists

(all views in this post are my own)

Intuitions about records management for data scientists 

Data science techniques can be applied in any domain (medicine, psychology, marketing, baseball, records management etc.). In order for data science techniques to be used effectively, a combination is needed of:

  • sound intuitions about how these these techniques work
  • sound intuitions about the domain they are being applied to

Imagine you are working with a data scientist on a project to use data science techniques for a particular records management purpose on a particular set of content. You might need their intuitions on data science. They might need your intuitions about records management.  

Both sets of intuitions would be subjective. No two data scientists and no two records managers would give the same set of intuitions about their disciplines. But this does not make them any less valuable. Not only would your intuitions give your colleague an insight into your discipline, they would also give them an insight into how you think, about what matters to you, and about what lens you will be using to look at the problem situation.

Intuitions about data science

Think of all the data science techniques that you have heard mention of: linear regression, classification, clustering, topic modelling, regular expression matching, entity extraction, graph algorithms, language modelling etc.. They are each executed by some algorithm written in some programme language. They are each underpinned by some combination of pure mathematics, statistics, probability and/or logic.

In lectures or podcasts you can hear data scientists converse about such techniques by conveying their intuitions about them.  For example the intuitions that:

  • Clustering algorithms can assign data points (customers, documents, properties, baseball players etc. etc.) to a position in a multi-dimensional virtual space. In doing so they can cluster together data points that have similar features (customers with a similar purchase history, listeners with similar musical tastes, baseball players with similar strengths etc. etc.) 
  • Graph algorithms can make connections between people, objects, and topics. For example, given an organisation’s email system and document management system as inputs, such algorithms could identify, for any given individual end-user, who that end-user most frequently communicated with, about what topics and with reference to which documents.
  • Large language models have a statistical understanding of how each language they have encountered works. They understand how frequently words occur in the language, how frequently words appear with other words and how the presence of one word or combination of words influences the likelihood that any other word or combination of words will appear. They can therefore calculate, to a high degree of probability, a good answer to any question on any subject, provided that they have been given enough relevant information in their training or at the point the question is asked.

You might need to contribute to a conversation on which data science technique(s) to use on your problem situation. If you have good enough intuitions about those techniques then you can make such a contribution without having to understand the underpinning maths or the executing code.

Intuitions about records management

In order to maximise the value of data science (and data scientists) to records management, it is important for us as individuals and as a profession to convey intuitions about the domain of records management.  

We can make a start on this by articulating some general intuitions about records in any age. The best source for this is archival science, which contains a set of intuitions that have been building up for well over a century (many people date the foundation of archival science to the publication of what is commonly called the ‘Dutch manual’ in 1898).

Here are what I consider to be the most important intuitions from archival science: 

  • Records arise when people conduct activities – in an information based society records are like water – vitally important but ubiquitous rather than special or unusual
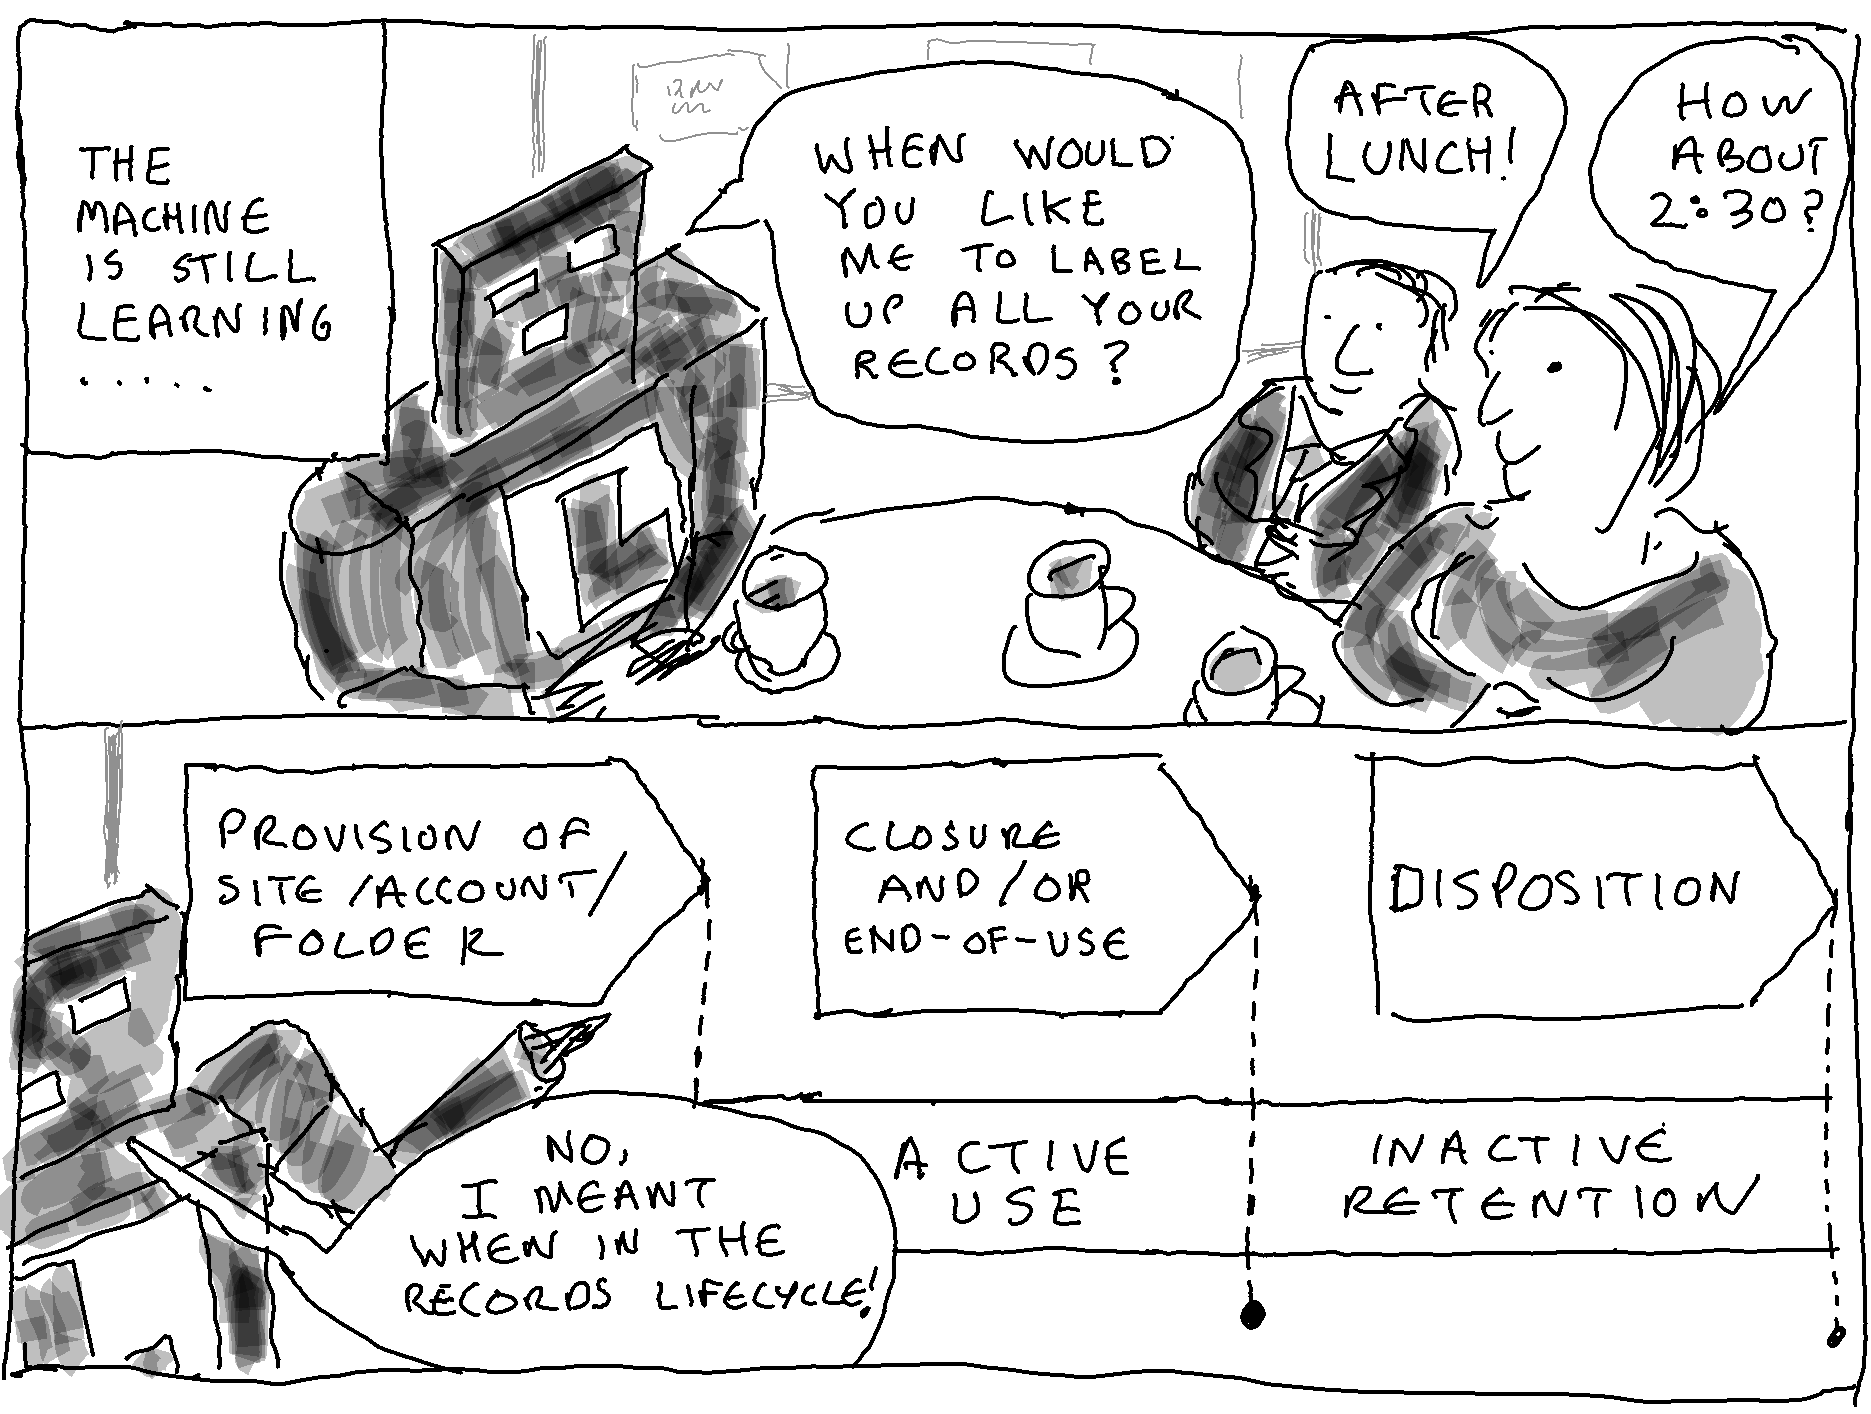
  • Records have a lifecycle – setting access permissions and retention rules at the point of creation helps ensure records can be managed predictably and efficiently through their life. 
  • Act at the highest practical level of content grouping – acting on content groupings rather than individual items helps ensure that you keep the context around key documents and messages. It is also the natural way that archival and records management thinking can be scaled up
  • The retention rule that should be applied to content depends upon the nature of the work from which that content arose – we value records according to the extent to which the work they arose from is important.  A hastily written message from a piece of work that is still having an impact on us now is likely to be more valuable than a beautifully written report from a piece of work of short lived impact
  • Preserve the context as well as the content – imagine you had the key documents from a piece of work (the strategy, design, policy, contract, final report etc,) but not the humdrum documents/messages through which the work to arrive at those outputs was conducted. You would have limited ability to understand, question, defend, debunk or assess those key documents
  • Respect the original order in which content was created – the structures of the systems that people use to conduct and record their work will influence that work. If you retrospectively change the order/structure of a set of records, then you risk giving a false impression of how that work was conducted. You also risk making it impossible to establish who knew what and when – questions that often lie at the heart of any form of research or investigation

These intuitions are generally applicable to records at any stage of human technological progress. They were arrived at in the paper age, but they are equally applicable to the parchment age before it (when clerks working in my country were creating records on sheep skins) or the digital age after it.

However, these general intuitions are only a starting point. We should build on them to arrive at a set of intuitions that are specific to our age, in order to better inform and frame data science interventions in our domain.

A significant proportion of the digital content that has been created in organisations in countries like the UK over the past twenty five years now exists as either:

  • legacy shared drive (fileshares) repositories
  • SharePoint repositories
  • email repositories

It would be beneficial to articulate intuitions about the structure and nature of content in these common types of repositories. In particular it would be beneficial to articulate intuitions for:

  • how the records lifecycle works in such a repository
  • what constitutes the original order/structure of content in the repository (and how we can best factor that order into the decisions we take when conducting reviews and appraisal exercises on records)
  • how content of ongoing value tends to be distributed across the repository
  • how content that has no value tends to be distributed across the repository

I will offer some of my intuitions on these questions in coming posts.

All comments are my own

Records management in a hyperscale digital world

Records management is a corporate function that takes place within the context of a wider digital economy, and is influenced by developments in that wider digital economy. The digital economy is three decades old but it is still moving, and still growing. 

One of the key trends in the digital economy has been the growth of what we might call ‘hyperscale’ services. These are services that can be scaled up to the level of the entire digital economy, for use by all, most or many actors across that economy.

We have seen the emergence of successive waves of hyperscale services:

  • in the 1990s – hyperscale search engines, consumer email services, and retail services
  • in the 2000s – hyperscale social media platforms 
  • in the 2010s – hyperscale cloud storage and compute services (like Amazon Web Services and Microsoft Azure) and hyperscale cloud productivity suites such as Office 365 (now Microsoft 365) and Google Apps (now Google Workspace)
  • in the 2020s – hyperscale AI services such as ChatGPT

The impact of hyperscale services on records management

Most organisations in our digital economy are now deploying a cloud productivity suite (Microsoft 365 or Google Workspace). These suites provide general purpose applications for messaging, collaboration and document management. They can be used by any and everybody in the organisation whilst working on any business activity. In the on-premise era these capabilities would have been provided by stand-alone applications (an email system, a document management system, and perhaps a collaboration system) that would have been separately deployed on a corporate on-premise network. 

The shift from on-premise systems to hyperscale cloud productivity suites is a change in the context in which records management takes place. It has: 

  • changed the architecture of the systems within which individuals communicate, collaborate and store documents– with a move to relatively simple architectures based on team or individual sites/accounts/drives
  • changed the nature of the relationship between document management systems and communication tools – search and AI tools within a cloud suite are able to use information in emails and chat messages as metadata about the documents held in the suite
  • speeded up the point at which organisational content is brought into contact with AI – Google and Microsoft have been big players in the emergence of hyperscale AI services –  Google researchers devised the transformer architecture on which all large language models (LLMs) are based, and have since developed the Gemini series of LLMs. Microsoft was the largest investor in OpenAI before and after the launch of its Chat GPT service, and they host OpenAI’s GPT models on their Azure cloud. Both Microsoft (using OpenAI’s GPT models) and Google (using their Gemini models) offer generative AI services within their cloud productivity suite.

The relationship between hyperscale cloud productivity suites and corporate records management

There is a demarcation line between hyperscale cloud productivity services and the corporate functions of records management and of information governance. Microsoft and Google respect the right of organisations to set their own access permissions and retention rules on content within M365 and Google Workspace. The AI tools that both Microsoft and Google have deployed within their suites (Microsoft 365 and Gemini for Google Workspace) are deployed to support individual productivity. They do not seek to change or override the access permissions and retention rules placed on content. Indeed these permissions and rules act as important guardrails on the operation of those services.

The architecture of the applications within cloud productivity suites

Organisations typically set access permissions and retention rules as defaults on aggregations/containers (folders, sites, accounts etc.). This is usually more efficient, more scaleable, safer, and easier to monitor, than applying such rules directly to individual items (though the ability to set exceptions from defaults is also important). From a records management perspective the key elements of any system’s architecture are the aggregations to which default access permissions and retention rules can be applied.

The way that a corporate collaboration/document management application is architected has a crucial impact on:

  • the speed at which the application can be deployed
  • the range of organisations capable of deploying the application 
  • the precision by which default access and retention rules can be set on content created or received within the application

There is a trade-off here. For any corporate wide document management/collaboration system:

  • an architecture that aggregates content into business activity specific aggregations (such as project, case or matter specific folders) will take a relatively long time to deploy, and a relatively high level of information management maturity to deploy, but will support a relatively high level of precision in the application of default access permissions and retention rules
  • an architecture that aggregates content into team or individual specific sites/drives/ accounts will take a relatively short time to deploy, and could be deployed by organisations whatever their level of information management maturity, but will allow for less precision in the application of default access permissions and retention rules 

Organisations tend to have a list of all their staff and all their organisational units. This makes rolling out a system that allocates sites, drives and accounts to individuals or organisational units a relatively straightforward process. Organisations do not tend to have a list of all the pieces of work being carried out across all areas of the business. Nor do they typically even have a list of all the types of work being carried out. This makes rolling out a corporate system based on function and activity a far from straightforward process because a central team would have to identify all these types of work (and specific instances of those types of work) as they go through the roll out. 

In the late 1990s and early 2000s various public institutions, in various jurisdictions, issued specifications for electronic records management systems. These specifications were all based on the assumption that once the digital world had settled down, organisations would want to use an architecture based on function and activity. 

The specifications created a market for a type of system that became known as electronic document and records management  (EDRM) systems. This was a niche market because only organisations with strong records and information management skill sets would find it feasible to deploy them. This is because their architecture required a corporate business classification, and such classifications are complex to construct, test and secure organisational agreement to.

The market for today’s hyperscale cloud productivity suites is fundamentally different to the on-premise market for document management and other corporate systems of the 2000s and early 2010s.  Cloud productivity suites are serving a hyperscale market which stretches to the entire digital economy, and which cannot support niche markets. These suites therefore have to be architected so that any organisation, large or small, can deploy them.  

A fundamental shift in the way records are aggregated

The move to cloud productivity suites has brought a shift:

  • towards team and individual based architectures – where sites are given to teams and accounts given to individuals). 
  • away from function and activity based architectures – where an organisation has some sort of hierarchical classification of its broad areas of work, and creates new aggregations (sites, libraries or folders) when new pieces of work start, which are assigned to the relevant place within the hierarchical structure

This shift is an inevitable consequence of the move to the hyperscale. 

Compared with equivalent applications from the on-premise age, the collaboration/document management applications within Microsoft 365 and Google Workspace have a simpler architecture, are less configurable, and, as a result, are quicker to deploy. Compare the typical time taken to roll out Microsoft Teams in circa 2020 (measured in weeks) with that of an on-premise SharePoint implementation in circa 2010, or an on-premise EDRM system in circa 2007 (measured in years).  

It is true that Microsoft and Google are able to offer premium service to segments of their market –  for example Microsoft can offer extra information management functionality for customers willing to buy E5 licenses rather than an E3 licences. But the premium information management features exist in separate administrative services (which in the case of M365 as branded as Microsoft Purview). The applications deployed to end-users (which, in the case of Microsoft 365 include Teams, Outlook/Exchange, and OneDrive) have a core architecture that is the same for all customers, large or small, regardless of their licence. 

Function and activity architectures have not disappeared. When an organisation deploys a line of business system for one area of work they invariably use an activity based architecture (think of case management systems, HR systems, student record systems etc.). However it would not be cost effective for an organisation to deploy specific systems for every separate line of business. It is only cost effective to pick out those line of business activities with the highest volume and/or value and develop specific systems for them. All other activities will tend to use all-purpose corporate systems, and that role is now generally provided by the hyperscale cloud productivity suites.

The intuition that we can apply access permissions and retention rules more precisely when we know the business activity from which content arose is still valid. This intuition can help to diagnose some of the challenges organisations will face in managing (and exploiting) content in team and individual based aggregations through time. It can also help generate options for using AI and data science techniques to improve the precision with which access permissions and retention rules are applied to content.

The fact that there has been a convergence across the digital economy on team and individual (rather than function and activity) based architectures in corporate all purpose systems is not a failure of records management or information governance. It is simply a change in the context in which they operate. The convergence has happened because corporate all purpose systems are now a hyperscale service.  Function and activity architectures would have acted as a bottleneck on corporate all-purpose systems becoming a hyper-scale service.

(Views in this post are my own)

An overview of Microsoft 365 Copilot

The use of unstructured data as an input to generative AI processes 

Microsoft 365 Copilot is an example of a ‘retrieval augmented generation’ (RAG) system. RAG systems are a way for organisations to use the generative AI capabilities of external large language models in conjunction with their own internal information. M365 Copilot enables an individual end-user (once they have a licence) to use the capabilities of one of OpenAI’s large language models in conjunction with the content they have access to within their M365 tenant.

The basic idea of a RAG system is that an end-user prompt is ‘augmented’ with relevant information from one or more sources (typically from a database or other information system within an organisation’s control). The augmented prompt is then sent to the large language model for an answer. A rigid separation is maintained between the large language model and the organisational information systems used to augment the prompt.

Retrieval augmented generation systems aim to harness the advantages of large language models (their creative power, ability to manipulate language and vast knowledge) whilst mitigating their main disadvantages (their tendency to hallucinate, their ignorance of their own sources, and the likelihood they have not been allowed to learn anything new since they finished their training).

Many RAG systems will use a structured database as their source for augmenting the large language model. Such a structured database will act as a ‘single source of truth’ within the organisation on the matters within its scope.

The interesting thing about M365 Copilot is that it is using the unstructured data in an organisation’s document management, collaboration, and email environments (SharePoint, Teams and Exchange) as the source of content to augment each end-user prompt.
These environments do not function as a single source of truth inside an organisation. They will contain information in some items (documents/messages etc.) that is contradicted or superceded by information in other items.

Using unstructured data as the source for a RAG system poses two key challenges for the system provider:

  • The system must respect the access permissions within those unstructured data repositories;
  • The system must be provided with a way to determine what content is most relevant (and what is less relevant, or irrelevant) to any particular prompt.

M365 Copilot is not seeking to change access permissions or retention rules. In fact those access permissions and retention rules can be seen as guardrails on the operation of M365 Copilot.

The component parts of Microsoft 365 Copilot

M365 Copilot itself has a relatively small footprint within an M365 tenancy. It adds just three types of thing to your M365 tenant – namely:

  • Some new elements to the user interface of the different workloads and applications (Teams, Outlook, PowerPoint, Word etc) to enable individuals to engage with M365 Copilot and enter prompts for Copilot to answer;
  • A set of semantic indexes that Copilot can search when an end-user enters a prompt. When an organisation starts using M365 Copilot a tenant level semantic index is built that indexes the content of all the SharePoint sites in the tenant. Every time they purchase a licence for a new individual user a new user level semantic index is built of all the content accessible to that user in their own individual accounts, together with any documents that have been specifically shared with the individual;
  • Tools (such as the Copilot dashboard and the Copilot Usage report) that enable administrators to monitor how Copilot is being used.

The reason that Microsoft have needed to add so little to the tenant is that M365 Copilot works with three pre-existing components, namely:

  • The Microsoft Graph, which is a pre-existing architectural feature of every Microsoft 365 tenant. In essence it a searchable index of all the content held within the tenant and all the interactions that have taken place within the tenant. Copilot’s new semantic indexes are built on top of the existing Microsoft Graph;
  • A group of large language models (of which the most important at the time of writing is GPT-4) that sits outside of any Microsoft 365 tenancy. They are owned and built by OpenAI, but they sit on the Microsoft Azure cloud platform.
  • An API layer to govern and facilitate the exchange of information between your tenancy and the external large large language model. Microsoft 365 Copilot uses Azure OpenAI Service to fulfill this role. The purpose of the Azure OpenAI Service component (and the contractual terms that underpin it) is to prevent the use of the information provided to the large language model being used by OpenAI to retrain the model or train new models. This is important in order to maintain the separation between the information in your tenant and the large language models that OpenAI and others make available to consumers and businesses.

This Azure OpenAI service is an outcome of the partnership between Microsoft and OpenAI.  OpenAI is a AI research lab that has developed the GPT series of large language models. They offer those models in consumer services (like Chat GPT) and to businesses.  Microsoft hosts the GPT models on its Azure cloud platform and is a major provider of funding to OpenAI.

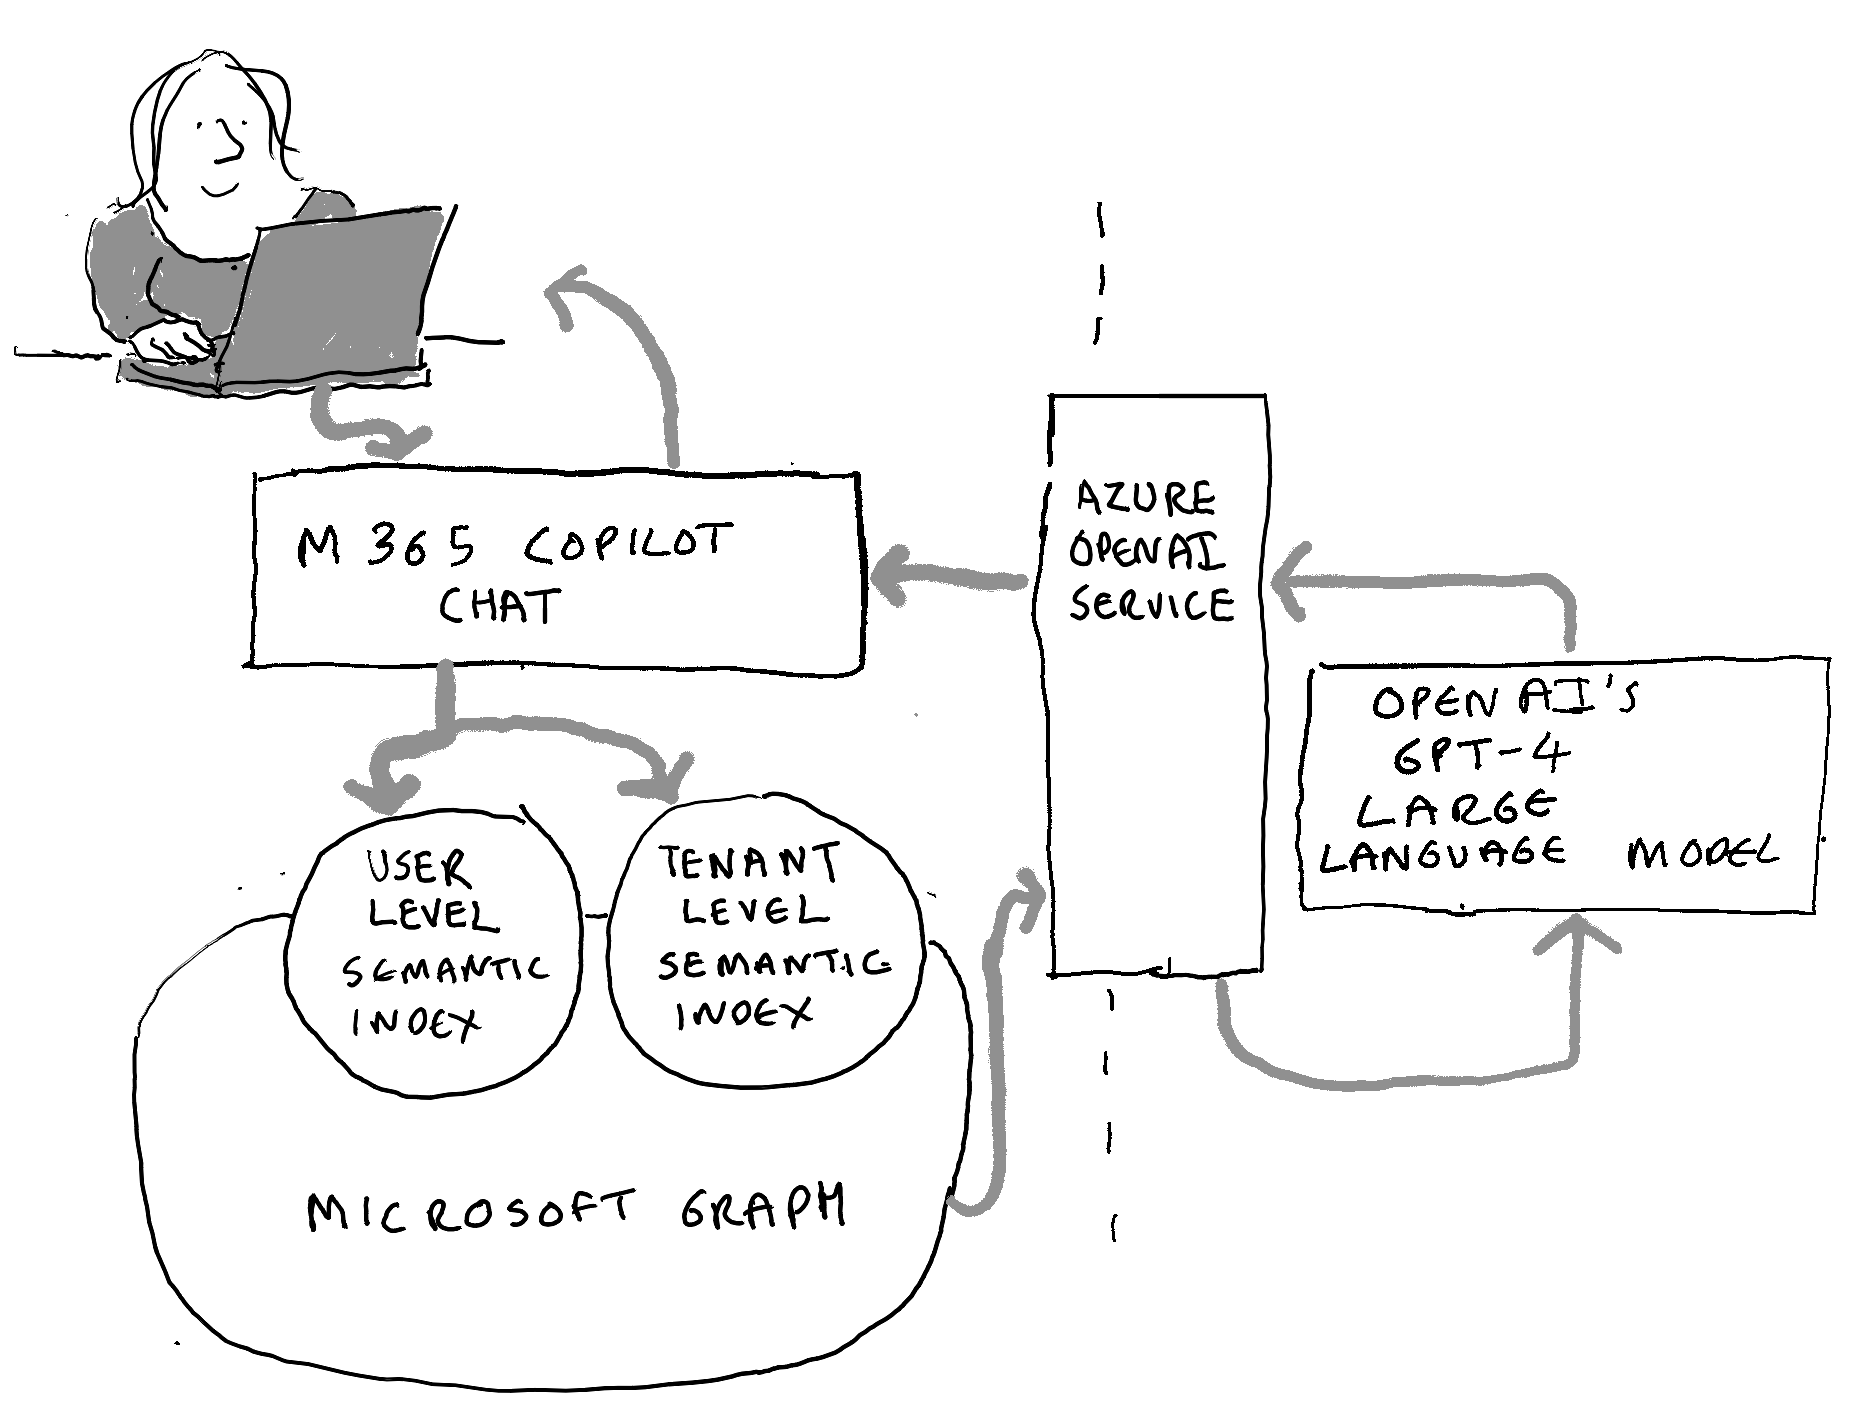
The illustration above shows what happens when an individual enters a prompt into Microsoft 365 Copilot Chat:

  • The prompt is sent to both the user level semantic index (of content specific to that individual) and the tenant wide semantic index (of all SharePoint content);
  • The semantic indexes develop a targeted search of Microsoft Graph to find information relevant to the individual’s prompt;
  • Copilot sends the prompt, enriched with the information found in Micorosft Graph, to Azure Open AI services;
  • Azure Open AI Services opens a session with one of OpenAIs large language models (typically GPT-4, which also serves as one of the models behind OpenAI’s consumer Chat GPT service);
  • GPT-4 provides a response;
  • Azure Open AI Services closes the session with GPT-4 without letting OpenAI keep the information that was exchanged during the session;
  • Azure Open AI Services provides a response back to M365 Copilot, which does some post-processing and provides it to the end user.

Using AI for records management purposes: seven key choices

If you were to tell me that you are going to apply artificial intelligence for records management purposes, then the first thing I would do is blink. Once I had finished blinking I would ask you some questions in order to locate your proposed intervention more precisely.  

There is a range of types of AI, that can be applied to take a range of different actions, on a range of different target types of content, at a range of different levels of aggregation, at a range of different stages of the records lifecycle, under a range of different types of human control, in pursuit of a range of different records management purposes. 

It is the choices that you make on each of these seven aspects that define your AI intervention.

1 Choice of AI/data science technique

There are a great variety of different types of artificial intelligence (and data science techniques more generally)  that could be applied. You might want to:

  • write your own rule set; OR
  • train a supervised machine learning model using pre-labelled data; OR
  • run an unsupervised machine learning model directly on your target content (and then start supervising and iterating it because the model won’t get it right first time!); OR
  • prompt, fine tune or augment a large language model (LLM).

Alternatively (or additionally) you might want to run analytics tools to gain statistical insights on your target content.

It is best to think of them as a tool set. You may need to apply them in combination. You may start within one type of intervention and have to switch to another if results are not as planned or if costs are too high.

2 Choice of relationship between AI and human control

The AI/data science technique might be:

  • giving decision support – by providing a records management team with summaries of content, suggested taxonomy categories, indications of the locations of sensitivities etc.;
  • directly acting on content – by assigning it to a taxonomy category, assigning it to a retention category, applying protective markings etc. In such cases the human control takes the form of both the testing of the AI model prior to deployment, and the continued monitoring of the model after deployment.

3 Choice of purpose 

There are various purposes for which a records management team might wish to deploy the help of AI (and data science techniques more generally). These include:

  • taxonomy application –  the use of AI to assign content to taxonomy categories. This could involve the use of supervised learning to apply an existing taxonomy. Alternatively it could involve the use of unsupervised learning to generate a taxonomy from the target content itself, and to apply it to that target content.  For the taxonomy to be useful for records management purposes it must be linked (or linkable) to retention rules;
  • disposition review – the use of AI to identify material that has no ongoing value to the organisation or its stakeholders;
  • appraisal and selection – the use of AI (usually by a public authority, after a period defined by statute) to identify material that has historical value for society and hence is worthy of transfer to a historical archive;
  • sensitivity identification – the use of AI to identify sensitivities in material that warrants the placing of access restrictions and/or other protections.

4 Choice of AI action

In order to support these purposes there are a variety of actions that AI might be deployed to take.  These actions include:

  • labelling – applying a taxonomy category (or directly applying a retention category) to an item or an aggregation;
  • summarising – summarising an item, aggregation or a set of aggregations. A summary might enable a records management team to quickly check assumptions about the content of that aggregation/set of aggregations. A summary might also enable a records management team to support and defend decisions made on that aggregation/set of aggregations; 
  • sensitivity protection –  actions to restrict access to aggregations, items, or parts of items that contain information that is identified as being sensitive;
  • negative appraisal – identifying personal, social, unsolicited (messages), uncommunicated (documents), and/or trivial items that are not needed within a particular aggregation or set of aggregations;
  • clustering – linking together similar items, aggregations or sets of items, for the purposes of taxonomy generation, taxonomy application, or to enable similar items/aggregations to be reviewed and processed together.

5 Choice of level of aggregation at which to act

Records consist of items (documents, messages, data entries, images, videos, etc). Items exist within aggregations (shared drives/folders, SharePoint sites/libraries, email accounts, datasets etc.).

A key decision for any AI intervention for records management purposes is the decision on what level of aggregation to make the decision/take the action on.  

If you are applying AI to apply a taxonomy, you could:

  • apply the taxonomy to individual items – each document, message, etc. is assigned to a taxonomy category; OR
  • apply the taxonomy to aggregations – each SharePoint site/ each email account/ each shared drive (or each high level folder or each folder) is assigned to a taxonomy category.

If you are taking destruction actions after disposition reviews you could:

  • dispose of entire aggregations – deleting the entirety of a SharePoint site/ the entirety of an email account/ the entirety of a shared drive/ the entirety of content below a high level folder/ the entirety of a folder; OR
  • dispose of individual items – deleting individual documents, messages etc. (without this deletion affecting the rest of the content in the aggregation of which they are part).

If you are taking selection actions after appraisal exercises you could:

  • select entire aggregations for permanent preservation- selection of entire SharePoint sites, entire email accounts (minus non-business content), entire Shared drives/the entirety of content below a high level folder/ entire folders; OR
  • select individual items for permanent preservation – selection of certain individual documents, messages etc. without this selection affecting the rest of the content in the aggregations of which they formed part.

6 Choice of stage of the records lifecycle

Another key choice is whether you plan to apply AI to:

  • active content on live systems (for example content in live MS Teams/SharePoint sites, live email accounts, etc.); OR 
  • inactive content on live systems (for example closed/moribund Teams/SharePoint sites, email accounts of leavers etc.); OR
  • inactive content on legacy systems (for example content created in legacy systems and not migrated to live systems, including legacy shared drives, legacy on-premise SharePoint implementations, legacy electronic document and records management systems, legacy email systems).

Applying AI to active content on live systems offers very different challenges than applying AI to legacy systems.

If you apply AI to active content in live systems you have the advantage that the AI model’s judgements could be made visible to the end-users who have created or received the content.  These end-users could be offered the opportunity to challenge or confirm the model’s judgement. 

However, most live environments are cloud based and are ‘evergreen’ – with frequent and rapid updates pushed through by the provider. For a tenant organisation to deploy an AI tool in a cloud suite such as Microsoft 365 and make its judgements visible in the end-user interface, would require some form of integration with the suite. Such an integration would run the risk of conflcting with future developments in the suite. This integration challenge would not arise if you use the AI capabilities provided within the suite itself, but you are then limited to the AI capabilities made available by that provider in that suite/product.

When dealing with content on legacy systems there are no end-users around to confirm or correct the judgement of the AI model. However a compensating  advantage of acting on legacy systems is that there is scope to move or copy target content into an environment of your choice, and to apply AI tools and data science techniques of your choice.

7 Choice of target content

In general, most organisations will have accumulated most of their unstructured content in generic communications and document storage tools. The market for such tools over the past twenty years has been dominated by Microsoft. 

In the on-premise era the Microsoft Windows environment dominated. The most widespread document storage area was network shared drives (file shares).  SharePoint sites offered an alternative to network shared drives in the latter years of the on-premise era.  The most common message storage medium in the on-premise era was Microsoft Exchange email accounts. 

Microsoft have retained their domination of generic business document management, collaboration and communication tools in the cloud era. The Microsoft 365 cloud suite is built around the online versions of SharePoint and Exchange. The first big cloud native application that emerged in the Microsoft 365 cloud suite was MS Teams, but Teams does not have a repository of its own – it uses SharePoint and Exchange as its repositories:  

  • MS Teams uses SharePoint and OneDrive sites to store any documents posted or uploaded into it or sent through it (OneDrive sites use the SharePoint repository);
  • MS Teams uses Exchange email accounts to store any messages or channel posts made through it. 

This relative homogeneity of supplier and environment means that most of the content that most organisations are likely to need to take action on comes in the form of either:

  • network shared drives (fileshares) – they may be an unglamorous left-over from the on-premise era, but they still have to be dealt with;
  • SharePoint sites -including sites from on-premise SharePoint implementations, sites in Microsoft 365 SharePoint implementations, sites set up to accompany MS Teams, and OneDrive sites.  Furthermore many organisations have decanted/migrated the content of some or all of their legacy on-premise era document management systems, including electronic records management systems, into SharePoint sites;
  • email accounts – including any on-premise email accounts, and email accounts in cloud suites. Email accounts in Microsoft Exchange in Microsoft 365 also include, as a substrate invisible to the end-user, the Teams chat messages exchanged by that user.

If approaches can be found for applying data science techniques for the management over time of content in network shared drives, SharePoint sites and email accounts, then huge swathes of most organisations’ digital heaps become manageable.

Typology of AI interventions for records management purposes

The most striking thing about these choices is that for each of them there is no right or wrong answer. These choices exist because there is no perfect form of AI, no perfect way of applying AI, and because perfection in records management is not obtainable (even with AI). There are trade-offs to be managed and different choices have different advantages and disadvantages.  

Setting out these choices provides a way of placing any existing or proposed AI intervention that you come across (or think of) against the whole constellation of choices open to a records management team.

Nature of the choiceOptions
1 AI/data science technique(s)– analytics tools
– rule set
– supervised machine learning 
– unsupervised machine learning 
– large language model
2 Relationship between AI and human control– AI directly acting on content
– AI providing decision support
3 Purpose– taxonomy application
– disposition review
– appraisal and selection 
– sensitivity identification
4 AI action– assigning a category or label
– summarising
– sensitivity protection
– negative appraisal
– clustering
5 Level of aggregation at which to act– item level
– aggregation level
6 Stage of the records lifecycle – active content on live systems
– inactive content on live systems
– inactive content on legacy systems 
7 Target content– content in SharePoint sites
– content in email accounts
– content in network shared drives
– other

PhD thesis: The science of recordkeeping systems

My PhD thesis was published yesterday. You can view it/download it from the Loughborough University digital repository here.

The thesis provides a reassessment of records management theory. It evaluates rival records management approaches to email, sets out a new model of how organisational record systems work, and makes predictions on the likely impact of AI on records management practice.

My thanks for their excellent support and advice go to my supervisory team: Prof Tom Jackson, Prof Graham Matthews and Dr Clare Ravenwood (all Loughborough University) and Michael Appleby (The UK National Archives).

My thanks also go to The UK National Archives for funding and co-supervising the research.

Here is an overview of the contents of the thesis:

Chapter 1 introduces the study, and sets out its aim, which is to arrive at a model of how an organisational recordkeeping system works that:

  • is compatible with Frank Upward’s records continuum model of how recordkeeping processes work across a society;
  • reflects a realist understanding of how systems (social programmes) work in the social world;
  • takes account of learnings from the experience with email systems, and with corporate multi-purpose systems more generally, over the quarter century prior to the time of the study;
  • is equally applicable for analysing organisational recordkeeping before and after the digital revolution, and before and after a potential AI revolution.

Chapter 2 seeks to explain the distinctive features of the realist perspective on reality, on knowledge, and on scientific progress. It describes how Ray Pawson and others developed a realist perspective on how social programmes work, and developed realist methodologies for investigating social programmes. It explains the implications of taking a realist perspective when looking at how recordkeeping systems work and describes how realism informed the logic of inquiry of this study.

Chapter 3 introduces Frank Upward’s records continuum model, perhaps the most flexible and widely accepted current model of how recordkeeping processes work across a society. It describes the roots of the model in Minkowski’s geometry of Einstein’s spacetime. The chapter draws on both Upward’s model and Minkowski’s spacetime geometry to produce an initial eight step model of the implementation chain of an organisation’s record system. This initial model is used through the study as a means of comparing different theoretical and practical approaches to recordkeeping.

Chapter 4 uses the Einstein-Minkowski light cone view of spacetime as a lens to look at both

  • natural world record systems; and
  • pre-industrial social world record systems (using the Medieval English royal administration as an example).

The chapter seeks to establish:

  • the essential features of recordkeeping systems;
  • the features of our universe that makes it hospitable to recordkeeping systems;
  • the ways in which social world record systems are similar to, and differ from, natural world record systems.

Chapter 5 explores the features of recordkeeping systems in the large scale bureaucracies of twentieth century industrial and post-industrial (but pre-digital) administrations. It seeks to identify how such administrations went about balancing the new imperatives of efficiency and precision in their recordkeeping systems whilst endeavouring to preserve the reliability and predictability that had been key features of natural world record systems and of pre- industrial record systems. It looks at how the tensions between these imperatives play out in theoretical differences between:

  • Jenkinson’s view (expressed in the 1920s) that the original order of records should be respected;
  • Schellenberg’s view (expressed in the 1950s) that records should be organised by business function;
  • Scott’s view (expressed in the 1960s) that there is scope for records to be organised in a variety of different ways so long as the context of a set of records is captured and preserved.

The chapter offers an explanation of why it was that, despite these divergent theories, the period between the end of the second world war and the coming of email was a relatively stable period in recordkeeping practice within the administrations of large democracies. characterised more by consensus than contention.

Chapter 6 explores the impact on recordkeeping of the widespread adoption of email as a general digital communications tool at the end of the twentieth century. It sets out the key features of email systems as both communications tools and recordkeeping systems, and how those features exposed fault lines in recordkeeping theory and practice.

Chapter 7 seeks to identify the key points of contention that arose in records management theory and practice in the 1990s.

It does so through an examination of:

  • a major legal dispute over the management of US presidential and federal government email;
  • theoretical disputes over what constitutes a record system, and when an item becomes a record.

Chapter 8 seeks to identify the key points of contention that arose in recordkeeping theory and practice in the 2000s and 2010s. It does so through an examination of:

  • market competition between electronic document and records management (EDRM) systems designed expressly for recordkeeping, and other types of collaboration system, up to and including the move of corporate multi-purpose applications to the cloud;
  • the policy differences between two rival approaches towards the management of the email of public authorities: namely the approach of moving important emails out of email accounts; and the (Capstone) approach of assigning email accounts to short, medium or long term retention bands depending on the relative importance of the role occupied by the email account holder.

The chapter identifies seven key points of contention in the underpinning beliefs between the two main policy approaches to email. These seven points of contention are analysed in the three following chapters.

Chapter 9 seeks to adjudicate on those points of contention between rival policy approaches towards email that relate to theoretical questions, namely:

  • the question of when an email becomes a record;
  • the question of whether an email system is likely to function as a record system;
  • the question of whether or not the aggregation of records by business activity constitutes the optimum order for records.

It also adjudicates on the question of whether or not a significant portion of the correspondence within an individual’s email account is likely to be needed as a record.

Chapter 10 seeks to adjudicate on the points of contention that relate to the question of whether or not it is possible for an originating organisation to persuade end-users to move business email out of their email accounts.

Chapter 11 seeks to adjudicate on the point of contention that relates to the question of whether or not email accounts are manageable through time as record aggregations.

Chapter 12 seeks to adjudicate on the point of contention that relates to the question of whether or not it could be compatible with European data protection principles for an originating organisation to select some individual email accounts for permanent preservation.

Chapter 13 develops and sets out a model of the trade-offs involved in the design of a record system. The purpose of the model is to help a policy maker, practitioner or regulator to make an informed choice as to which of two imperfect approaches to records management is preferable in any given set of circumstances for any given set of stakeholders.

Chapter 14 uses both the record system trade-offs model presented in chapter 13, and the adjudications on points of contention presented in chapters 9 to 12, to arrive at an evaluation of the rival policy approaches to email. The chapter also:

  • proposes a formulation of the circumstances in which it is possible to design a record system that works for all stakeholders; and the circumstances in which it is not possible to design a record system that will meet the needs of all stakeholders;
  • makes an assessment of the implications of the record system trade off model developed in this study, and the evaluation of the policy approaches towards email carried out in this study, for three key records management principles: namely those of respect for the original order of records; the superior efficiency of aggregation by business activity; and the separation of the organisation of records from the context of records.

Chapter 15 describes how this study went about ‘zooming in’ Upward’s record continuum model of how recordkeeping processes work across an entire society to produce a new model of how recordkeeping processes work within a single organisation. It shows how the new model (the ‘record system matrix’) was created by combining the core ideas of Upward’s diagram with the ideas of Pawson on how social programmes work, and of Bearman on how recordkeeping transactions work. The model itself is presented in Chapter 16.

Chapter 16 presents the record system matrix that was developed in the course of this study. The matrix consists of a sixteen-step implementation chain of how a record system works within an organisation embedded in a recordkeeping society. The sixteen steps are presented in a four by four matrix that shows how four elements of a record system (the need to provide an interface to the system, the need to protect records, the need to organise records and the need to apply rules to records) manifest themselves across four phases of a record system (the policy and frameworks phase, the configuration phase, the recordkeeping transaction phase and the management of records phase).

Chapter 17 uses email as a testing ground to explore the practical implications for recordkeeping of the development of ever more powerful forms of artificial intelligence (AI). It makes predictions as to whether AI models for recordkeeping purposes are more likely to be developed by originating organisations themselves, or by the cloud suite providers that provide most organisations in the English speaking world with email systems at the time of this study. It looks at the implications of the relationship between tenant organisations and cloud suite providers for:

  • the explainability of any changes to retention rules to email correspondence made on the basis of the judgement of algorithmic models;
  • end-user consent to any changes to access permissions on email made on the basis of the judgement of algorithmic models.

Chapter 18 investigates the theoretical and policy implications of the development of ever more powerful forms of artificial intelligence and of their application for recordkeeping purposes to email. It sets out two thought experiments and uses them as a basis to:

  • make predictions as which of the main policy approaches towards email is likely to make a safer and better starting point for the application of artificial intelligence models for recordkeeping purposes;
  • assess whether or not the original aggregation of email correspondence into email accounts (and by extension the principle of respect for the original order of records) will continue to be important once organisations acquire the ability to re-aggregate records at any point in their lifecycle.

Chapter 19 sets out the conclusions of this study with regard to its three objectives, which were to:

  • clarify, reframe and resolve key tensions in recordkeeping theory;
  • evaluate rival recordkeeping approaches towards email;
  • construct a model of how an organisational recordkeeping system works against which any viable approach to recordkeeping could be mapped.

It provides some reflections on the novelty of this study, and some methodological reflections on the use of thought experiments. It also explores a key opportunity for further research arising from this study, namely the opportunity to develop a science of record systems that covers both social world and natural world record systems.