Role-based retention in Microsoft 365: Requirements for features and AI models

The Information and Records Management Society’s Microsoft 365 Customer Advisory Board Working Group provides a channel through which the records management community can work up feature requests to pass to Microsoft in an effort to influence and inform the company’s future roadmap for the product. 

In 2023 the Working Group passed two sets of feature requests to Microsoft, and I reproduce one of them in this post. It is a set of feature requests that aims to make it easier for an organisation to apply a role-based approach to records retention within Microsoft 365.

About role-based retention

Role-based retention has emerged from the Capstone approach to email, developed by the US National Archives and Records Administration (NARA) in 2013. 

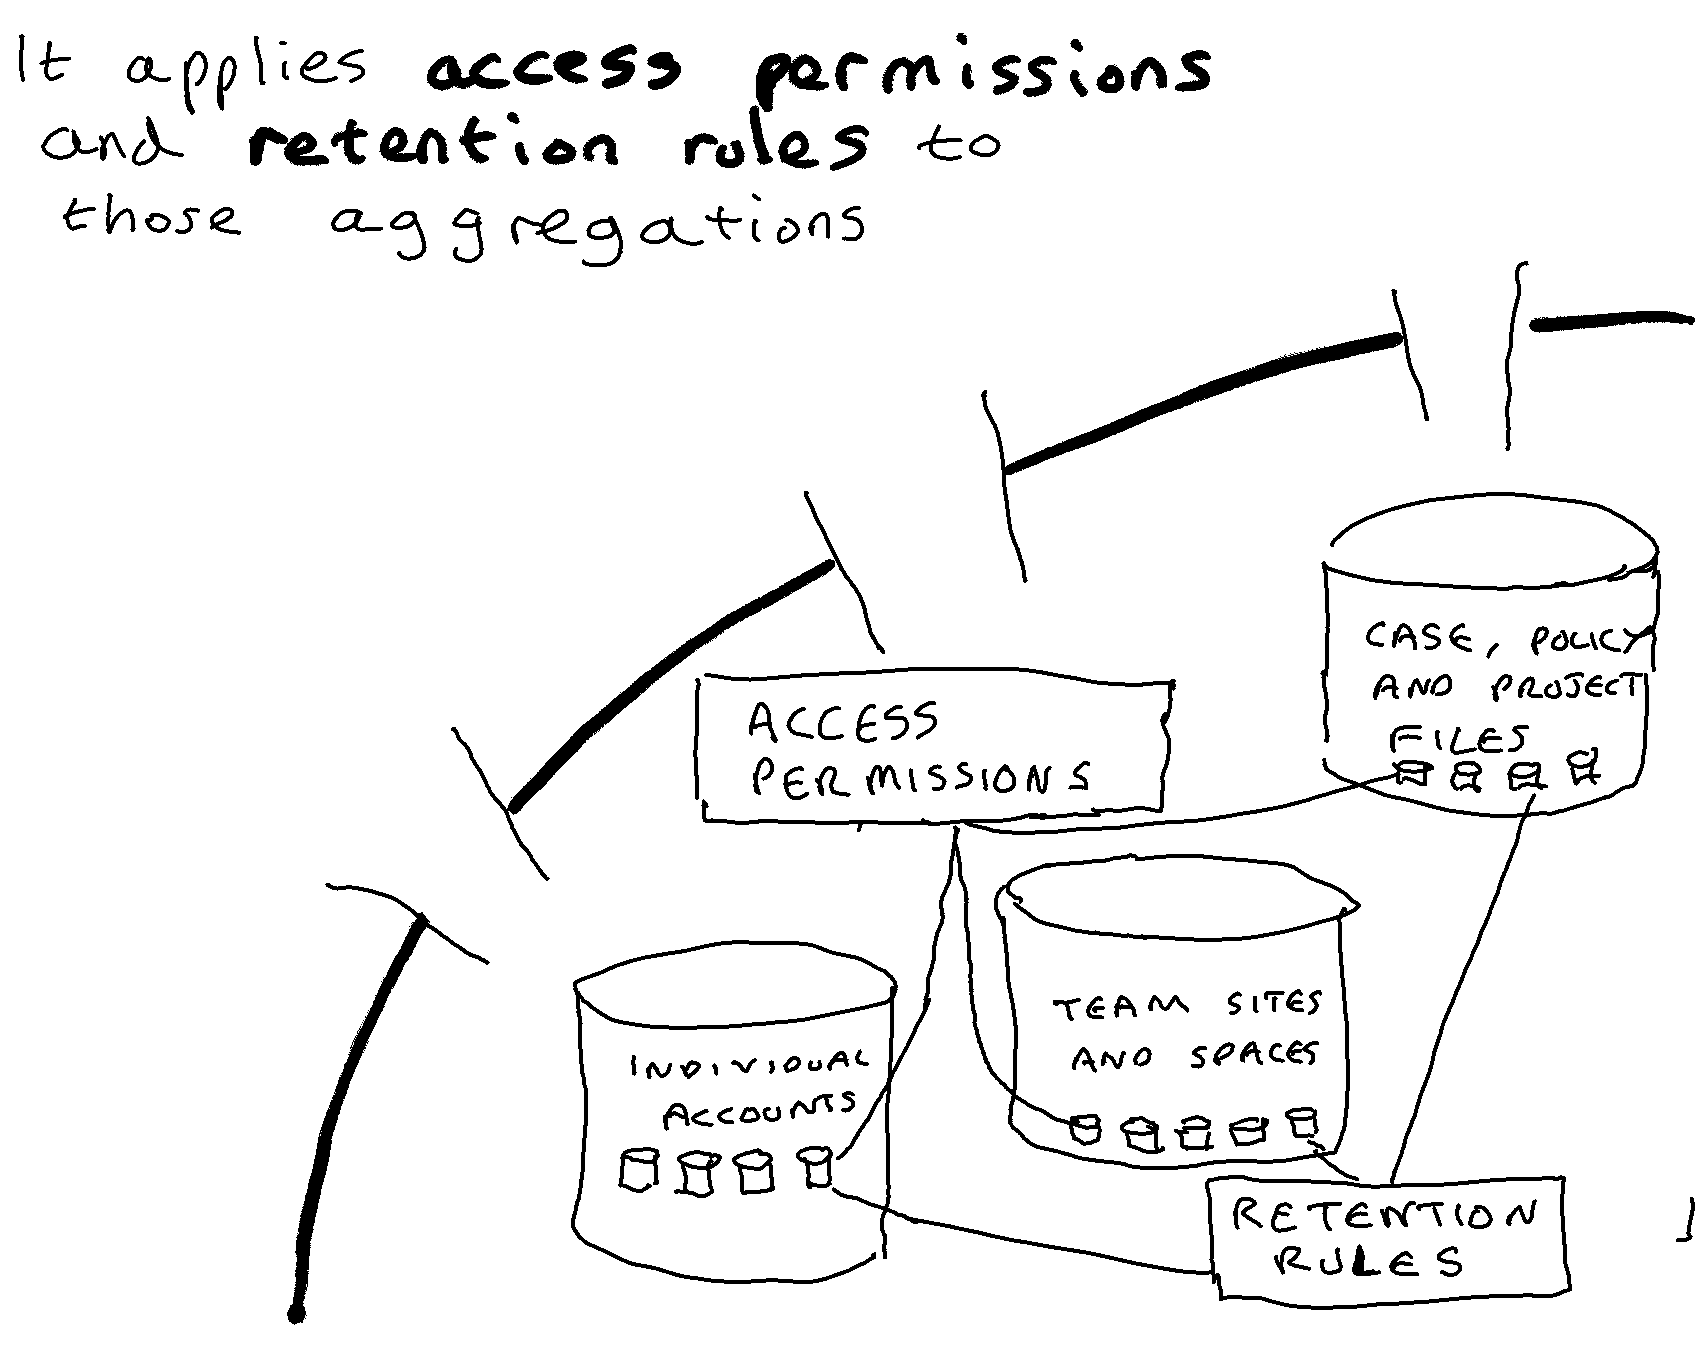
The working definition of role-based retention used in this set of requirements is that it is an approach to applying retention rules in which:

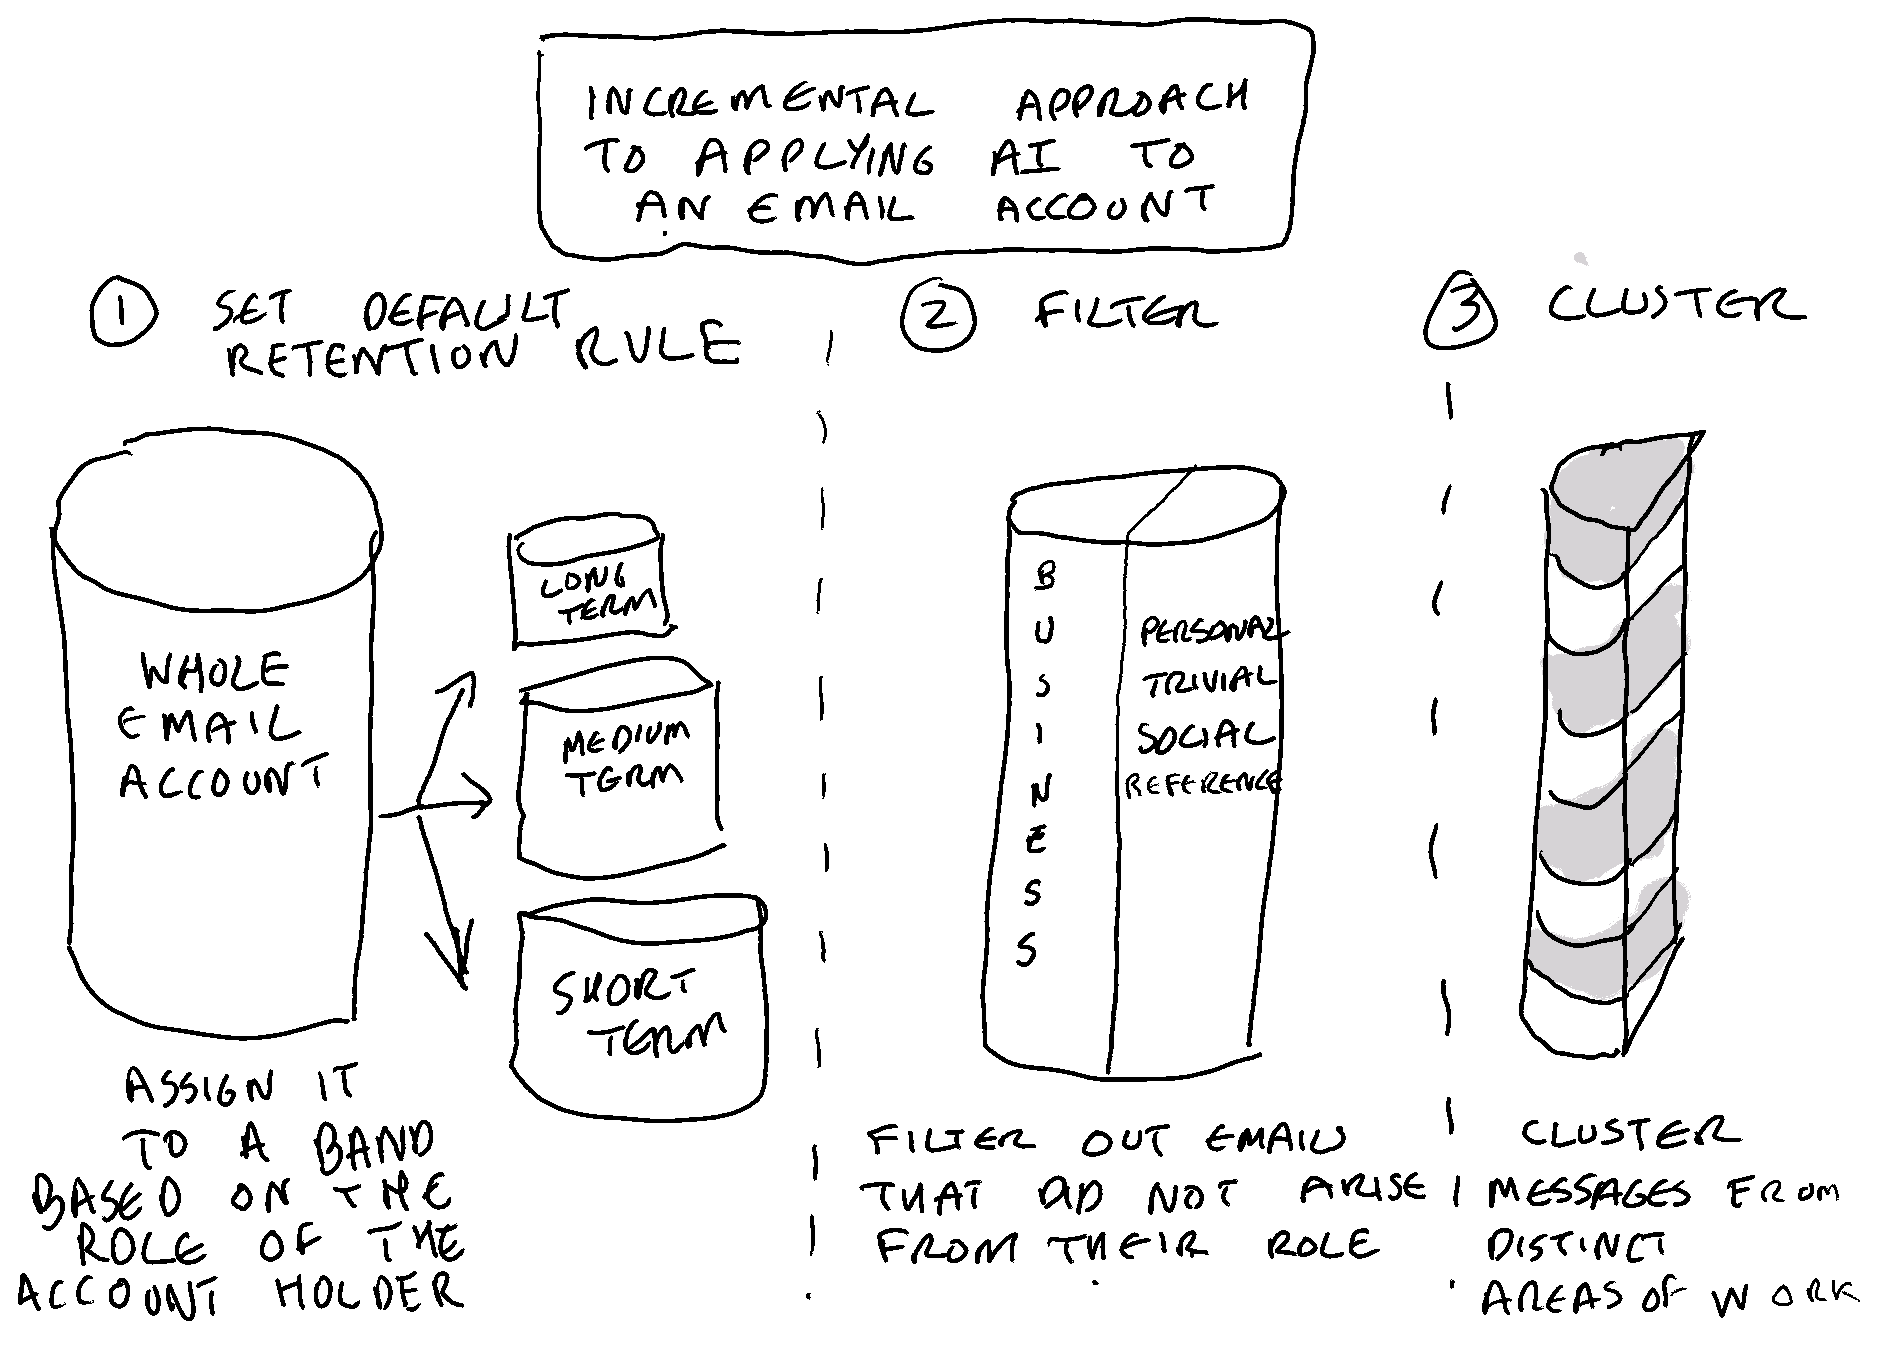
  • Individual accounts are assigned to a short, medium or long term retention rule depending upon the relative importance of the role of the individual to whom they belong;
  • Team sites and spaces are assigned to a short, medium or long term retention rule depending on the relative importance of the role of the team to whom they belong.

Like any approach to retention, role-based retention has strengths and weaknesses.

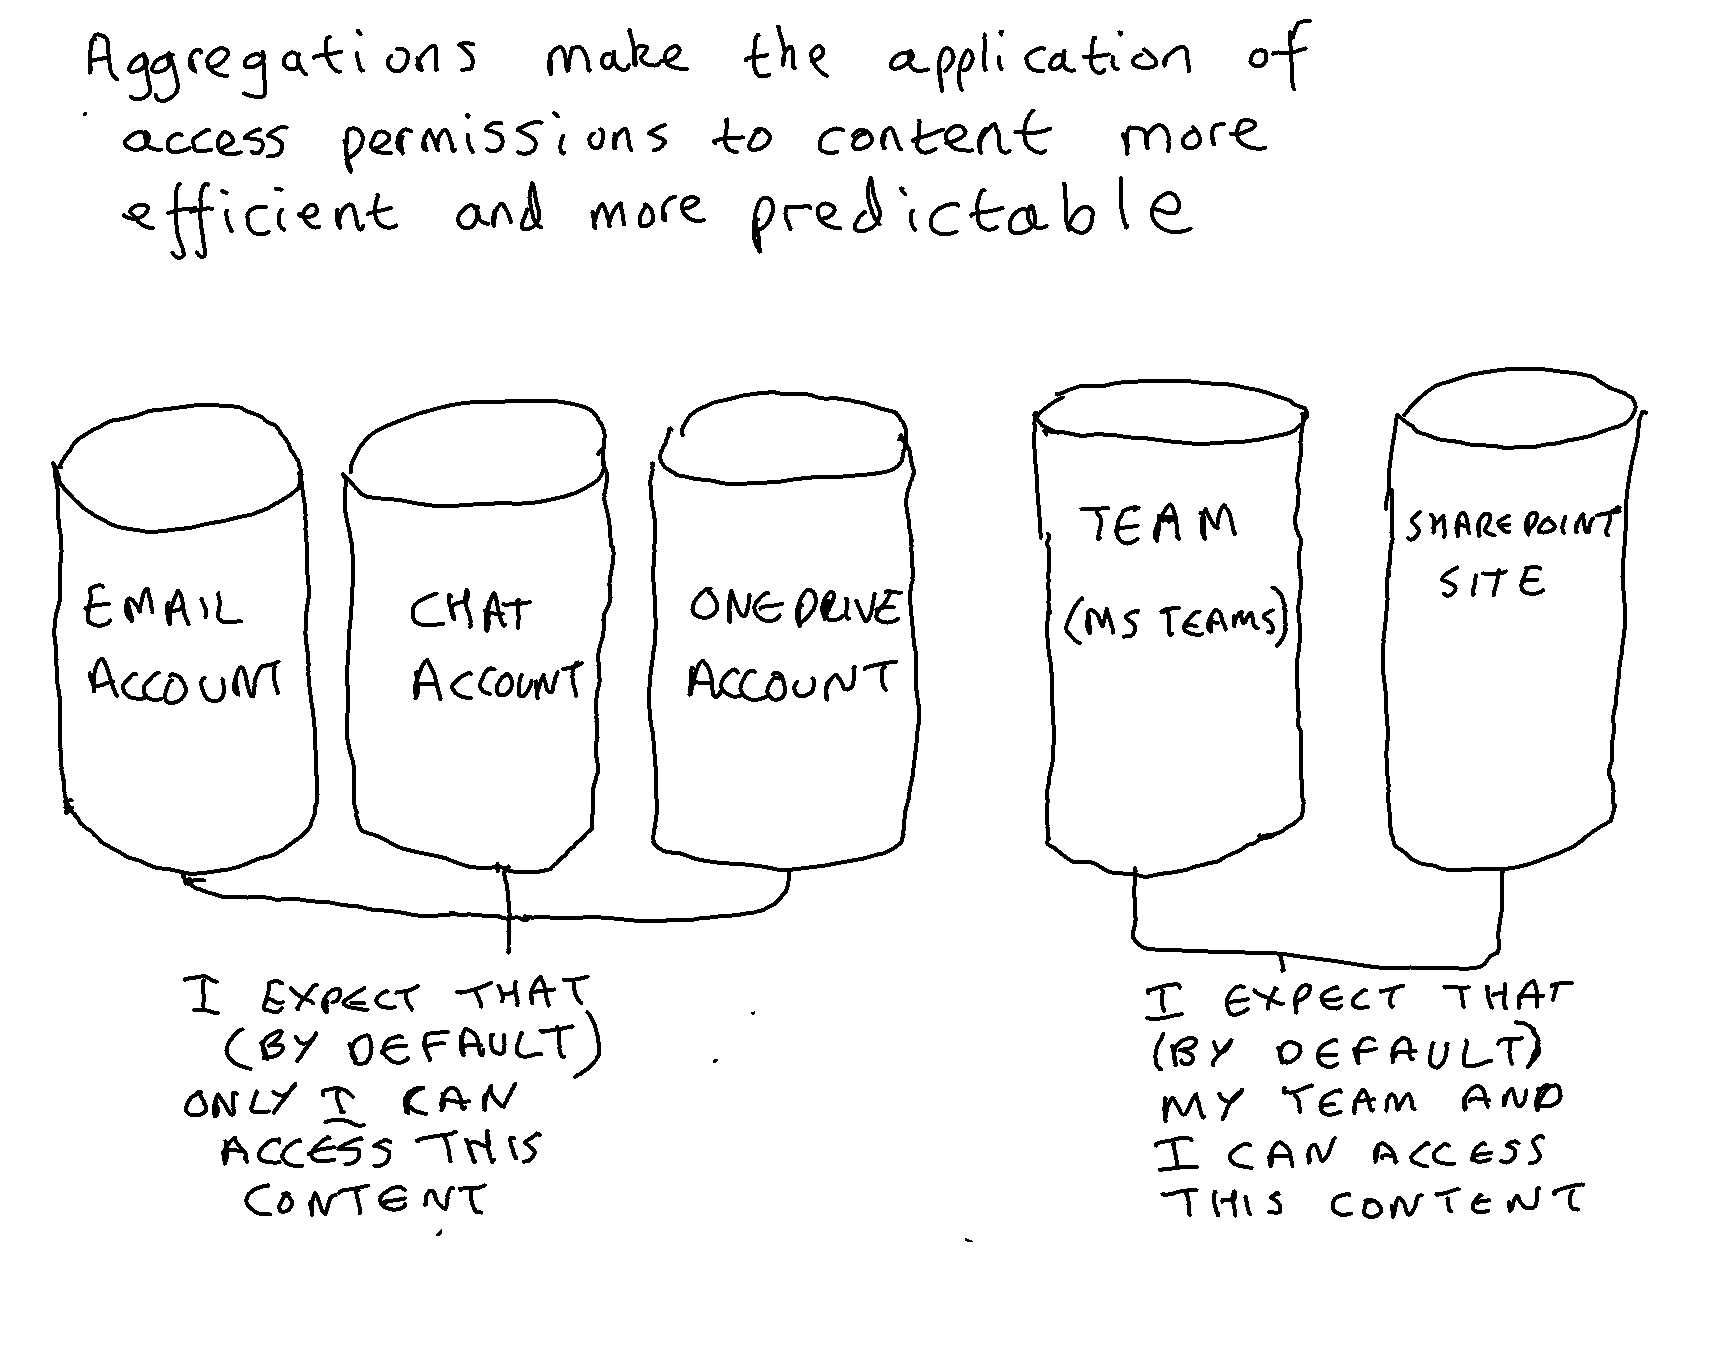
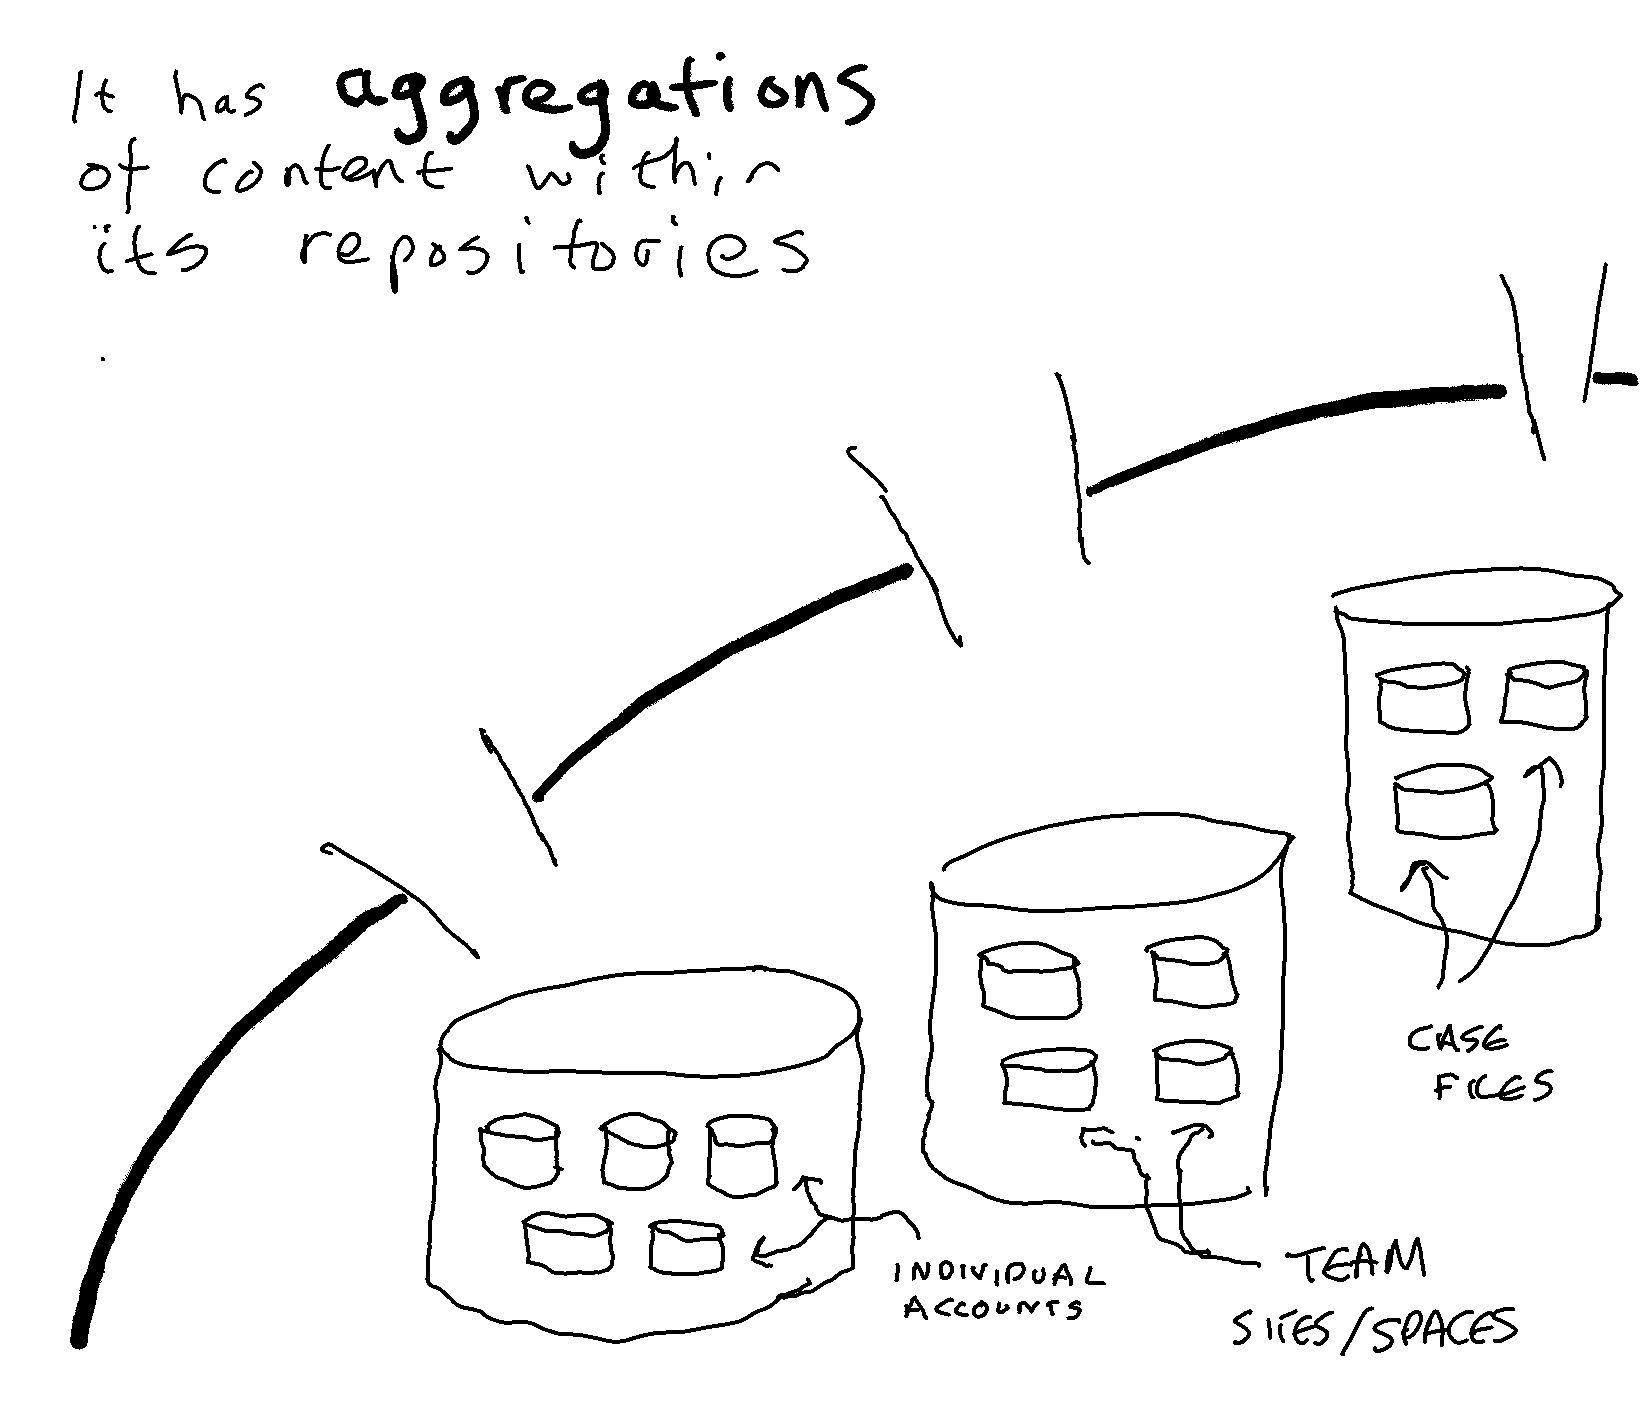
  • Its main strength is that it uses the existing way that content is aggregated within the communication and collaboration applications of a cloud suite such as Microsoft 365;
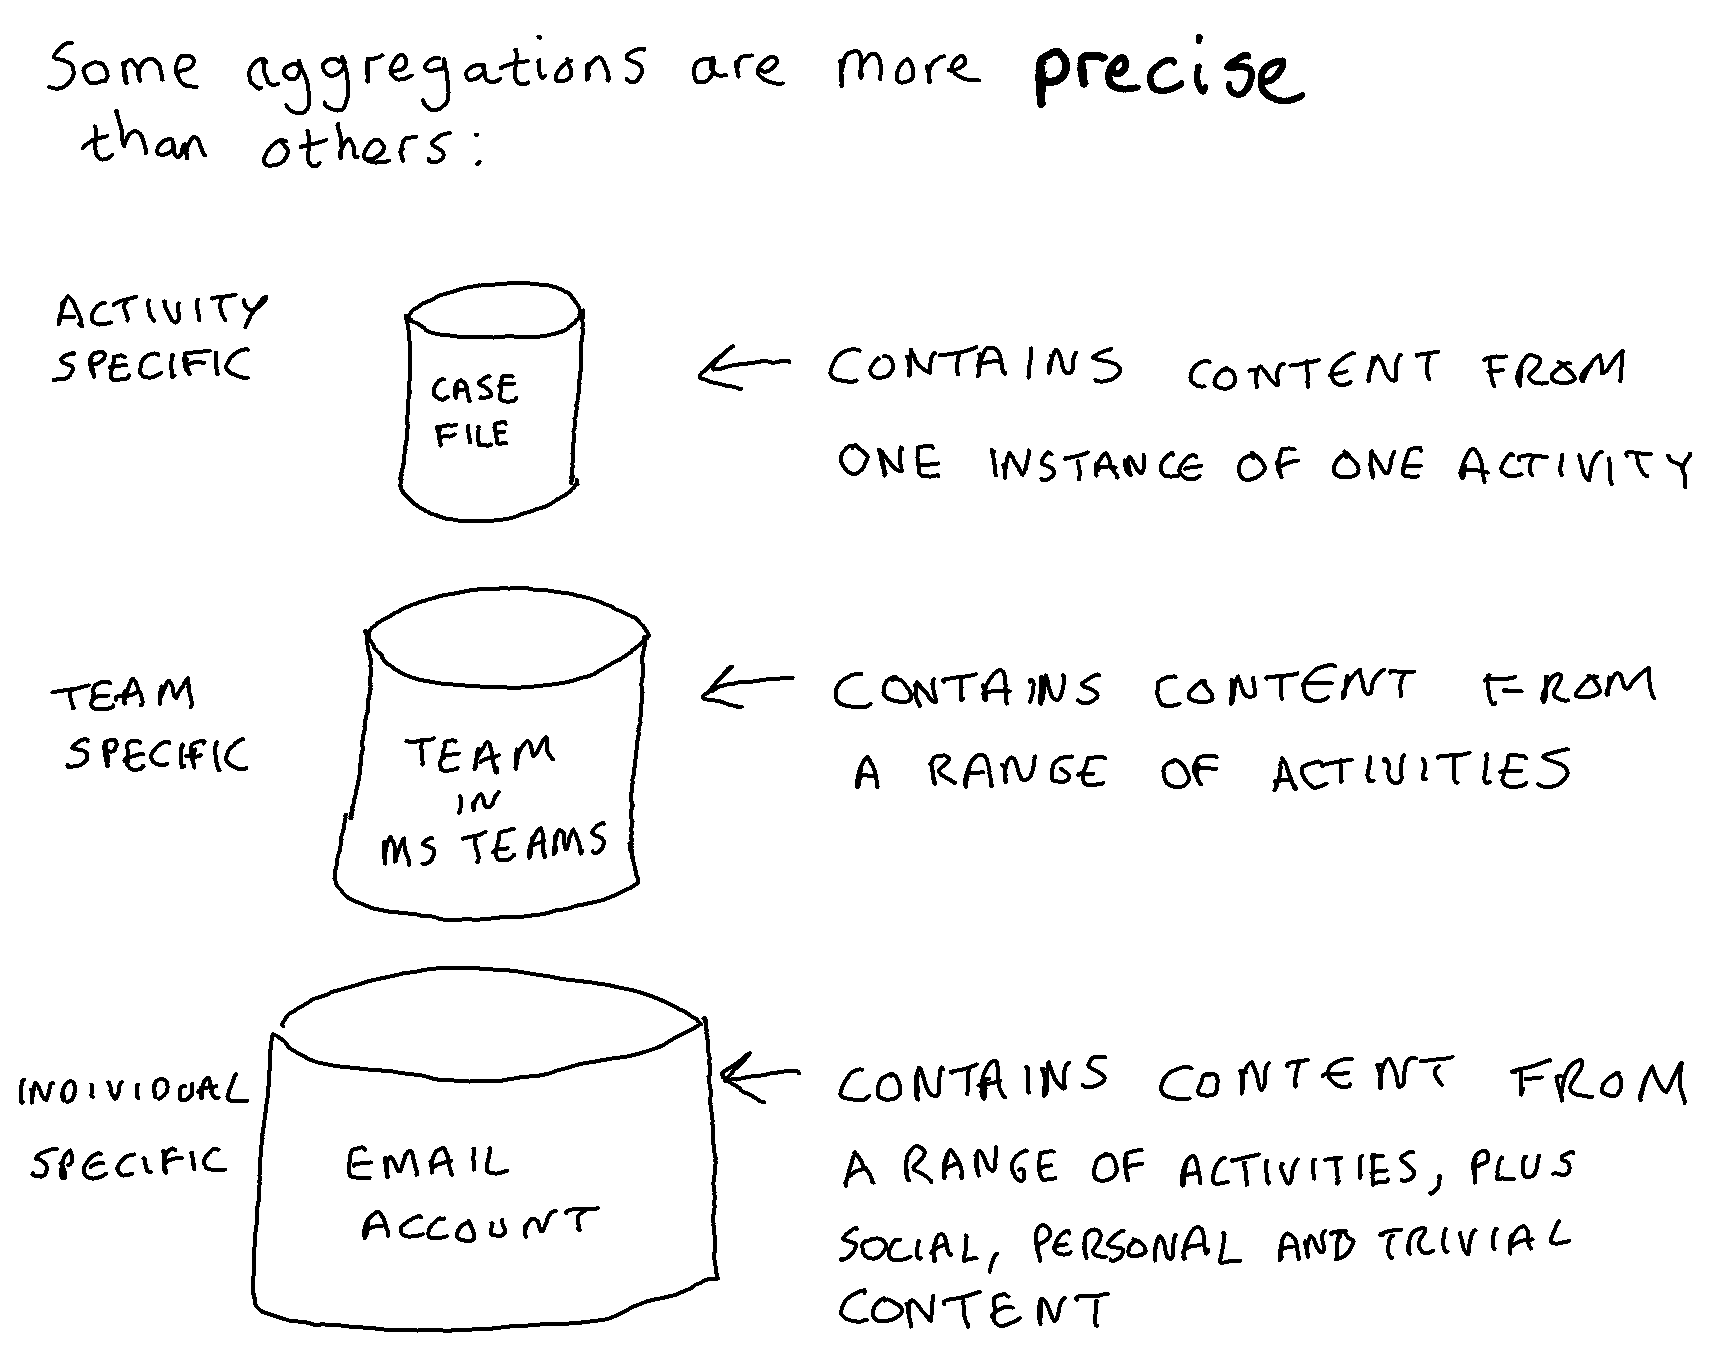
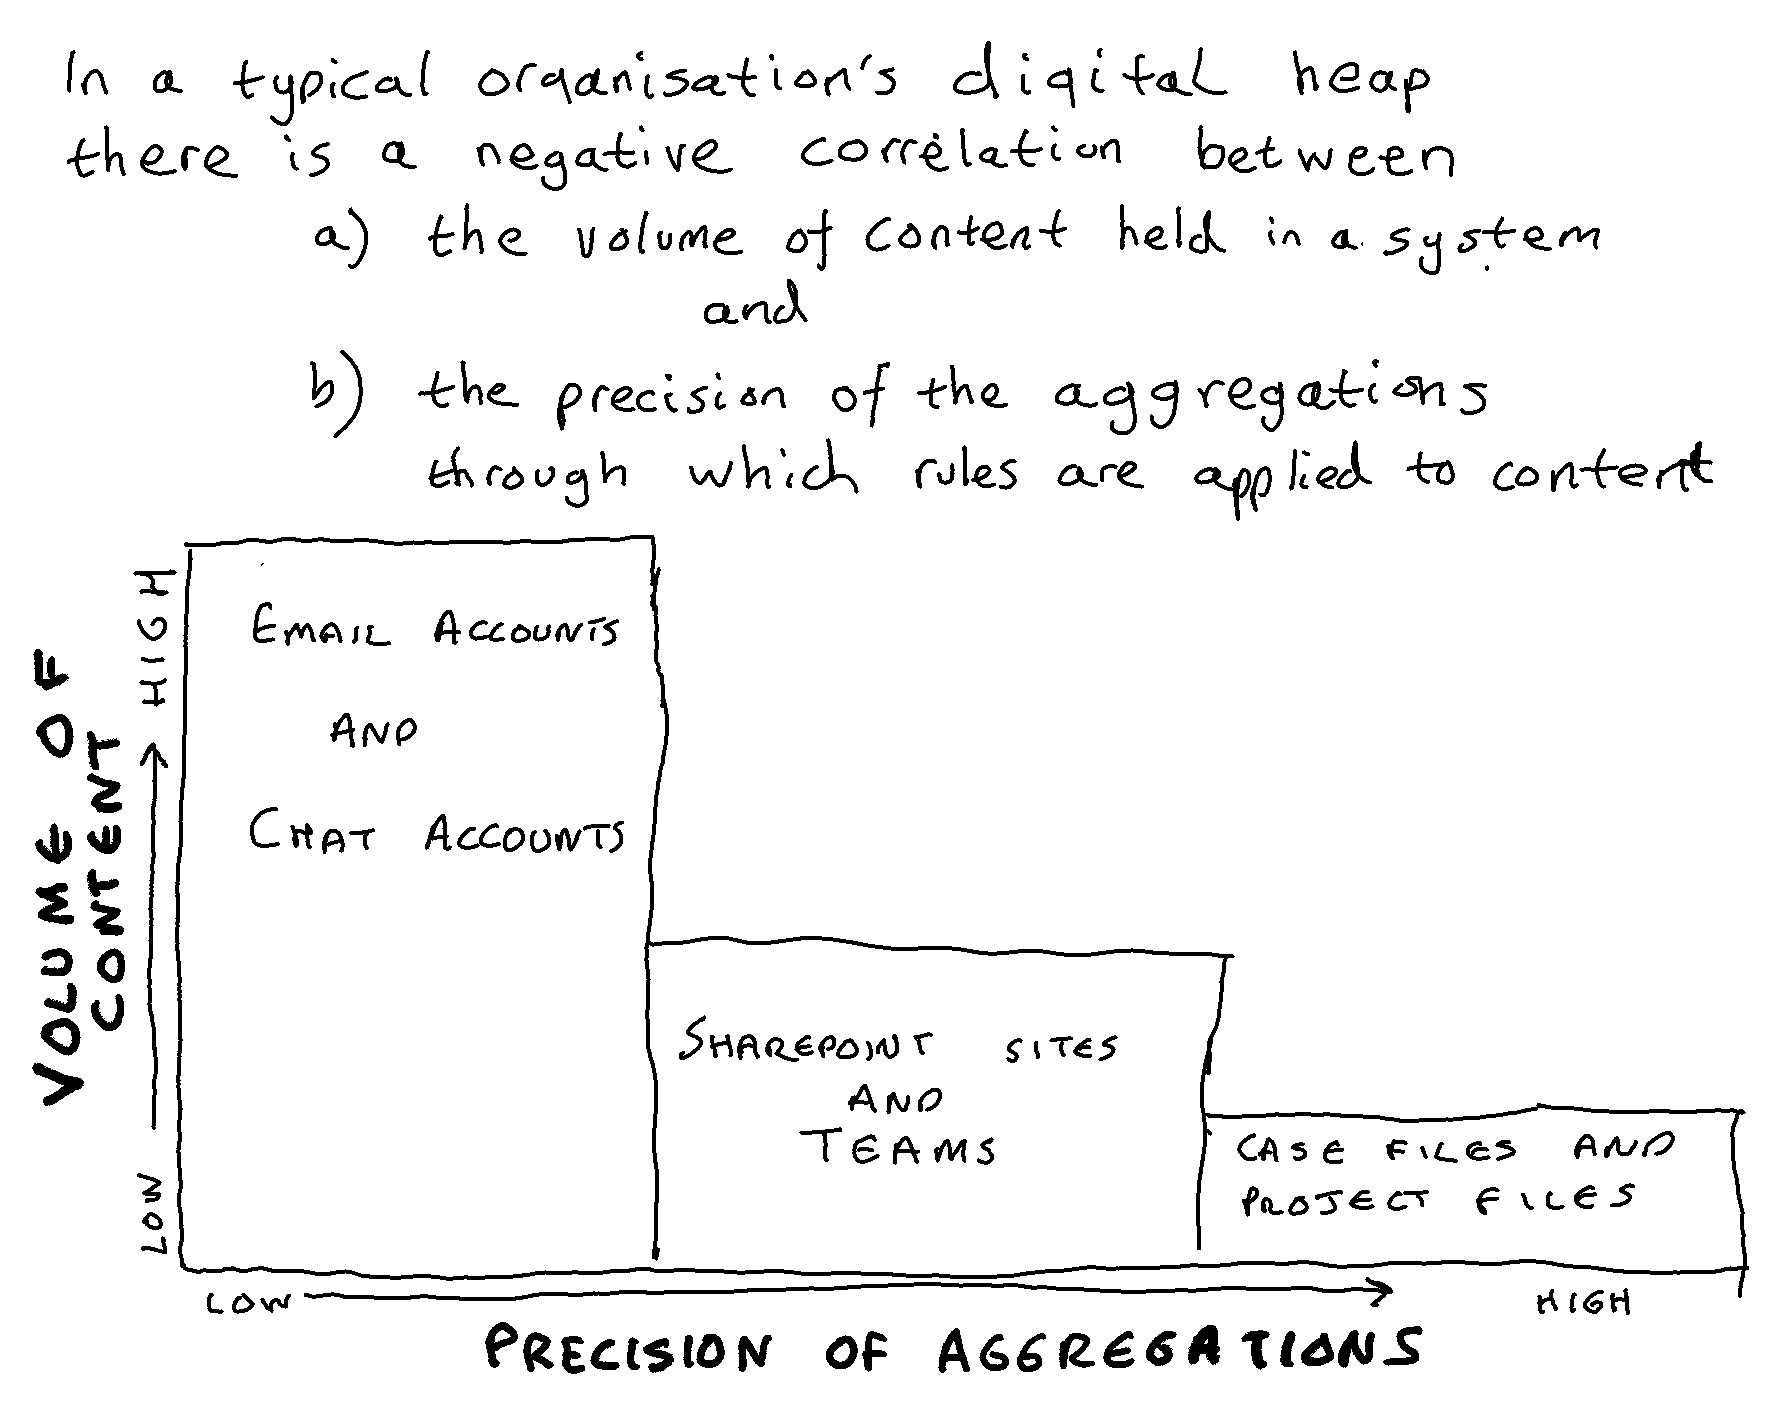
  • Its main weakness is that those aggregations (individual accounts and team sites/spaces) tend to cover a broad range of activities. Individual accounts may contain trivial, social and personal material alongside business content. 

About the AI models specified in the set of requirements

The set of requirements set out below aims to build on the strengths and mitigate the weaknesses of the role-based retention approach. It does so by requesting AI models that work to:

  • Identify trivial, personal, and social items within individual accounts that have no need to be protected by retention policies;
  • Cluster together (via a common tag) material within an individual account that arises from the same business activity.

It is likely that social, trivial and personal content will manifest itself in different ways, and have different give-away features, in the different applications of the Microsoft 365 suite.  The aggregations in the suite likely to have the most such material are individual accounts within Exchange/Outlook, OneDrive, and Teams Chat. The set of requirements therefore specifies a different model for each of these applications. This gives Microsoft the option of asking the different product groups responsible for these applications to each develop an AI model to identify social, trivial and personal material within individual accounts within that application.

Similarly it is individual accounts that are most likely to benefit from a facility to cluster content arising from the same type of business activity. Again the features of content arising from a similar activity are likely to manifest themselves differently in each different application, so a separate requirement has been arrived at for Exchange/Outlook, for Teams Chat and for OneDrive.

About this set of requirements

What follows is a set of requirements that I drafted, in the context of my work at the UK Central Digital and Data Office, and in discussion with colleagues in the UK National Archives (TNA),  the US National Archives and Records Administration (NARA), and the Public Record Office of Victoria (PROV).

The list of requirements reproduced below comes with two caveats:

  • It does not constitute a standard. Role based retention is one approach to records retention.  Other approaches to retention exist.
  • This is a set of feature requests to a technology company. It does not constitute advice, guidance or recommendations to organisations who use Microsoft 365. Organisations need to decide for themselves which approach to retention to apply to which applications within Microsoft 365, on the basis of their business context and on how those applications are used by their staff. 

The set of requirements covers the main workloads of Microsoft 365:  Exchange/Outlook (email); SharePoint and OneDrive; Teams and Teams Chat. It attempts to answer the question as to what features and AI models would best support the application of a role-based retention policy in each of these applications/workloads.  In practice those organisations that apply a role based retention policy are likely to pick and choose which applications they will apply it to. The presence of requirements for functionality to support role-based retention within a particular application/workload should not be interpreted as a recommendation that organisations apply the approach within the workload – that is a decision for each organisation.

The remainder of this post reproduces the set of requirements that was submitted to Microsoft by the IRMS Microsoft 365 CAB working group.

0.Introduction

0.1 About role-based records retention

The role-based approach to records retention is an attempt to generalise out the Capstone approach to email so that it has the potential to be applicable across any system/application that aggregates content by individual or team. The Capstone approach to email was developed by the US National Archives and Records Administration (NARA) in 2013.

A role-based approach to retention assigns individual and/or team based aggregations to a short, medium or long term retention band on the basis of the relative importance of the role of the individual or team that own it.

Role-based retention is one approach to records retention. Other approaches to retention exist. This requirements list does not attempt to recommend or mandate the approach, rather it attempts to list the features and algorithmic models that would make it possible for an organisation, if it so wished, to apply the approach in one, two, several or all of the main workloads of Microsoft 365.

0.2 About this requirements list

This document was developed by the UK Central Digital and Data Office (CDDO), in conversation with the UK National Archives (TNA), the US National Archives and Records Administration (NARA), and the Public Record Office Victoria (PROV). It was developed with a view to feed into discussions of the Information and Records Management Society (IRMS) IM Tech group, and of the group’s working group for the M365 Customer Advisory Board that is run by Microsoft with the IRMS.  

This set of requirements seeks to:

  • Increase understanding of the role-based approach to retention and what it entails in practice;
  • Prompt debate about how role-based retention can best be supported inside Microsoft 365;
  • Set out the features and algorithmic models that would support an organisation in applying role-based retention across the major applications within M365; 
  • Provide a basis for advocacy and dialogue with Microsoft and its ecosystem. 

However, this set of requirements: 

  • Does not represent the policy approach of any actual organisation; 
  • Is not intended to express the policy position of any of the contributors to this document; 
  • Does not constitute records management advice to any organisation.

1. Retention bands

One way of streamlining the deployment of a role-based retention approach is to assign each individual (and each team or working group) to a retention band. This is in order to enable each individual account (and/or each team site) to inherit the retention rule applying to the band that the individual (or team) has been assigned to.

Requirements

1.1Provision of the ability for an administrator to set up three or more retention bands, each with a default retention rule.
1.2aProvision of the ability for an administrator to allocate any, several or every individual end-user to one of the retention bands.
1.2b Provision of the ability for an administrator to allocate any, several or every organisational unit/working group to one of the retention bands.
1.3 Provision of the ability for an administrator to access a central record of which individuals and which organisational units have been allocated to which retention band (and between what dates).
1.4 Provision of the ability for an administrator to move an individual from one band to another if they take on a new role which merits a different retention band.
1.5Provision of a mechanism whereby the change of an individual from one retention band to another (for example after they take on a new role with a very different level of responsibility) results in any content created or received by them in any of their individual accounts from that point in time onwards receiving the default retention rule inherited from their new band.
1.6Provision of the ability for an individual end-user to access information about what retention band they have been assigned to, and about what retention band the organisational unit(s) they belong to has been assigned to.
1.7Provision of the ability for an administrator to configure the dynamic assignment of individuals to retention bands on the basis of properties in their Active Directory profile.

2. Allocating default retention policies to containers

Role-based retention involves the assignement of a default retention rule to an aggregation (container) based on the business content within the aggregation. The default rule reflects how long the business content within that aggregation is likely to be of value to the organisation (for operational and/or accountability purposes).

Requirements

2.1Provision of a mechanism to ensure that each individual account inherits the default retention policy that applies to the band that the individual has been assigned to.
2.2 Ability for an administrator to exempt a particular individual account (or set of individual accounts) from inheriting its retention policy from the band to which the individual has been allocated.
2.3Provision of a mechanism to ensure that each team collaboration site inherits the default retention policy from the band to which the organisational unit mainly responsible for it has been allocated.
2.4Provision of the ability for an administrator to exempt a particular collaboration site (or set of collaboration sites) from inheriting its retention policy from the band to which the organisational unit mainly responsible for it has been allocated.
2.5Provision of a mechanism to ensure that the retention policy inherited by an individual account (see 2.1) or a collaboration space (see 2.3) from the band that it has been assigned to cannot be overriden by any other retention policy applying to the container unless an administrator first allows the inheritance to be broken.
2.6Provision of the ability for an individual end-user to view the retention policy applying to each of their individual accounts.
2.7Provision of the ability for an individual end-user to view, for each collaborative site to which they have access, which retention policy applies to that site.
2.8Provision of the ability for an administrator to view a list of all individual accounts that have been exempted (under 2.2) from inheriting its retention policy from the band that the individual has been allocated to.
2.9Provision of the ability for an administrator to view a list of all collaborative sites that have been exempted (under 2.4) from inheriting a retention policy from the retention band that the individual/organisational unit mainly responsible for it has been allocated to.
2.10Provision of the ability for an administrator to prevent any messages within an individual end-user’s Chat account from being acted upon by a retention policy or retention label originating from the account of a party with whom they have been in conversation.

3 Using retention labels to override default policies

An organisation deploying a role-based retention approach would benefit from the capability to identify material within an individual account (or team site) that does not warrant being retained as long as the business content of the individual (or team/working group). They would benefit from the capability to assign a retention period to such content that is shorter than the default for the account/site, and to have that shorter retention period override the default retention policy for the account/site.

Requirements

3.1Provision of the ability for an administrator to define, for any particular container, any particular set of containers, and/or any particular type of containers, which retention labels (if any) are permitted to override the retention policy applying to that/those containers.
3.2Provision of the ability for an administrator to prevent a retention label from overriding a retention policy set on a container, or on a defined set of containers, or on a type of containers, unless an administrator had configured the container (as per 3.1) to specifically allow its retention policy to be overriden by that label.
3.3Provision of the ability for an administrator to configure a container, a set of containers and/or a defined type of containers to permit a particular retention label to always override the default retention policy.
3.4Provision of the ability for an individual end-user to view, for each of their individual accounts, which retention labels (if any) can override the retention policy applying to the account.
3.5Provision of the ability for an individual end-user to to view, for each collaborative site to which they have access, which retention labels (if any) can override the retention policy on the site.

4. Identifying trivial content within individual accounts

4.1 Identifying trivial content within email accounts

An organisation applying a role based approach to email would benefit from being able to identify trivial, personal, social and unsolicited emails that do not warrant being retained for as long as the business correspondence within the email account of each individual.  For such messages the organisation would benefit from being able to override the default retention policy assigned to the email account with a shorter retention rule applied via a label.  Such an organisation might also seek to find a pathway to enable an individual new-to-post (and any generative AI acting on their behalf) to access the business correspondence in their predecessor-in-post’s email account, with the permission of the outgoing post-holder, and without access being provided to any personal or social emails.

Requirements

4.1.1Provision of the ability for an administrator to automatically assign a retention label to all emails within an email account that the Focused Inbox algorithmic model assigns to the ‘Other’ tab.
4.1.2Provision of an algorithmic model that runs over content within an email account that has been assigned to the ‘Focused’ tab, and makes a distinction between: 
– correspondence that has arisen from the individual’s social/personal life;
– correspondence that has arisen from the account holder’s business role.
4.1.3Provision of the ability for an administrator to automatically assign a retention label to all messages identified as social or personal by the algorithmic model specified in 4.1.2.
4.1.4Provision of the ability for an end-user to correct, reinforce and/or retrain any AI model developed and deployed within their email account in fulfillment of requirement 4.1.2.
4.1.5Provision of a means for an individual end-user to proactively flag up content within their account that is personal to them. 
4.1.6Provision of a means for an individual end-user to indicate that they are happy for a successor-in-post (and any generative AI model acting on their successor-in-post’s behalf) to see correspondence that has been identified (by the model specified in 4.1.2) as arising from their business role.

4.2 Identifying trivial content within Teams Chat accounts

An organisation applying a role based approach to Teams Chat would benefit from being able to identify conversations that do not warrant being retained for as long as the business conversations within the account of the individual.  For such conversations the organisation would also benefit from being able to override the default retention policy assigned to the Chat account with a shorter retention rule applied via a label. Such an organisation might also seek to find a pathway to enable an individual new-to-post (and any Copilot generative AI acting on their behalf) to access the business conversations in their predecessor-in-post’s Chat account, with the permission of the outgoing post-holder, and without access being provided to any personal or social conversations.

Requirements

4.2.1Provision of a means for an individual end-user to proactively flag conversations within their Teams Chat account that are predominantly personal.
4.2.2Provision of an algorithmic model that identifies (and tags or labels) conservations that the individual did not contribute to (for example Chat conversations in meetings that an individual attended).
4.2.3Provision of an algorithmic model that labels each conversation within an individual’s Chat account according to whether it is predominantly a business conversation or predominantly non-business [trivial, business, social or personal].
4.2.4Provision of a means for an administrator to ensure that conversations within a Chat account that are flagged as not relating to the individual’s business role are assigned a shorter retention period than the default assigned to the account. 

4.3 Identifying trivial content within OneDrive accounts

An organisation applying a role-based approach to OneDrive would benefit from being able to identify documents that do not warrant being retained for as long as the business documents created by the individual. Such documents include trivial documents and documents that the individual has not shared with any colleagues. Such an organisation might also seek to find a pathway to enable an individual new-to-post (and any Copilot generative AI acting on their behalf) to access the business documents in their predecessor’s OneDrive account, and that have been shared with their predecessor. This would be dependent on the predecessor-in-post granting permission, and on access being denied to personal, social and trivial documents.

Requirements

4.3.1Provision of the ability to identify documents/content within the OneDrive account that have not been shared with others (by direct sharing with others, or as attachments to messages, or as Loop components, or by any other means).
4.3.2Provision of the ability for an administrator to apply a retention rule to documents within a OneDrive account that have not been shared with others that is shorter than the default for the account.
4.3.3Provision of the ability for an individual end-user to proactively flag up documents that are predominantly social, personal or trivial.
4.3.4Provision of an algorithmic model that labels each document within a OneDrive account as being predominantly business or as predominantly non-business [trivial, social or personal].
4.3.5Provision of a means for an administrator to ensure that documents within a OneDrive account that are flagged as not relating to the individual’s business role are assigned a shorter retention period than the default assigned to the account.

5 Clustering correspondence within individual accounts

5.1 Clustering correspondence within individual email accounts

An organisation deploying a role based retention approach to email would stand to benefit from an algorithmic capability to cluster together (for example by assigning a common tag) items of correspondence within an email account that have arisen from the same business activity. This would enable an organisation to apply different retention rules to correspondence arising from different activities of the individual. It would also open up the possibility of an end-user allowing their successor (and any Copilot generative AI working on their successor’s behalf ) to access correspondence from some aspects of their activities (but not others).

Requirements

5.1.0Provision of an algorithmic model to create clusters within each email account of correspondence that has arisen from a similar business activity. The model would identify messages that arose from similar areas of work and assign them a common tag.
5.1.1Provision of a means for an end-user to rename a cluster created within their email account.
5.1.2Provision of a means for an individual end-user to indicate whether a cluster created within their email account by the algorithmic model specified by 5.1.0 was useful (or not) to them.
5.1.3Provision of a means for an individual end-user to re-assign messages from one cluster within their email account to another.
5.1.4Provision of a means for an individual end-user to add an item to a cluster within their email account.
5.1.5Provision of a means for an individual end-user to remove an item from a cluster within their email account.
5.1.6Provision of a means for an individual end-user to indicate whether they are happy for an administrator to know of the existence of a cluster within their email account.
5.1.7Provision of a means for an individual end-user to indicate to an administrator whether they are happy for a successor-in-post (and any generative AI model acting on behalf on their successor’s behalf) to access a cluster of correspondence created within their email account.
5.1.8Provision of a means for an administrator to provide a person new-in-post (and any generative AI model acting on their behalf) access to a cluster of correspondence from their predecessor, providing that their predecessor had confirmed their consent (as specified by 5.1.7).
5.1.9Provision of a means for an administrator to assign a retention label to a cluster created within an email account by the algorithmic model specified by 5.1.0.

5.2 Clustering correspondence within Teams Chat accounts

An organisation deploying a role based retention approach to Teams Chat would stand to benefit from an algorithmic capability to cluster together (for example by assigning a common tag) conversations within a Chat account that have arisen from the same business activity. This would enable an organisation to apply different retention rules to conversations arising from different activities of the individual. It would also open up the possibility of an end-user allowing their successor-in-post (and any Copilot generative AI working on their behalf) to access conversations from some aspects of their activities (but not others).

Requirements

5.2.0Provision of an algorithmic model running within each individual Teams Chat account, that could identify conversations that arose from similar areas of work and assign them a common tag or label, to create a ‘cluster’.
5.2.1Provision of a means for an individual end-user to rename a cluster that was created within their Teams Chat account.
5.2.2Provision of the means for an individual end-user to indicate whether a cluster created in their Teams Chat account was useful (or not) to them.
5.2.3Provision of a means for an individual end-user to re-assign conversations within their Teams Chat account from one cluster to another.
5.2.4Provision of a means for an individual end-user to add a conversation to a cluster in their Teams Chat account .
5.2.5Provision of a means for an individual to remove a conversation from a cluster in their Teams Chat account.
5.2.6Provision of a means for an end-user to indicate whether they are happy for an administrator to know of the existence of a cluster within their Teams Chat account and to see the title of that cluster.
5.2.7Provision of a means for an individual end-user to indicate whether they are happy for a successor in post (and any generative AI model within Microsoft 365 acting on their successor-in-post’s behalfI) to access a cluster of conversations within their Teams Chat account.
5.2.8Provision of a means for an administrator to allow a successor-in-post (and any generative AI acting on their behalf)  to have access to a cluster of conversations from their predecessor, providing that their predecessor had confirmed their consent (as specified by 5.2.7).
5.2.9Provision of a means for an administrator to assign a retention label to a cluster of conversations created within a Chat account by the algorithmic model specified by 5.2.0.

5.3 Clustering documents within a OneDrive account

An organisation deploying a role based retention approach to OneDrive may stand to benefit from an algorithmic capability to cluster together (for example by assigning a common tag) documents within a One Drive account that have arisen from the same business activity. This would enable an organisation to apply different retention rules to documents arising from different activities of the individual.  It would also open up the possibility of an end-user allowing their successor (and any generative AI model working within Microsoft 365 on their successor’s behalf) to access documents from some aspects of their activities (but not others).

Requirements

5.3.0Provision of an algorithmic model running within each individual OneDrive account, that could identify documents that arose from similar areas of work and assign them a common tag or label, to create a ‘cluster’.
5.3.1Provision of a means for an individual end-user to rename a cluster within their OneDrive account.
5.3.2Provision of the means for an individual end-user to indicate whether a cluster within their OneDrive account is useful (or not) to them.
5.3.3Provision of a means for an individual end-user to re-assign documents within their OneDrive account from one cluster to another.
5.3.4Provision of a means for an individual end-user to remove a document from a cluster within their OneDrive account.
5.3.5Number not used.
5.3.6Provision of a means for an individual end-user to indicate whether they are happy for an administrator to know of the existence of a cluster within their OneDrive account and to see the title of that cluster.
5.3.7Provision of a means for an individual end-user to indicate whether they are happy for a successor-in-post (and any generative AI model acting on their successor-in-post’s behalf) to see a cluster of documents within the OneDrive account.
5.3.8Provision of a means for an administrator to allow a successor-in-post (and any generative AI acting on their behalf) to access a cluster of documents from their predecessor, providing that their predecessor had confirmed their consent (see 5.3.7).
5.3.9Provision of a means for an administrator to assign a retention label to a cluster of documents within a OneDrive account.

6 Preserving the connection between messages and any attachments

6.1 Preserving the connection between Teams Chat messages and any attachments

Where a Chat message is sent with a document attachment, the message forms an important part of the metadata of the document and the document forms an important part of the content of the message. An organisation applying a role-based approach to the retention of Teams Chat messages would need a way to ensure that any message stayed linked to a document attached to it, even if the message and document were stored in separate repositories.

Requirements

6.1.1Provision of a means of ensuring that there is a persistent connection between chat messages and any documents that were exchanged within them.
6.1.2Provision of a location for the storage of an individual’s chat correspondence if and when an administrator decided to no longer retain their Exchange email account (whether for reasons of not having to continue to pay the licence fee or other reasons).
6.1.3Provision of a means for an administrator to treat an individual’s chat conversations and any attachments posted within them as one aggregation for retention purposes. There must be a way of maintaining the link between chat messages (stored in a hidden folder associated an individual’s email account) and any documents exchanged via Teams Chat, even after an individual has left the organisation and even if an organisation has moved the chat correspondence to a new location and/or disabled the email account it was formerly stored in.
6.1.4Provision of a means of ensuring that, if an individual’s Teams Chat account is subject to a longer retention period than their OneDrive account, then the folder of documents within their OneDrive account that contains documents they have sent via Teams Chat is not destroyed for as long as the Chat account is retained.

6.2 Connection between Teams channel posts and attachments

Where a Teams channel posting contains a document attachment, the post forms an important part of the metadata of the document and the document forms an important part of the content of the post. An organisation applying a role-based approach to the retention of Teams would need a way to ensure that any post stayed linked to a document attached to it, even if the post and document were stored in separate repositories.

Requirements

6.2.1Provision of  a means of ensuring that a persistent connection is maintained between documents (stored in SharePoint) that have been posted through standard channels, private channels and shared channels, and the channels that they were posted through.
6.2.2Provision of a means of ensuring that if a SharePoint site is hosting documents that have been posted through Teams channels, that the documents are retained for as long as the channel posts are retained. 

7 Decoupling the storage of email from licence costs

When an individual leaves post the organisation is likely to wish to decommission their email address, but may need to retain their email correspondence.

Requirements

7.1.1Provision of a way of deactivating an email account that:
– Leaves open the possibility that it will be possible to make parts of the content accessible (with the individual’s permission) to their successor-in-post and their successor-in-post’s generative AI;
– Does not incur a licence fee;
– Does not require content to be manually moved.

The impact of Copilot on records management: some predictions

Copilot is Microsoft’s branding for the way they plan to enhance end-user productivity by making generative AI capabilities available in all their offerings, including Microsoft 365. The M365 Copilot is currently in its Early Access phase which means a select group of organisations already have access to it. No date has been fixed for its general availability but Microsoft are unlikely to want to delay it too long.

The impact of generative AI on records management will be felt from the moment an end-user can go to the Copilot Business chat feature within their Teams Chat client within Microsoft 365 and obtain a useful answer to the following prompt:

give me a timeline of all documents and messages arising from insert name of project. Summarise each document and each message thread and provide a link to the sources.

Copilot will search for the answer to such a prompt across all the information that the individual has access to within the tenancy. It will not matter to Copilot where the information is stored. What will matter is the access permissions on that content. Copilot will only return to an end-user information that they already have access to.

From the point at which Copilot returns good answers to this question there is even less incentive for an individual to move messages and documents out of their individual accounts (such as their email account, Chat account and OneDrive account) into shared spaces like SharePoint libraries and Team Channels. They may feel able to use their Copilot to pull together content scattered across different applications and to find content buried in accumulations of email/chat.

Any attempt to shift end-user behaviour to do more work outside of individual accounts or to move content out of individual accounts will face an uphill struggle because Copilot will reinforce rather than challenge the behaviour of working and storing content in individual accounts.

As Copilot gains in strength a key records management task will be to build pathways to ensure continuity of access to business correspondence and documentation held in individual accounts as staff move post or leave employment. A person new-to-post does not have access to content in their predecessor’s individual accounts. Neither will the Copilot acting on their behalf. The Copilot of a person new-to-post will have access to considerably less content than their predecessor did, because it will take time for them to build up accumulations of correspondence and documentation in their individual accounts.

Short term adaptations to the problem of unequal access to information

It is possible to predict some short-term adaptations that teams and individuals may make to address this unequal access to content. For example if an individual is about to leave post, then their manager might ask them to:

  • run a Business Chat Copilot prompt for each of the main projects/cases/matters they had been dealing with, to get a timeline of documents and messages
  • run a Business Chat Copilot prompt for each of the key stakeholder relationships that they had been dealing with to get a timeline of documents and messages
  • make the outputs of the above prompts accessible to their teammates and their successor-in-post.

An individual new-to-post who receives a disappointing response to a Copilot prompt might ask a colleague who has been in post longer (and hence has a longer memory in their individual accounts) to run the same prompt and send them the answer.

A pathway to support continuity of access to business content in individual accounts

The above adaptations are unsatisfactory because they are ad-hoc and haphazard. Records management works better when it is routine and comprehensive. A better approach would be for AI models to run within individual accounts to make distinctions that make it as easy and safe as possible for an end-user to grant access to named individuals (and their successor-in post) to sections of their email/chat/OneDrive content.

In the email environment Microsoft 365 already provides a focused inbox feature that relegates unsolicited emails to a secondary ‘other’ tab. It would be beneficial if that feature could be extended to make a further distinction within ‘focused’ email, that separates out ‘business’ email from ‘personal’ or ‘social’ email. This would enable an organisation to ask individuals if they were willing to grant access to their successor-in-post (and their successor-in-post’s Copilot) to the emails marked as ‘business’.

The more fine-grained the distinctions that AI models can make within individual email accounts the better. If an AI model could make distinctions within the emails marked ‘business’, to cluster together the emails arising from particular pieces of work, then:

  • it would support end-user productivity (for example by supporting a Copilot prompt focused on one particular cluster) and
  • it would support pathways for continuity of access by enabling the end-user to grant access for their successor-in-post (and/or a named individual) to emails arising from a specific piece of work, once they were satisfied that the AI model was assigning items to the cluster in a predictable and precise manner.

Note that such a clustering model would not require the organisation to build a records classification. Nor would it require the AI model to learn a records classification. it could be an unsupervised learning model that was able to recognise the features (in terms of commonality of vocabulary, commonality of attachments, and/or commonality of participants to the messages) that meant that certain emails were likely to have arisen from the same piece of work.

Note also that such clusters would not do away with the need or value of having a records classification. An obvious next step would be a capability to allow an end-user and/or an administrator to link particular clusters within their email account to a records classification.

The direction of travel of Microsoft 365

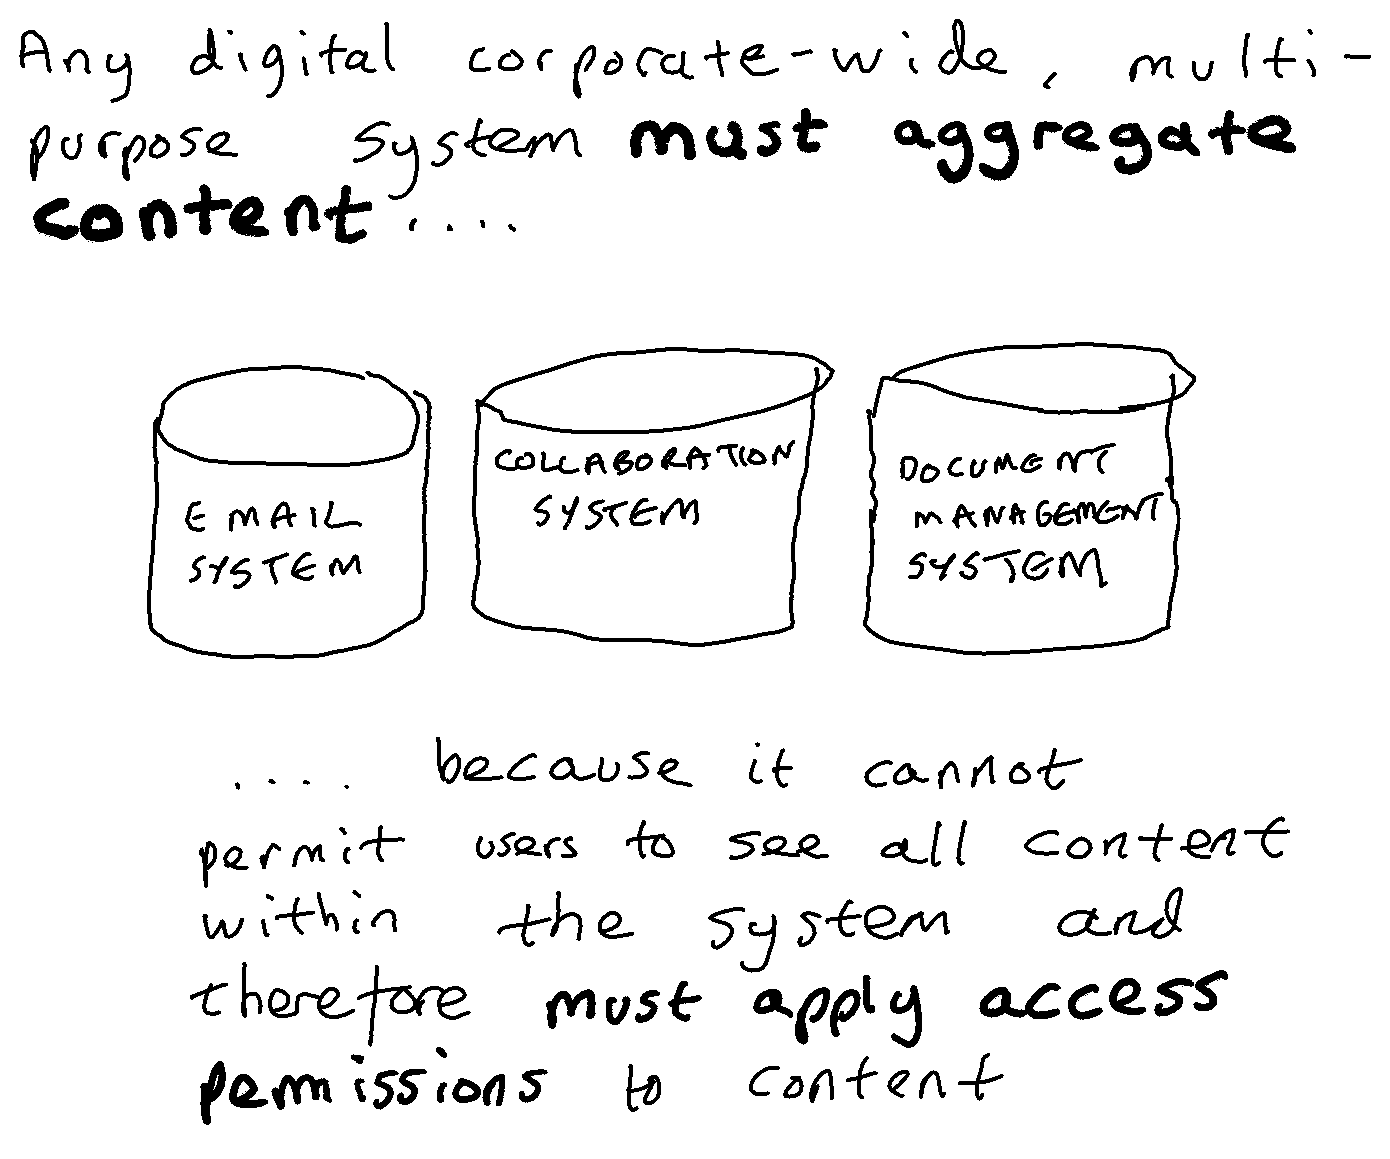
The Microsoft 365 cloud suite is a set of corporate multi-purpose applications:

  • an email system (Exchange);
  • a document management system (SharePoint);
  • a collaboration system (Teams);
  • an instant messaging application (Teams Chat);
  • a filesharing application (OneDrive); and
  • an enterprise social application (Yammer/Viva Engage).

Various common services are wrapped around these applications. These include services that provide means of securing, governing, and searching content held within those applications. 

Microsoft will have an implicit strategy as to how the applications within their suite relate to each other, what they envisage them being used for, what they envisage them storing, and how access and retention rules get applied to content created or received within them. 

Many of the tenant organisations that use Microsoft 365 will have their own records management strategy. Each such strategy will express the organisation’s choices and preferences about how different digital applications relate to each other, what they should be used for, what should be stored in them, and how access and retention rules get applied in them. 

This opens up the possibility that a difference may arise between the records management strategy of a tenant organisation and the broad direction of travel of the Microsoft 365 suite. This raises the question as to the extent to which a tenant organisation’s records management strategy needs to take account of Microsoft’s direction of travel for M365.

The ‘evergreen’ nature of Microsoft 365

Microsoft 365 is an ‘evergreen’ cloud suite. Microsoft introduces a constant stream of new features with the aim of improving the user experience; making users more productive; extending the power of AI models within the suite; and improving the ability of tenants to govern and protect content across the suite. This permanent state of product improvement is essential in order to stay ahead of their competition.

For each set of significant new features introduced by Microsoft into M365 we need to look not just at what those features do, but also at what they say about the direction of travel of M365 as a whole. Each successive new round of features moves M365 further forward along the direction of travel the company has determined for the product. Any difference between a tenant organisation’s records management strategy and Microsoft’s direction of travel will tend therefore to grow over time. Any records management strategy which is significantly different to Microsoft’s direction of travel will, over time, become progressively harder for a tenant organisation to apply within M365.

Let us imagine a tenant organisation that has a high level of information management expertise. Such an organisation might adopt a records management strategy based on:

  • a preference for an application (such as SharePoint) that they can configure with a sophisticated, hierarchical, metadata-rich information architecture;
  • a preference for individuals to work in shared spaces (such as Teams channels and SharePoint sites), rather than in individual accounts (such as Teams Chat accounts, Exchange email accounts and OneDrive accounts);
  • a preference for any important content in Teams Chat, Exchange, or OneDrive to be moved to an appropriate library in the architecture created within SharePoint.

Nothing that Microsoft is going to introduce will make that strategy impossible to pursue. It will remain a defensible approach, and a viable strategy for organisations with very strong information management capabilities. But it is clear that Microsoft’s strategy for M365 is based on a different set of preferences. The overall trend of new features introduced by Microsoft since the birth of the Office 365/M365 suite shows: 

  • a preference for applications (such as Teams and OneDrive) with a flat modular architecture that any organisation can roll out regardless of their level of information management expertise;
  • neutrality as to whether individuals communicate through individual accounts (such as Teams Chat) or shared spaces (such as Teams Channels); 
  • neutrality as to whether content is stored in SharePoint, OneDrive or Exchange;
  • a preference for content to remain in the repository used by the application that it was created in.

One discernable element of the direction of travel of M365 is the establishment of Exchange to act not just as an email system, but also as a general repository for messages created in any new application developed within the suite. SharePoint and OneDrive act as the general repositories for documents created in any new application within the suite. MS Teams was the first new application that Microsoft created within Office 365/M365. It was configured so that it does not store any of the messages and documents that go through it:

  • messages sent through Teams Chat are stored in a hidden folder linked to the email account (in Exchange) of each person participating in the chat. Messages posted to Teams channels are also stored in Exchange, in a hidden folder associated with the shared email account of the M365 Group that is linked with the Team (see this post for more details);
  • documents sent in Teams Chat messages are stored in the OneDrive account of the sender. Documents posted to Teams channels are stored in a library of the SharePoint site associated with the Team (see this post for more details). 

New feature sets in M365

Microsoft are in the process of introducing three potentially important feature sets into M365:

  • Loop allows an individual to create a collaborative shared resource inside a a message within their individual Teams Chat account or email account, and invite others to contribute to it;
  • Copilot is the M365 equivalent of ChatGPT. It aims to make an individual more productive by delivering them information relevant to the content they are creating at a particular point in time. The information is sourced from the total set of information accessible to that individual in any application within the suite;
  • Viva Topics is an AI model that aims to act as a source of reference within M365 for the organisation. It analyses content stored in SharePoint to identify projects/topics that the organisation is working on. It creates a topic card (akin to an intranet page) for each topic, with a description of the project/topic, links to key resources and names of key contacts. That topic card can be made available to individuals when they encounter mention of the topic (or when they themselves mention the topic) in various applications within M365. Like Copilot it is trimmed for access permissions so an individual is only shown information that is already accessible to them in content within the tenancy.

These three new feature sets have nothing directly to do with records management. They have no direct impact on the access permissions and retention rules that are applied to content. But they do give us an indication of the direction of travel of M365 with regard to the relationship between new M365 functionality and existing M365 repositories, and with regard to how AI models will work in the suite. And that overall direction of travel will act over time, to make some types of records management strategy easier to apply within M365 tenancies than others.

Relationship between new feature sets and existing M365 repositories

Microsoft have set the default storage location for items created with Loop to be the OneDrive account of the individual who created the item. At first sight this decision is surprising. Collaboration is about sharing content and working together, whereas OneDrive is based on individual accounts. But on closer inspection Microsoft has no other choice.

Microsoft can safely assume that almost every individual in almost every tenant will have an email account, a Teams Chat account and a OneDrive account. Microsoft can also assume that every new collaboration object will be initially created by an individual. Microsoft can therefore be sure that every new Loop object will have a logical home in the OneDrive account of the creator. Any proliferation of Loop objects will not result in a proliferation of new aggregations because the OneDrive accounts already exist. 

In contrast if Microsoft had wanted Loop content to be stored by default in SharePoint, then they would almost certainly have been forced to spin up a new SharePoint site every time a new Loop object was created for a new combination of users. This is because of the idiosyncrasies of SharePoint’s architecture:

  • every document in SharePoint needs to live in a library;
  • every library needs to live in a site;
  • every site has an owner who has powers over all content in the site;
  • there is no way of knowing whether any given set of people collaborating on a Loop object are happy for that Loop object to come under the control of that particular site owner.

MS Teams is engineered so that a new SharePoint site is spun up for every new Team created, purely in order to house a document library for the Team in the site. In theory Microsoft could have adopted this model for Loop, with a new SharePoint site being spun up for every loop object, but the short lived nature of the collaborations envisaged for Loop would make this disproportionate and undesirable.

The decision to architect M365 to store messages in Exchange and documents in SharePoint/OneDrive has an important consequence. It is relatively straightforward for Microsoft to architect any major new application or feature set to store content in individual accounts (OneDrive accounts and/or individual Exchange email accounts). It is much more complex for Microsoft to architect the new application/feature set to store content in shared spaces (SharePoint document libraries and/or shared Exchange email accounts). Over the course of time this is likely to lead to an increasing portion of content being stored in individual accounts.

How AI models work in M365

Copilot and Viva Topics are different AI models that stand independently of each other. Copilot dredges information from anywhere within the tenancy that the individual has access to. Viva Topics dredges information from anywhere in SharePoint (or rather those parts of SharePoint that administrators have allowed it to trawl). But they have two key architectural feature in common:

  • they are both trying to use AI to make an individual more productive by bringing them knowledge specifically relevant to their context;
  • they both trim their outputs to ensure that every piece of information they present to a particular user is already accessible to them within M365.

We can predict that the more effective the AI models in M365 become, the less it will matter to a user where a particular item of content is stored. What matters is whether they (and by extension their AI models) have permission to view the content.  We can also predict that the more effective the AI models become, the less Microsoft will be concerned about which of the M365 repositories content is stored in.

In effect a new type of aggregation has come into existence as a result of the development of these AI models. That aggregation is the set of content within a tenancy to which a particular user has access to. This aggregation is not visible to anyone except the AI models, but the AI models must know its boundaries otherwise they would not be able to trim the information they are providing to individual users as auto-suggestions, topic cards etc.

Let us assume that Copilot will continue to improve over the course of the next two or three years as it achieves greater adoption and as its algorithms are further refined in the light of that adoption. If this proves to be the case, then Copilot will reach a point at which it enables an individual to benefit significantly from the information they have access to within M365. Some of that information will be held in their individual accounts, the rest will be held in the various shared spaces that they have access to.

At a certain point in time that user will leave their post of employment  A new individual might be appointed to replace them. The new individual is likely to be given access to the shared spaces that their predecessor had access to, but not to the material in their predecessor’s individual accounts. Consequently there will be a drop-off in effectiveness of Copilot for the new person in post. This drop-off will persist until the new person accumulates, over time, a sufficient breadth of relevant content in their own individual accounts.

In order to flatten out this drop-off there may arise a need to develop ways in which an organisation can safely provide a new person in post (and the AI models working on their behalf) with access to the non-personal content held in the individual accounts of their predecessor. In order for that to happen another AI model may be needed, that works within the individual accounts of a user and identifies personal material that the AI model predicts the user would not want to make accessible to their successor-in-post. It is likely that the only person who could act as the human-in-the-loop to monitor, reinforce and retrain such a model, would be each individual end-user themselves.

Such a model could be seen to be successful if and when it reaches the point at which an individual would be willing to freely grant permission for their successor (and by extension their successor’s AI models) to access the material within their individual accounts that the model had not identified to be personal.

Research paper on archival theory and email

The journal Archival Science has published the latest paper from my doctoral research project into archival policy towards email. The paper is entitled ‘Rival records management models in an era of partial automation’. It is an open access paper and is free to read and to download from here.

The paper argues that:

  • the adoption of email in the 1990s brought in an era of partial automation. Email systems could automatically file correspondence, but not into a structure/schema of our choosing;
  • Frank Upward’s records continuum model sees a recordkeeping system as a set of processes that involve the creation, capture, organisation and sharing of records;
  • in an email system the process by which correspondence is captured is optimal. Correspondence is filed instantly according to very predictable and reliable rules. Metadata values are assigned consistently and accurately;
  • the structure and metadata schema of a typical email system is sub-optimal. Correspondence is not linked to the business activity it arose from, and business correspondence is not distinguished from personal, trivial, and social correspondence. This causes difficulties with the management and sharing of records (most notably when an individual leaves post and their successor cannot normally be permitted to access the business correspondence within their email account).

A significant proportion of archival and records management thought over the course of the past quarter of a century has gone into trying to specify what constitutes an optimal structure and metadata schema for a records system.

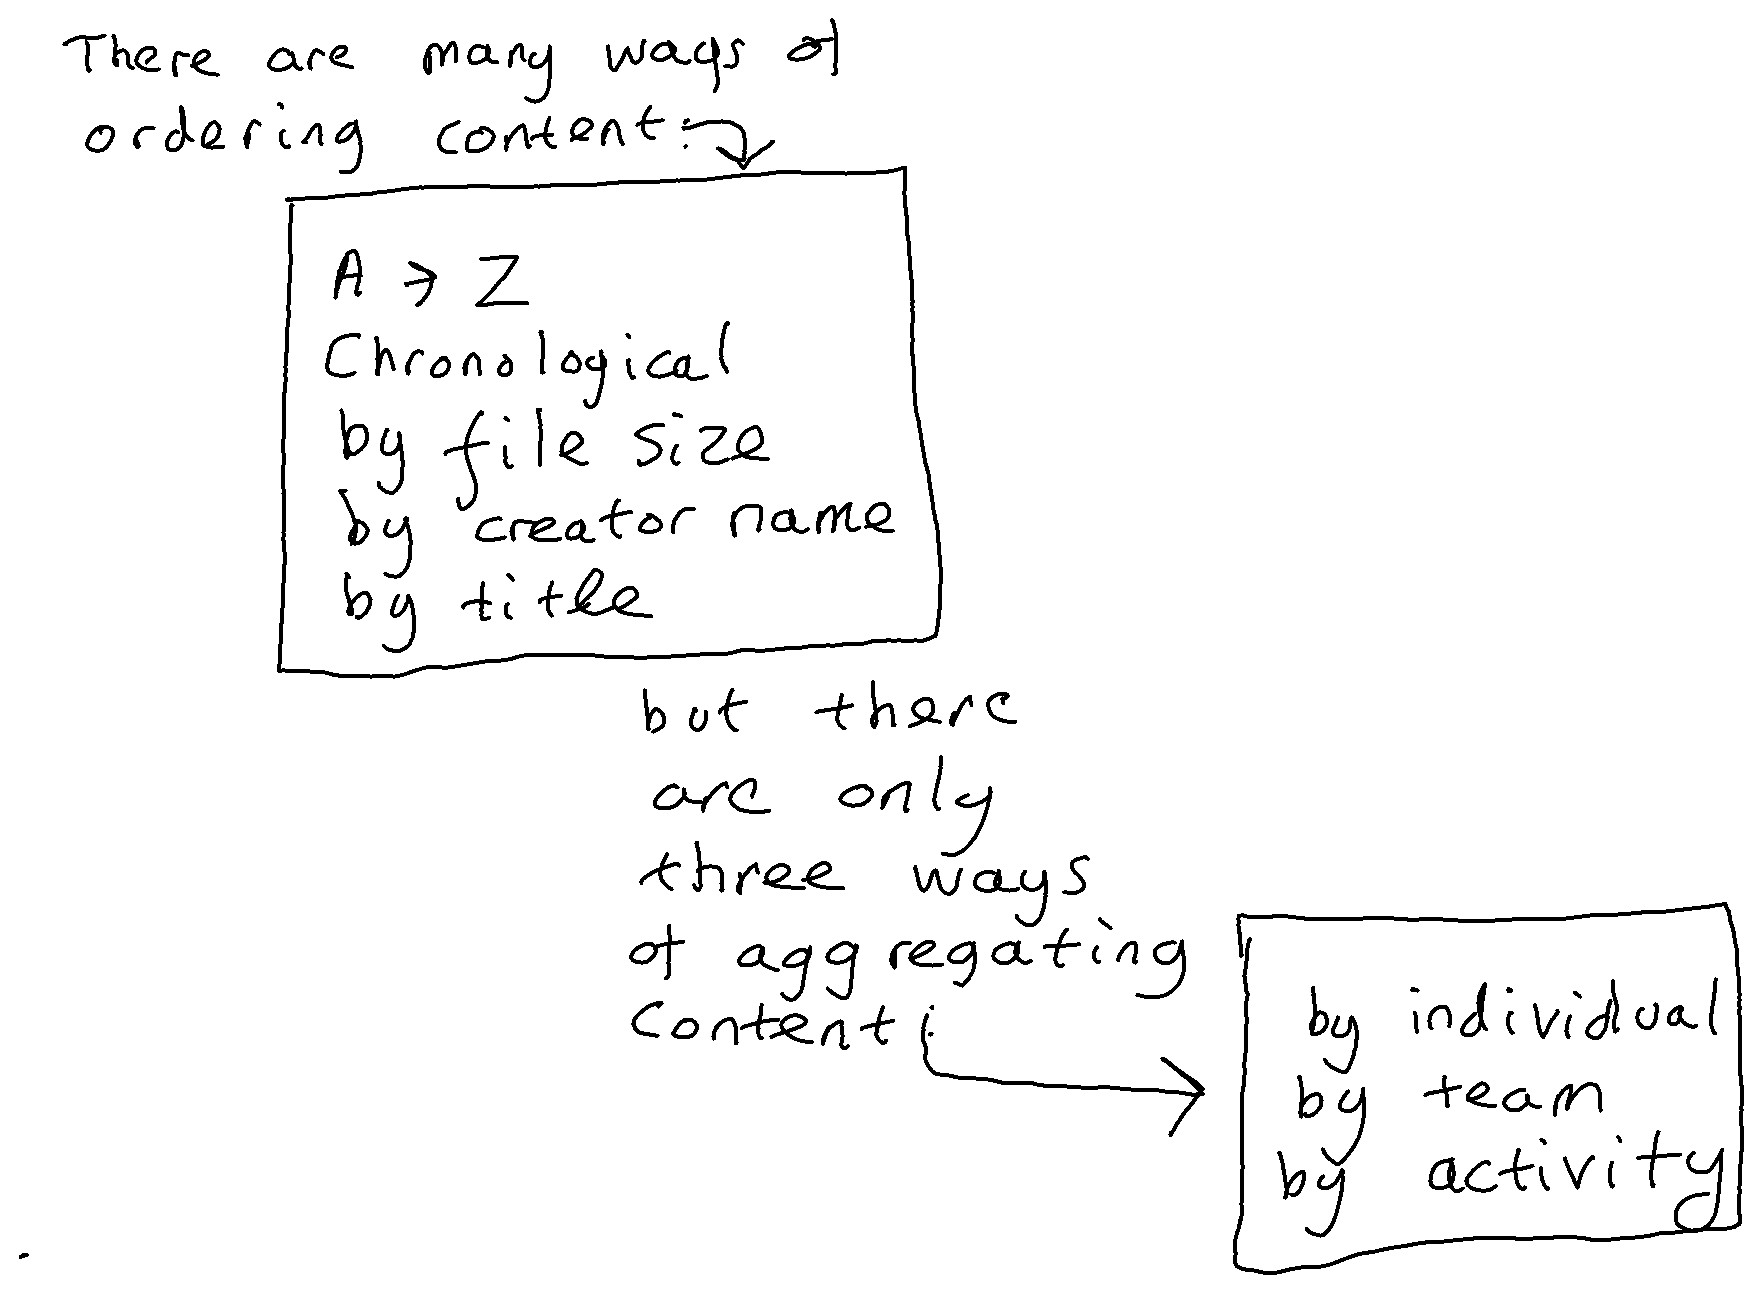
In the era before email, when we did not have the capability to automatically file correspondence, there was a level playing field between different ways of structuring a record system. An organisation had a choice of several ways it could file correspondence (chronologically, alphabetically by correspondent, functionally by business activity). It did not take appreciably more effort for a human to file into any one of these three different structures than into any of the others. It therefore made sense to choose the structure that gives the optimum efficiency in terms of the management and sharing of records through time. This equates to the structure that is most efficient from the point of view of the application of records retention and access rules. Theodore Schellenberg, author of the foundational text on records management, tells us that the most efficient way of organising records is by function and business activity.

The coming of email changed this equation. An email system automatically files all of an organisation’s email correspondence alphabetically and chronologically at the email system level, and all of an individual’s correspondence alphabetically and chronologically at an email account level. There is no longer a level playing field between different ways of structuring a record system. We can automatically and instantly file email correspondence chronologically and alphabetically, but if we want to file it by business activity then that would have to be done manually.

In this era of partial automation we have a paradoxical situation whereby if we were to ask end-users to file email correspondence into an application with an optimal structure/schema (one that organises records by business activity) then we are likely to make the recordkeeping of the organisation less efficient and less reliable. This is because we would be using an unreliable manual process to re-file correspondence that had already been filed automatically and reliably into a sub-optimal structure/schema.

The paper therefore finds a justification within archival theory for approaches that seek to manage correspondence in place within the structure and metadata schema of a native messaging application (for example of an email system) even where that structure/schema is sub-optimal . This justification is valid in circumstances where the native application has automatically and reliably assigned correspondence to that structure/schema, and where the organisation lacks an automatic and reliable means to re-assign correspondence to an alternative (more optimal) structure/schema.

The impact of Microsoft Teams on records management strategies

Every organisation has a records management strategy. Regardless of whether or not they make that strategy explicit in a strategy document, their strategy is implicit in the choices they make about how they go about applying retention rules to the content in their business applications:

  • they might be seeking to try to move documents and messages needed as a record into one business application that is optimised for recordkeeping;
  • they might be seeking to intervene in several, most or all of their business applications so that each of these applications are optimised to manage their own records;
  • they might be seeking to manage records ‘in place’ within the native applications that they arise in, even when an application has a structure and a metadata schema that is sub-optimal for recordkeeping.

Each of these rival strategies has their pros and cons. Each is a legitimate records management approach.

This situation is made more complex by the arrival of the cloud suites from tech giants Microsoft and Google. Each cloud suite is a combination of several different document management, collaboration, filesharing and messaging applications. Each cloud suite embodies an implicit records management strategy. The strategy is discernable by the retention capabilities that the suite is equipped with, and by how those capabilities relate to the applications within the suite. This opens up the possibility that an organisation might be expounding one type of records management strategy, but be deploying a cloud suite that is informed by one of the rival strategies.

It is clear from the way that the Microsoft (Office) 365 cloud suite has been set up that Microsoft have adopted an ‘in place’ approach to records management. In the MS 365 suite no one application is superior for records management purposes than any other. Retention functionality sits in the Compliance centre, outside of any one application. Retention rules can be set in the Compliance centre and applied to any type of aggregation in any of the collaboration/document management/messaging/filesharing applications within the suite.

In the early years of Office 365 it may have been possible for an organisation to deploy the suite whilst continuing with a strategy of moving all documents and messages needed as a record into one specific business application that is optimised for recordkeeping. Since the coming of MS Teams this no longer appears possible.

MS Teams deployed as an organisation’s primary collaboration system

The phenomenal rise in adoption of MS Teams over the past two years is prompting some fundamental changes in the records management strategies of those organisations who have adopted it as their primary collaboration application:

  • prior to the coming of MS Teams an organisation would have been able, if it so wished, to configure their main collaboration system with a records management friendly structure and metadata schema. This kind of ‘records management by design’ is not possible in MS Teams;
  • prior to the coming of MS Teams most large organisations tended to deploy a document management application as their main collaboration system. Microsoft Teams is a messaging application. The organisation has therefore gone from trying to manage messages in a document management application, to trying to manage documents in a messaging tool.

These two changes are related: the reason why MS Teams is not as configurable as previous generations of collaboration systems is precisely because it is primarily a messaging system in which content is pushed to individuals and teams via Chat and Channels.

The impact of MS Teams on an organisation’s records management strategy

Let us think of how the records management strategy of a typical large organisation may have evolved over the past two decades:

  • in the middle of the first decade of this century they may have implemented a corporate electronic document and records management system (EDRMS) and said to their staff ‘if you want a document or a message to be treated as a record, save it into our EDRMS’.
  • near the start of the second decade of the 21st century they may have wanted to introduce a document management system that is more collaborative in nature. They may have replaced their EDRMS with a tool such as Microsoft SharePoint. They might have said to their staff ‘if you want a document or message to be treated as a record, move it into a SharePoint document library’.
  • in 2019 or 2020 they may have rolled out Microsoft Teams, giving every individual a Teams Chat client and every team a Team with a set of channels into which messages and documents can be posted. They may now say to their staff ‘it you have an important document or message then post it through a Team channel’.

Here we have some elements of continuity, but also some important elements of discontinuity.

The main element of continuity is that the organisation is still encouraging staff to contribute every document or message needed as a record to one particular application. They are still making a distinction between:

  • an application that they designate as being a record system (and hence will apply their retention principles and retention rules to);
  • other applications that they do not regard as record systems (and hence do not commit to apply their retention principles and rules to).

The element of discontinuity lies in the nature of the rationale behind this distinction.

When the organisation had implemented an EDRM or SharePoint as its corporate document management system and asked staff to move any documents and messages needed as a record into that system they could argue that they were taking a ‘records management by design’ approach. They will have endeavoured to configure their corporate document management systems with a logical structure that reflects (as best they could) their business processes and to which they will have attempted to link appropriate retention rules and access rules.

They could justify the routine deletion of content in other applications by arguing that the records management by design approach relies on important documents and messages being placed into an application that has records management frameworks configured into it.

MS Teams and the decline of records management by design

For most of the past ten years SharePoint has dominated the market for corporate document management systems and hence dominated the market for systems through which an organisation could apply a records management by design approach.

SharePoint has been on a journey. It started the decade as an on-premise, stand-alone document management system which end users would directly interact with. It ends the decade as a component part in a cloud suite. Its role in that cloud suite is more and more becoming that of a back-end system supplying document management capability to MS Teams.

An organisation that configured SharePoint as their corporate document management system with a carefully designed information architecture will find that structure sidelined and deprecated by the introduction of MS Teams. Each new MS Team is linked to a new SharePoint document library in which all documents posted through its channels will be kept. In effect this brings in a parallel structure of document libraries to rival those previously set up for those same users in SharePoint.

At the time of writing it does not appear possible to do records management by design with Microsoft Teams. The information architecture of MS Teams is not suited for it, and neither is the way that most organisations roll Teams out.

Information architecture of MS Teams

In MS Teams each Team is a silo. There is no overarching structure to organise the Teams. Overarching structures are useful in any sort of collaboration system, not just to serve as a navigation structure for end-users to find content, but also to place each collaboration area into some sort of context to support the ongoing management and retention of its content. There does exist, in the Microsoft 365 Teams Admin Centre, a list of the Teams in the tenancy. This list is only accessible to those who have admin rights in the tenancy. Most organisations give admin rights to only a very small number of people. The list gives an information governance/records management team precious little information about each Team. It gives a basic listing of the name of the team and the number of channels, members, owners and guests it has. (see this recent IRMS podcast with Robert Bath for a fuller discussion of these issues).

Roll out of MS Teams

In the past organisations typically used a staggered roll out to deploy their corporate document management /collaboration system (EDRMS, SharePoint etc.). Such systems would be rolled out tranche by tranche, to give time for the implementation team to configure the specific areas of the system that each team in the tranche was going to use. This was necessary in order to bridge the gaps between the organisation’s broad brush information architecture frameworks and the specific work and specific documentation types of the area concerned.

Microsoft Teams is a primarily a messaging system. It is a communication tool. It gives individuals the ability to send messages to other individuals through their Chat client and to share posts with their close colleagues through a Team channel. Its aim is to speed up communications and to enable colleagues separated in space by remote working to keep closely connected. Organisations may have been happy to stagger the roll out of a document management system but they are not typically happy to stagger the roll out of a messaging system because to do so would exclude some staff from communication flows.

There is a design element to Teams. There are choices to be made as what is the the optimum size for a Team, as to how many different channels to set up in any team, and what to set channels up for. But there are two significant limitations to the scope of these design choices.

The first limitation arises from the fact that the design choices relate to Teams channels, whereas most MS Teams traffic tends to go through Teams Chat. There are no design choices to be made in the implementation of individual Teams Chat clients.

The second limitation arises from the fact that however you design Teams and Teams channels, you cannot overcome the fundamental architectural weakness of Teams, that each Team has to be a silo. This is the key difference between SharePoint/EDRMS systems on the one hand and MS Teams on the other.

The access model in MS Teams

SharePoint is a document management system. The access model for SharePoint sites and document libraries is flexible. You can make the site/library a silo if you wish by restricting access to a a small number of people, but equally you can open up access widely. You can reduce the risk of opening access widely by confining the right to contribute, edit and delete content to a small group whilst opening view access to a wider group.

MS Teams is a messaging system first and foremost with a document management component (provided by SharePoint) as a secondary element.

You can only view content in a given Team if you are a member of a that Team. Each Team member has access to every channel within the team (apart from private channels) and to the Team’s document library. Each Team member can contribute posts to channels and can add and delete items from the document library. Broadening the membership of a Team is therefore more risky than opening up access to a document library in a SharePoint implementation, because everyone that you make a member of the Team has full edit and contribute rights in the Team.

A further disincentive to adding extra members to the Team lies in the fact that by making someone a member of the Team you are exposing the individual to the flow of messages in and out of the channels of that Team. There is a catch-22 here. The more you widen membership of a Team the more you drive message traffic away from Teams channels and into Teams Chat. This is because the wider the membership the greater the likelihood that any given message will be uninteresting, irrelevant or inappropriate for some members. If you keep the membership small you may increase the percentage of traffic going through the channel but you decrease the number of people to whom that traffic is accessible.

Microsoft Teams and the notion of ‘retrospective governance’

The first time I heard the phrase ‘retrospective governance’ was in the chat in the margins of a recent IRMS webinar. An organisation had carried out a corporate wide roll-out of MS Teams out virtually over night in 2019, and the records manager reported having spent the subsequent year trying to put in place some ‘retrospective governance’ by identifying which organisational unit each Team belonged to, what it was being used for, whether it was needed, what retention rule should apply to it. Numerous other participants reported similar experiences.

Retrospective governance is not exclusive to Microsoft Teams. We can for example see retrospective governance in the use of analytics/eDiscovery tools to make and process decisions on legacy file shares (shared drives).

In the past an organisation may have decided to apply retrospective governance to data in legacy applications and repositories, but such retrospective governance efforts were very much peripheral to the main thrust of their records management strategy which was centred on the application into which it had configured its recordkeeping frameworks. After the coming of MS Teams retrospective governance suddenly moves to the heart of an organisation’s records management efforts. The rise of MS Teams means that within the MS 365 suite it is not possible to configure records management frameworks into one application in such a way as to give that application records management primacy over other applications.

The in-place records management strategy

The in place records management approach holds that at the current point in time it is not feasible to consistently move all significant business documents and messages into an application equipped with a structure/schema that is optimised for records management. There also exist many classes of business application (including email systems and all other types of messaging system) whose structure and schema simply cannot be optimised for record keeping. Therefore an organisation’s document management, messaging, filesharing and collaboration applications should be treated as record systems even if the structure and metadata schema of most of these applications is sub-optimal for recordkeeping.

Unless and until it becomes possible either a) to consistently and comprehensively move records into an application that is optimised for recordkeeping, or b) to configure each business application so that it has a structure and schema that is optimal for recordkeeping, then we also need c) a viable strategy for managing records in applications that have a structure and schema that is sub-optimal for recordkeeping.

Dialogue with Microsoft about their execution of the in-place records management strategy

The records management profession has put a tremendous amount of work over the past 25 years into building a knowledge base for the records management approaches that involve optimising one business application for recordkeeping. There is also a small amount of literature about the model where you configure records management frameworks into several, many or all business applications. The profession has put much less work into defining best practice for the in-place records management approach. This is understandable, because it was not our first choice of model. But its absence is especially noticeable in discussions with Microsoft about records management.

The in-place strategy embodied in the MS 365 cloud suite is one in which applications are deployed without any attempt to ensure that the structure and schema of those applications are optimised for recordkeeping. Organisations apply retention rules to the aggregations that naturally occur within those different native applications (email accounts, SharePoint sites, One Drive accounts, Teams Channels, Teams Chat accounts etc.) and ask individuals (or train machines) to identify and label any items that are exceptions to the retention rule set on the aggregation that they are housed in.

We can point Microsoft to a truck load of best practice standards in records management but almost all of it has been written from a point of view that assumes an organisation or a vendor is trying to design records management frameworks into one business application. There is little or no literature on the in-place strategy that Microsoft are trying to implement in their cloud suite. We have nothing against which to judge Microsoft’s execution of the in-place strategy in their suite, and nothing to guide organisations attempting to work with that strategy in their implementation of the suite.

Filling the gap in records management best practice

I am writing this on New Years Day. How about a collective new year’s resolution to start building a knowledge base for the in-place records management strategy? This should prompt us to start thinking through the key considerations involved in managing records across multiple document management, messaging, filesharing and collaboration applications, many of which have structures and schemes that are neither optimised nor optimisable for recordkeeping.

This should supplement but not replace the existing knowledge base we have for the other two main records management strategies.